The theme today is efficiency. Anthropic quietly cut Claude Code's subagent token costs by 99% with a smarter status update trick. OpenAI shipped Images 2.6 with GIFs and generation that's 50% faster. Both labs shipping the same day, both chasing the same thing: doing more with less.
We're past the era of raw capability. The race is now about cost per useful output.
More runway, faster pixels. Not bad for a Tuesday.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Claude Code cuts background subagent token cost by 99% in v2.1.316
|
|
17,480 Likes
|
|
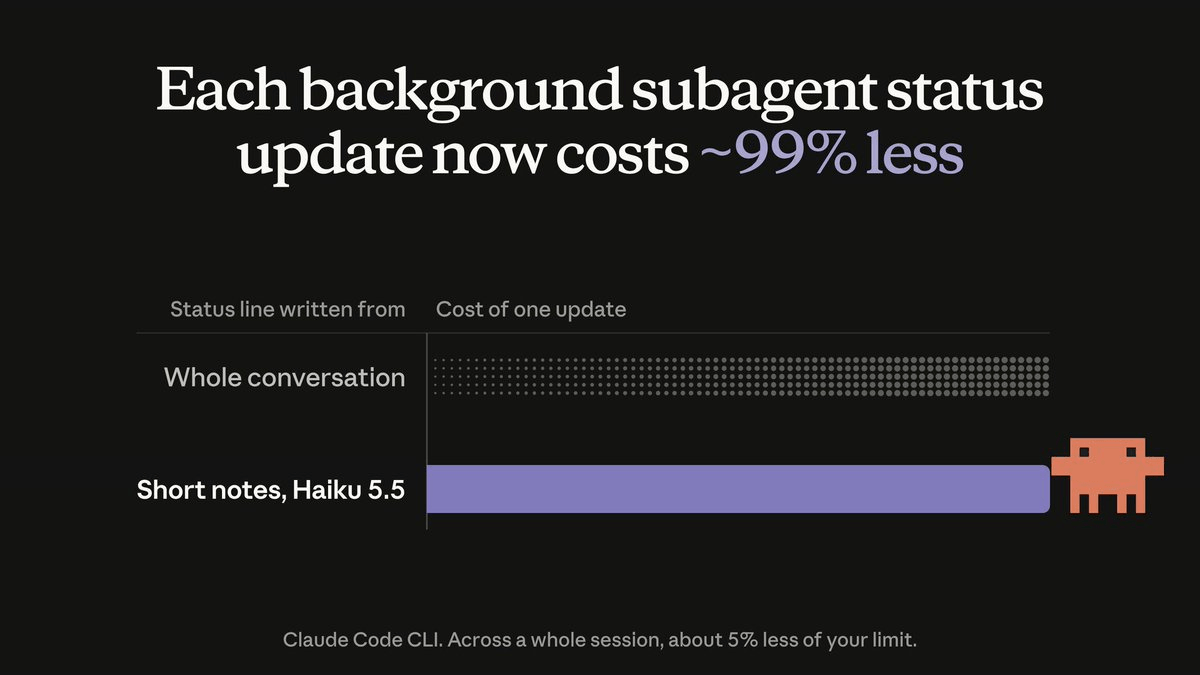
Claude Code just got a quiet but useful fix for background subagents, those helper agents that run tasks in parallel while your main session keeps going. Here is the problem it solved. Every 30 seconds, each background subagent refreshed its status line. To do that, it re-read its entire conversation history each time. That is expensive. The longer the session, the worse it got. Now, Haiku 5.5, a smaller and faster model, writes that status update from short notes instead of the full transcript. The result: each status update costs 99% less to generate. What does that mean for you? More runway on the same plan. - Sessions with background subagents now use about 5% less of your usage limit
- That translates to roughly 6% more prompts before you hit the wall
- No config changes needed, just update to v2.1.316+ with claude update
- Live for Pro, Max, Ultra, Team, and Enterprise users
Small change, real impact, especially if you run long multi-agent sessions.
|
|
|
|
Presented by Unblocked
|
|
A Pile of MCP Connectors Is Not a Context Engine
|
|
Your team connected Slack, Jira and GitHub over MCP, and engineers still spend their time steering agents to the right answer.
Unblocked's benchmark shows why: connectors fetch from one tool at a time, so every agent stitches the pieces together itself, trusts the first doc that looks right, and adds a search to your token bill each time.
Read what changes when a context engine sits on top of your connectors: the same coding task finished 83% faster at 60% lower cost.
|
|
|
|
Top News
|
|
|
|
OpenAI ships ChatGPT Images 2.6 with GIF output and 6-second image generation
|
|
13,311 Likes
|
|
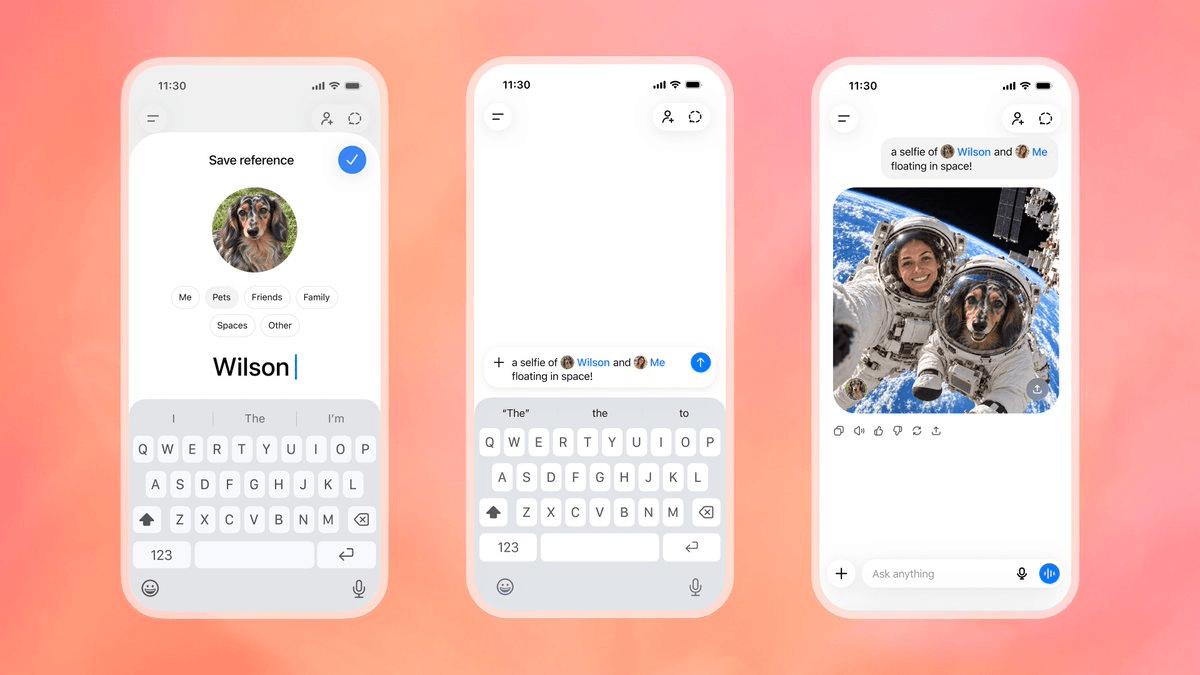
OpenAI just dropped Images 2.6, and it is a solid upgrade worth knowing about. The headline feature: you can now generate animated GIFs from a text prompt or a photo. You can tweak the speed and edit individual frames. The model keeps characters consistent across frames, so animations actually look coherent. The other big addition is reference images. Save a character, a pet, or a product once, and reuse it across future creations without re-uploading anything. Huge for anyone building consistent visual content. On the API side, two models are now available: - Flare (gpt-image-2.6-flare): speed-first, generates in as little as 6 seconds. Great for prototyping and high-volume pipelines.
- Sunburst (gpt-image-2.6-sunburst): higher quality, more consistent edits. Built for polished output.
Both support image markup and SVG export, so you can pinpoint edits and pipe results directly into design workflows. Overall generation is 50% faster than before. Available now in ChatGPT, Codex, and the API.
|
|
|
|
Presented by Buoyant.io
|
|
Make inference count on your GPUs: no token bills
|
|
Every agent and app you ship sends more tokens to a frontier model, and the bill grows with them. Kinference serves that traffic from your own vLLM pods, routing each request to the pod predicted to meet its SLO, with frontier models only by policy. Open-source inference serving for platform teams.
|
|
|
|
Top News
|
|
|
|
Kimi.ai releases Kimi K3.1 Pro model weights to the public
|
|
6,681 Likes
|
|
Moonshot AI just dropped the weights for Kimi K3.1 Pro on Hugging Face, and it's a big deal for anyone who wants a powerful model they can actually run themselves. So what is it exactly? A 2.8 trillion parameter open-weight model with a 1 million token context window, meaning you can feed it an entire codebase at once. It uses a Mixture-of-Experts setup, where only a slice of the model activates per task, keeping it efficient despite the massive size. Here's what it's good at: - Full-project coding in Unreal, Unity, and Godot, plus 3D modeling in Blender and CAD
- Finance work with hallucination down by 65%
- Ranked #1 among open-weight models on Agent Arena, across productivity, coding, and chat
Platforms like Ollama, Nebius, and Databricks already support it, so you don't need to self-host. The weights alone are around 1.56 TB, so local runs need serious hardware.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
