| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 4 min 17 sec | 🎖️ Top News
📌 Lambda
⚡️ Trending Signals
📝 Top Models
RMBG v2.0: High-accuracy background removal model with 87.7% photorealistic handling.
OpenScholar model improves scientific literature navigation with retrieval-augmented language models.
LLM2CLIP boosts CLIP’s multimodal performance with large language model integration.
🧠 Pytorch Tip |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
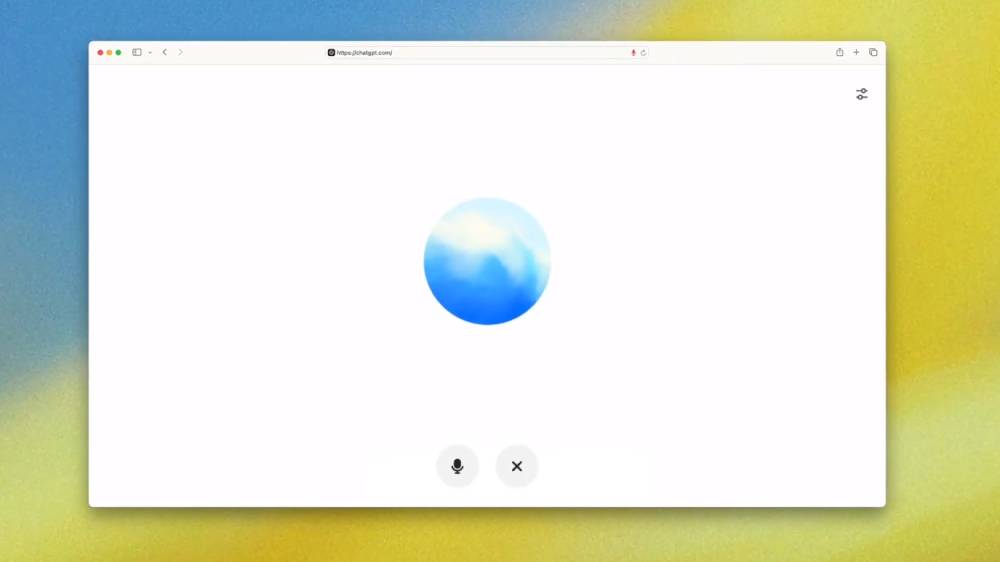
| Voice Interaction | OpenAI rolls out Advance Voice Mode on web, allowing voice-based interactions with ChatGPT |
⇧ 4,789 Likes |
 |
What's New |
OpenAI has introduced Advanced Voice Mode to ChatGPT’s web platform for all paid users, broadening its accessibility.
The feature, initially available on iOS and Android in September, now allows users to interact with ChatGPT via voice input directly in the web browser.
Key Highlights
- Advanced Voice Mode allows users to interact with ChatGPT via voice input through a web browser.
- Eliminates the need for typing, enabling natural language communication in real-time.
- Users can ask questions, explore ideas, or perform tasks hands-free, improving speed and efficiency.
- Voice input is processed by the same language models used for text-based interactions.
- Supports real-time translation and conversations across languages.
Use-cases
- Real-time language translation: Use it to conduct business conversations across languages, as tested in Seoul and Tokyo.
- Hands-free queries and interactions: Ideal for developers who prefer voice interaction over typing for tasks like exploring documentation, testing model behavior, or generating code ideas.
- Accessible across devices: The web deployment makes it easier to switch between desktop and mobile platforms while maintaining voice interaction capabilities.
Cost Efficiency
The model processes 3.6x more tokens per ¥0.3 compared to GPT-4o-mini, maintaining competitive pricing for its extended capabilities. It provides scalability for applications involving high token volumes without increasing costs.
How to Access it? The update is available for users with a Plus, Enterprise, Teams, or Edu subscription. Free-tier users will gain access in the coming weeks. This new deployment extends voice interaction capabilities to web browsers, complementing the previously available desktop and mobile app versions.
- Available for Plus/Enterprise/Teams/Edu subscribers.
- Free users to get access in future updates.
| |
|
Read more
|
|
|
|

| Learn How to Simplify and Automate your AI Infrastructure |
Lambda is a cloud platform offering on-demand NVIDIA GPU instances and clusters for AI developers.
Join Brendan Fulcher (Lambda ML Engineer) and Andrey Cheptsov (dstack CEO) for a live webinar on December 4th at 10 am PT / 1 pm ET.
What You’ll Learn: - Set up dstack, an open-source AI container orchestrator on Lambda for AI tasks.
- Automate instance provisioning effortlessly.
- Orchestrate training, environments, and deployments seamlessly.
Explore how Lambda’s AI-optimized cloud and dstack—a Kubernetes alternative for AI/ML orchestration—simplify and automate AI infrastructure.
Don’t miss this opportunity to elevate your workflows with expert guidance.
|
|
Register now
| partner with us |
|
|
|
TRENDING SIGNALS
| Enterprise Agents |
|
⇧ 849 Likes | |
Vision Language Model |
|
⇧ 2,672 Likes | |
AI Personalization |
|
⇧ 1,161 Likes | |
Grok API |
|
⇧ 3,473 Likes | |
Audio Generation |
|
⇧ 611 Likes | | |
|
|
|
|
TOP MODELS
| Background Removal |
| ⇧19,434 Downloads |
BRIA RMBG v2.0 helps you remove backgrounds from images across various categories, including e-commerce, gaming, and advertising. Trained on over 15,000 high-res, manually labeled images, the model achieves high accuracy with balanced gender and ethnicity representation. It uses the BiRefNet architecture, offering 87.7% photorealistic content handling. |
| Language Model |
|
⇧ 67 Stars |
This recently releases model helps you efficiently navigate and synthesize scientific literature by using a retrieval-augmented language model. It first searches for relevant papers and then generates responses grounded in those sources. This approach addresses the challenges of staying current with the rapidly expanding volume of scientific publications. |
| Multimodal Model |
|
⇧ 8,893 Downloads |
LLM2CLIP enhances the pretrained CLIP model by integrating large language models (LLMs) as textual teachers, improving CLIP’s ability to process long, complex text. It extends the input window, deepens text comprehension, and aligns text-image representations more effectively. The model employs Caption-to-Caption Contrastive Learning, boosting CLIP’s multimodal performance for tasks like dense captioning and image-text matching. |
| |
| |
|
|
PYTORCH TIP
| Optimizing Memory and Performance with Checkpointing and Profiling | In PyTorch, two powerful but underused tools — checkpointing and profiling — can significantly enhance the efficiency of the models.
Why This Works
Checkpointing reduces memory usage by recomputing activations during the backward pass, enabling deeper models or larger batch sizes without exceeding GPU limits.
Profiling helps identify time bottlenecks during forward and backward passes, allowing for targeted optimizations and better hardware utilization.
Together, they enhance resource management and model performance.
When to Use
Use this when training large models or optimizing inference speed.
Benefits
Helps identify slow operations, providing insights to fine-tune code and hardware usage for optimal performance, especially in production.
Example Code |
import torch
import torch.nn as nn
from torch.autograd.profiler import profile, record_function

class SimpleModel(nn.Module):
    def forward(self, x):
        return x * 2

model = SimpleModel().cuda()
input_data = torch.randn(1000, 1000).cuda()

with profile(use_cuda=True) as prof:
    with record_function("model_forward"):
        output = model(input_data)

print(prof.key_averages().table(sort_by="cuda_time_total"))
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. | | | |
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Work with us
|
|
|
|
|
