AI is eating its own supply chain. Google ships Neon to make frontier reasoning cheaper, while OpenAI uses AI to redesign the chips that run it all.
That's the loop closing in real time: better models, cheaper to run, on hardware AI helped build. And Google's SIM paper adds memory to the mix, so agents compound instead of reset.
The stack is getting smarter at every layer. Quietly.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
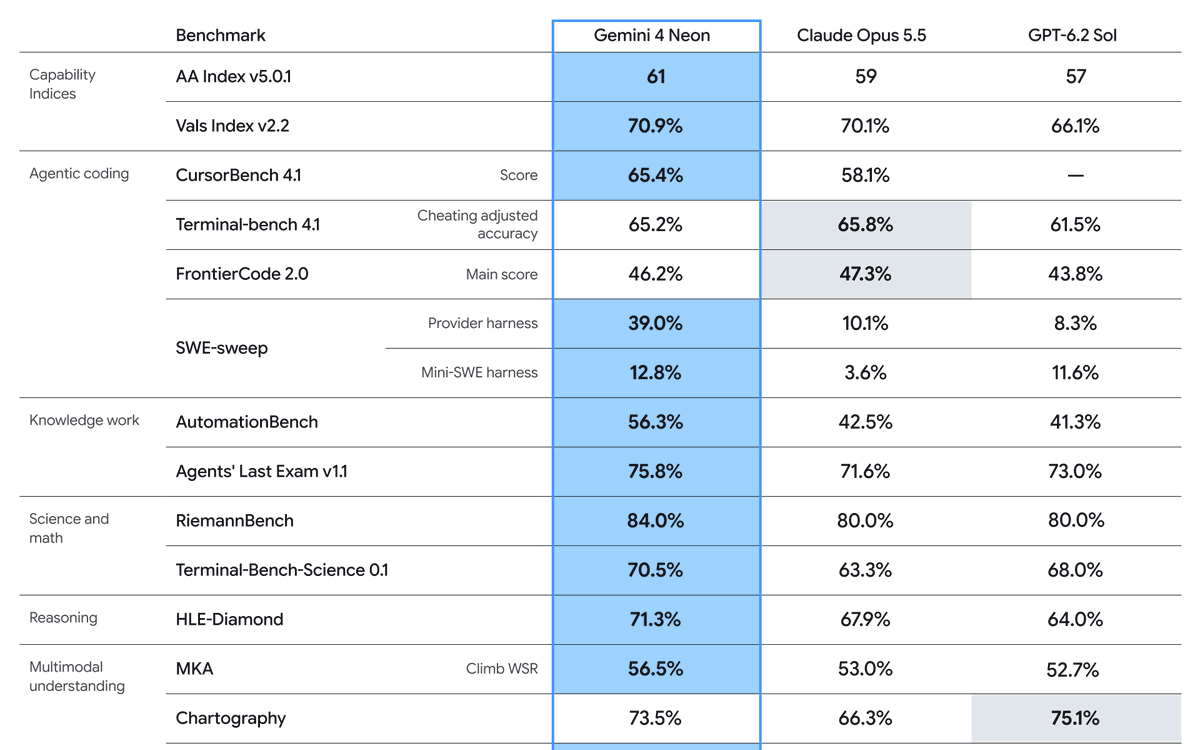
Google DeepMind ships Gemini 4 Neon, ranking #3 on the Intelligence Index
|
|
7,150 Likes
|
|
Google just dropped Gemini 4 Neon, a new model sitting between the cheaper Hydrogen and the more powerful Carbon. Think of it as the sweet spot: near-Carbon reasoning quality, but faster and cheaper per task. Here is what you get: - 1M token context window shared across input, thinking, and output, so you can feed it entire codebases or long documents
- Handles text, images, video, audio, and PDFs in one call
- Four thinking levels: low, medium, high, and xhigh, so you control how hard it thinks and what you spend
- Supports Computer Use, code execution, file search, and Google Search grounding
- Priced at $3 per million input tokens and $15 per million output tokens
You can use it right now via the Gemini API, AI Studio, and Android Studio with model ID gemini-4-neon. One heads-up: if you are migrating from an older Gemini model, set the thinking level explicitly or you will hit validation errors.
|
|
|
|
Presented by Collibra
|
|
Your AI agents are working. Who’s watching?
|
|
Agents now read, decide and act across your tools, and the fleet grows whether you govern it or not. Drift, not hackers, is the usual failure. Collibra’s playbook shows how to scan every agent, set fleet-wide rules and catch problems early. Includes a 10-step plan and a maturity self-assessment.
|
|
|
|
Top News
|
|
|
|
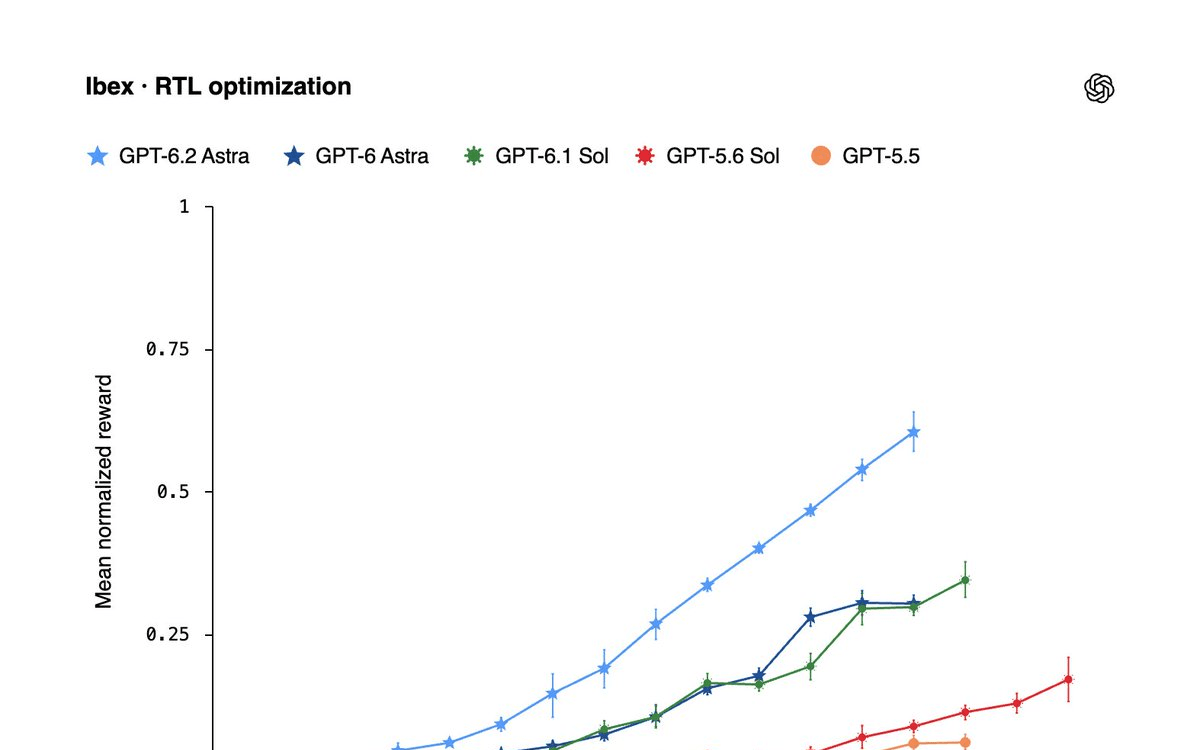
OpenAI's chip design model delivers 14% hardware gains on AMD's GPU
|
|
4,229 Likes
|
|
Chip design used to take years of expert tuning. OpenAI just showed AI can compress that into months. Working with AMD, OpenAI's models rewrote chip circuit code and found up to 14% PPA improvement on AMD's flagship GPU. PPA stands for power, performance, and area: how efficient, fast, and compact a chip is. That's roughly a year of progress achieved in less than five months. And these weren't fresh designs either. AMD has already included some changes in a recent design sent for manufacturing, with others added to production files for future versions. OpenAI also ran the same approach on Jalapeño, its own custom chip built to run AI models, with gains confirmed on real silicon. The bigger unlock is GPT-Synopsys: a new model trained to use Synopsys EDA tools the way expert chip designers do. EDA tools are the software used to build and verify chips. This opens the workflow to any team, not just the biggest labs.
|
|
|
|
Presented by Orkes
|
|
Why the best AI agents are built like octopuses
|
|
Because when an octopus loses an arm, it grows it back. Orkes Conductor gives your agents the same power: every agent compiles into a workflow, so failed steps retry, humans approve mid-run, and runs survive crashes. Free for devs, with agent skills, MCP, and Python, TypeScript, and Java SDKs.
|
|
|
|
Top News
|
|
|
|
Cognition launches Devin Bots, helping engineers merge 4.5x more PRs
|
|
4,063 Likes
|
|
Cognition just shipped Devin Bots, and the idea is simple: instead of you managing every coding task, an AI manager does it for you. Think of it like hiring a team lead. The Bot takes a big goal, breaks it into tasks, spins up multiple Devin agents to work in parallel, checks their output, and only pings you when a real decision is needed. - Handles planning, code review, and automated testing end-to-end
- Bots talk to each other: a QA Bot finds a bug, hands it to a Developer Bot to fix
- Keeps memory across sessions, so it stays on track over days or weeks
- You follow along in Slack, group chat, or phone call
The numbers are hard to ignore. Beta testers are merging 4.5x more pull requests per message. One team went from 50 to nearly 2,000 PRs a week. You can start from a template for your backlog, CI, or next release at devin.ai/bots.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
