| Hey, | Welcome to today's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries ensure you're always up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior |
|
|
|
IN TODAY'S SIGNAL | Read Time: 4 min 57 sec |
|
|
|
Enjoying this newsletter? Please forward it to a friend or colleague. It will help us keep this content free. |
|
|
|
TOP PROJECT | Operating Systems | AIOS: The First LLM Agent Operating System | ☆ 1581 ⇆ 131 | 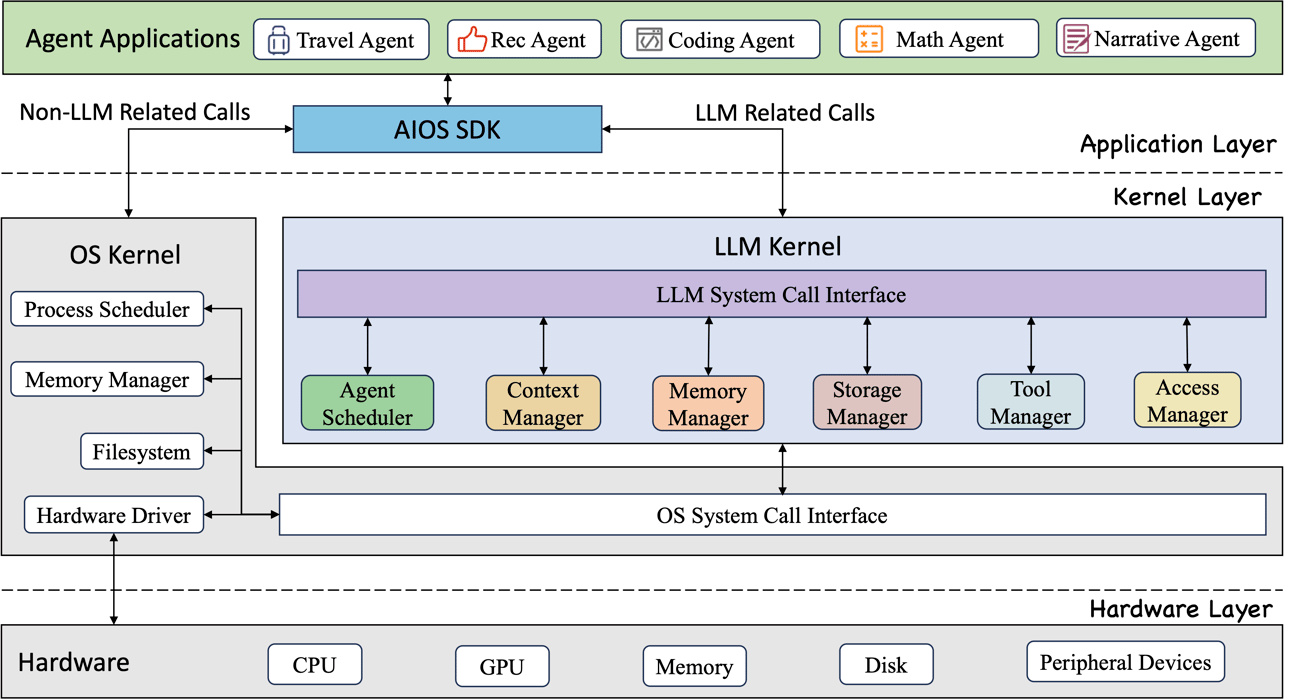 | What's New | AIOS (LLM Agent Operating System) is a new agent orchestration framework that embeds large language models into operating systems, creating an OS with a "brain" that can "understand".
AIOS is designed for optimal resource allocation, facilitating context switches, concurrent execution, tool services for agents, access control, and providing a rich toolkit for developers.
AIOS is based on several key agents that orchestrate the others. It consists of: an Agent Scheduler for prioritizing agent requests, a Context Manager for managing interaction context, a Memory Manager for short-term memory, a Storage Manager for long-term data retention, a Tool Manager for managing external API tools, and a Access Manager for enforcing privacy and access control policies.
Those agents communicate with the AIOS SDK in an interactive mode, along with non-LLM tasks coming from the OS Kernel (with the Process scheduler, the memory manager, etc).
This architecture allows AIOS to integrate complex AI functionalities into traditional operating systems, enabling the development of more intelligent, responsive, and efficient applications that can leverage the full power of LLMs alongside conventional OS resources and capabilities. | Why This Matters | This approach is a shift in the way we interact with machines with agents deployed at the Operating System level that accomplish complex tasks. This trend is also demonstrated by Apple's ReALM models capable of understanding not only conversation, but also on-screen and background jobs information. This a new era of intelligent computing. | Community Feedback | Andrey Karpathy: "Looking at LLMs as chatbots is the same as looking at early computers as calculators. We're seeing an emergence of a whole new computing paradigm, and it is very early." (09/23)
Carlos E. Perez: "AIOS constitutes a holistic platform to truly unleash the potential of LLM agents in the real world."
| | Get the code |
|
|
|
 | Experience breakthrough multi-workload performance in the cloud | Get the most out of the L40S by relying on Latitude.sh’s high-performance networking and enterprise-grade hardware designed for Machine Learning engineers.
With an intuitive dashboard and pre-installed AI software, you get from zero to running workloads in just a few clicks.
NVIDIA's universal GPU is now available at Latitude.sh in fully dedicated clusters and container GPUs.
With 48 GB of vRAM, the GPU is a great value for universal workloads: from running inference to training models with up to 24 Billion parameters in FP16. | | Get started | partner with us |
|
|
|
TOP PAPERS | Agents | | Demonstrates that adding more agents increases LLMs accuracy using a simple sampling-and-voting technique. Tests across various LLM benchmarks show this approach improves performance significantly, especially for complex tasks.
For instance, with 15 agents, Llama2-13B equals Llama2-70B's accuracy, and with 15 to 20 agents, Llama2-70B and GPT-3.5-Turbo reach the accuracy of their more powerful versions. The authors share the code publicly.
"We realize that the LLM performance may likely be improved by a brute-force scaling up the number of agents instantiated." | ⇧ 1630 ⇆ 150 | | Vision | | Achieves 94% accuracy on CIFAR-10 in 3.29 seconds on a single NVIDIA A100, scaling to 96% in 46.3 seconds. Integrates six techniques: patch-whitening and identity initialization, higher learning rate for biases, Lookahead optimization, multicrop TTA, and alternating flip for augmentation.
These strategies, combined with torch.compile for efficient GPU use, offer open-source scripts, markedly speeding up ML experiments and reducing costs, showing a 1.9× speed boost over previous records. Techniques generalize across small-scale tasks and contribute uniquely to the final speed, with alternating flip providing a notable 10% speedup. | "I think it's nice to develop intuition for training neural nets with this thing. It can be used to test classic things like "when you double the batch size, is it really ideal to double the learning rate?" in < 1 minute" | ⇧ 360 ⇆ 68 | | Language Models | | Google introduces Equal-Info Windows, a method for training large language models on neurally compressed text. It outperforms byte-level baselines in perplexity and inference speed but has higher perplexity than subword tokenizers.
This method reduces sequence lengths, leading to lower latency. At 2 billion parameters, it achieves perplexity close to that of SentencePiece tokenization with reduced computational demands for inference. | Yi Tay: "Holy. This idea is so outrageously cool and insane." | ⇧ 874 ⇆ 55 | | |
| |
|
|
PYTHON TIP | Optimization | Multiprocessing with Pool | Python's multiprocessing library enables task execution in parallel by creating separate processes for each task, effectively utilizing multiple CPU cores.
This method bypasses the Global Interpreter Lock (GIL), allowing for concurrent task processing. The library includes Process and Pool classes for managing processes, and it supports inter-process communication through pipes and queues.
By dividing tasks into independently executable units, multiprocessing can significantly reduce execution times for parallelizable tasks. |
from multiprocessing import Pool
import time

def process_request(request):
    time.sleep(1)
    return f"Processed "

requests = ['req1', 'req2', 'req3', 'req4', 'req5']

# Sequential processing
start = time.time()
results_seq = [process_request(req) for req in requests]
print(f"Sequential:  seconds")

# Output: Sequential: 5.00 seconds
| Running the same processes in parallel will speed up the execution. Here is how you can do it using multiprocessing.Pool. |
# Concurrent processing with multiprocessing Pool
start = time.time()
with Pool(5) as p:
    results_pool = p.map(process_request, requests)
print(f"Pool:  seconds")

# Output: Pool: 1.11 seconds
|
|
|
|
TOP OF REDDIT | Gemini's context window is much larger than anyone else's | | ⇧ 1631 | 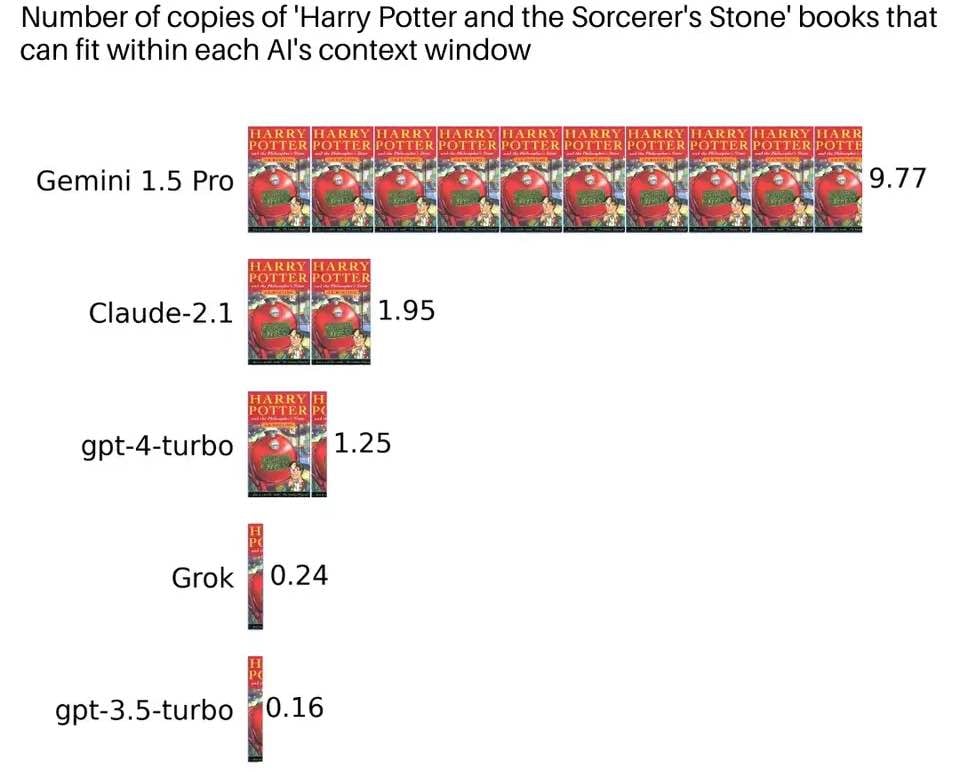 | | | | ⇧ 420 | 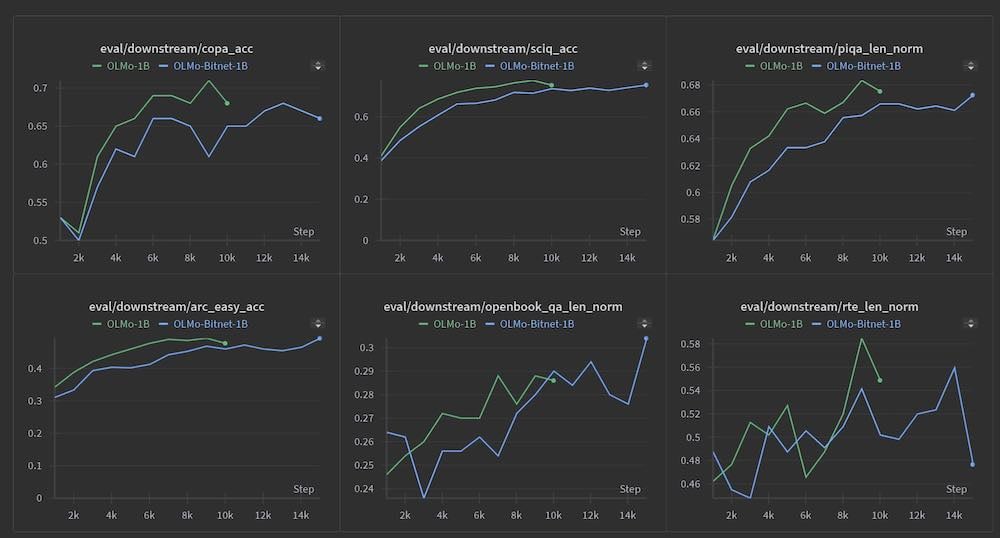 | We are releasing our first step in validating and independently confirming the claims of the Bitnet paper, a 1B model trained on the first 60B tokens of the Dolma dataset. Comparisons made on the @weights_biases charts are between the Bitnet implementation and a full FP16 run (all hyperparameters equivalent)
| | | | ⇧ 775 | "This is a bold claim, but I feel like LLM hype dying down is long overdue. Not only there has been relatively little progress done to LLM performance and design improvements after GPT4: the primary way to make it better is still just to make it bigger and all alternative architectures to transformer proved to be subpar and inferior, they drive attention (and investment) away from other, potentially more impactful technologies. [...] I can't help but think that the entire field might plateau simply because the ever growing community is content with mediocre fixes that at best make the model score slightly better on that arbitrary "score" they made up, ignoring the glaring issues like hallucinations, context length, inability of basic logic and sheer price of running models this size." | |
| |
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics. |
|
|
|
Want to promote your company, product, job, or event to 175,000+ AI researchers and engineers? | | Sponsor |
|
|
|
|
