Agents are eating software. xAI ships Grok Bot, a $120/seat autonomous worker that logs into your tools and never sleeps. DeepSeek drops a free, MIT-licensed agent framework the same week.
One is closed, expensive, and ready to deploy. The other is open, free, and yours to build on. Two very different bets on who wins the agentic layer.
Meanwhile, researchers proved you can predict model scaling from tiny, cheap runs. Less glamorous, but arguably the most valuable news today.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
xAI launches Grok Bot, an AI agent that logs into your tools and works autonomously
|
|
40,100 Likes
|
|
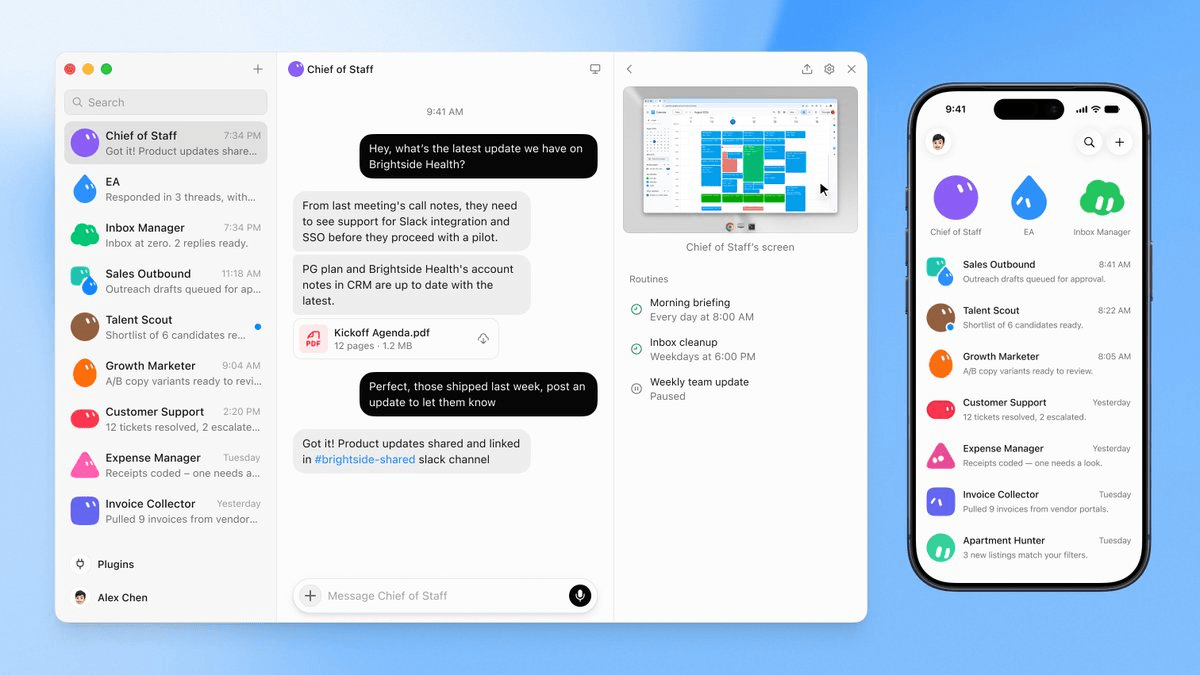
xAI just shipped Grok Bot, and it is a different kind of AI tool. Not a chatbot. Not a code helper. An AI that logs into your actual accounts and does the work while you sleep. Here is how it works: each Bot gets its own cloud computer, signs into your tools the same way you do, and keeps running after you close your laptop. No API setup needed. It clicks, types, and navigates any browser-based app like a human would. What can you actually hand off to it? - Keeping a CRM updated automatically
- Managing customer support for an online store
- Researching accounts and drafting outreach overnight
- Negotiating with vendors in your own voice
The big unlock: any tool you can open in a browser is now automatable, no integration required. The catch? Pricing starts at $120/seat/month, with no free tier. It is available on macOS, iOS, Windows, and Linux today.
|
|
|
|
Presented by Teleport
|
|
Extend Zero Trust to include AI agents
|
|
AI agents aren’t just users or applications – they’re autonomous actors operating at a speed and scale that challenges today’s security frameworks. Zero Trust, as it’s currently conceived, is both necessary but insufficient to control or contain them. “From Zero Trust to Agent Trust,” from Teleport, explains why Zero Trust must expand to Agentic Trust Principles: - verify explicitly → enforce continuously
- use least privilege → bound collective autonomy
- assume breach → assume misalignment
|
|
|
|
Top News
|
|
|
|
DeepSeek open-sources a plugin-first agent framework under MIT license
|
|
15,951 Likes
|
|
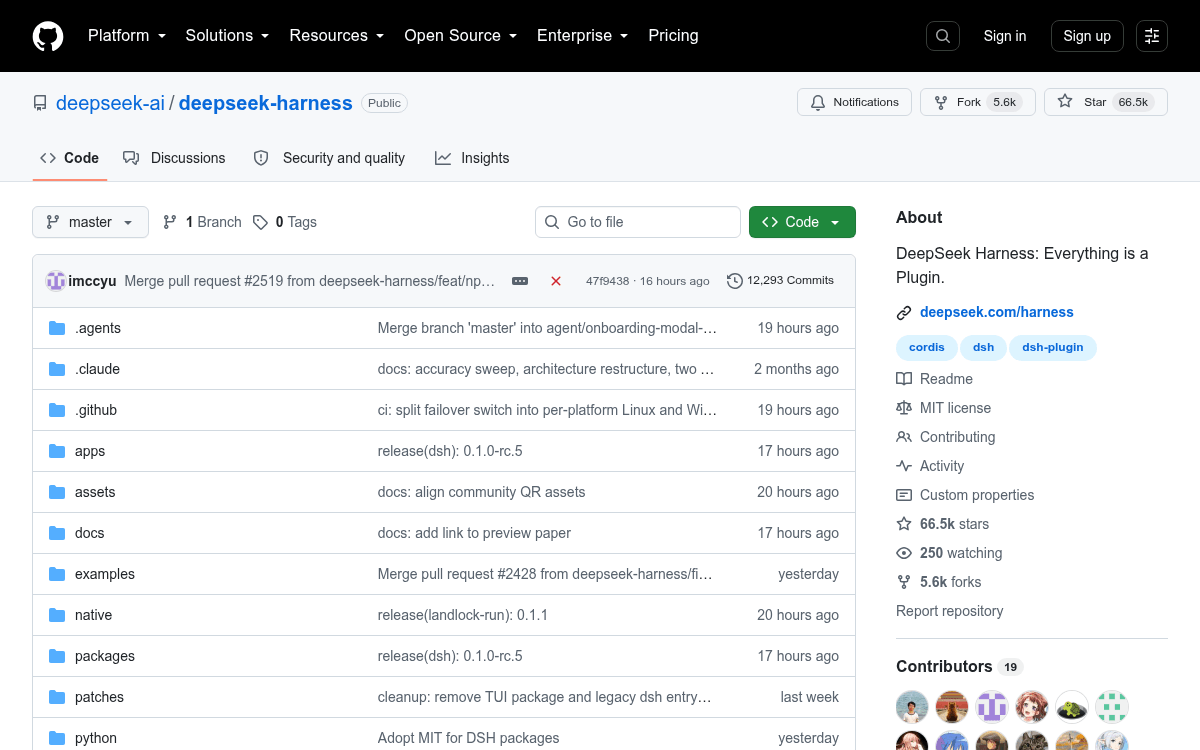
DeepSeek just dropped Harness v0.1, an open-source framework for building AI coding agents, and it's free to use under the MIT license, meaning you can build commercial products on top of it with zero restrictions. The core idea is simple: everything is a plugin. Instead of one rigid system, every piece of the agent, including the AI model, tools, memory, file system, and even the UI, is a swappable plugin. You can mix, match, and replace any part without touching the source code. It ships with four ready-to-use modes: - Standard: full agent with file editing, shell, web search, and subagents
- Code: model writes TypeScript to chain multi-step tool calls together
- Minimal: bare-bones shell and file editor, great for benchmarking
- Creator: build and test your own custom agent setups
Every session is fully traceable via an append-only log you can replay or fork. To try it: git clone, pnpm install, pnpm dsh web, then open localhost:3080. Expect breaking changes, it's early.
|
|
|
|
Presented by Databricks
|
|
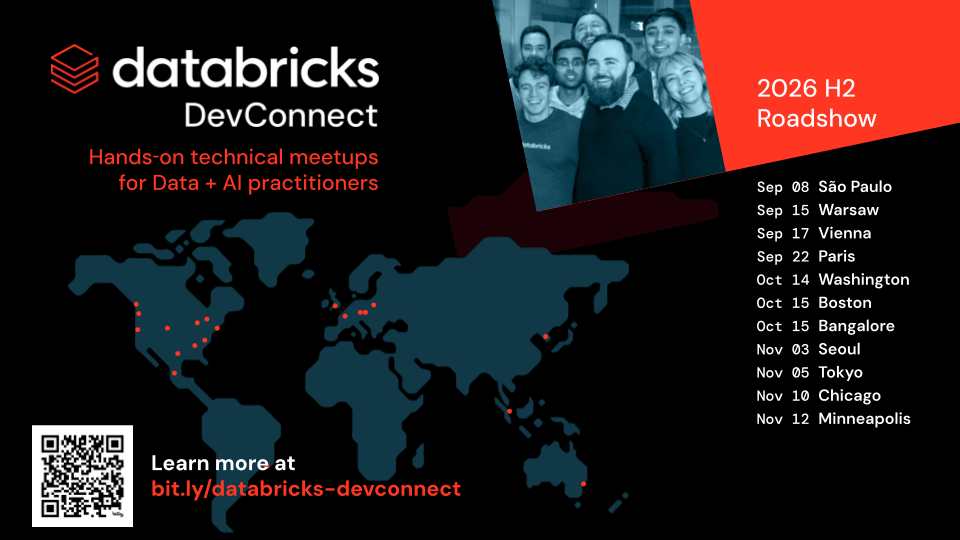
Databricks DevConnect is coming to a city near you.
|
|
Get code-level deep dives and live demos on Lakehouse//RT, LTAP, Managed MCP, Unity AI Gateway, Omnigent, and Genie ZeroOps. Explore real-time data, agentic workflows, and production-ready apps. Connect with Databricks experts and peers. Find an event near you.
|
|
|
|
Top News
|
|
|
|
OpenAI launches GPT-5.6 Sol at 750 tokens per second via Cerebras
|
|
14,490 Likes
|
|
You know the old rule: fast AI = dumb AI. Want the smart model? Wait for it. OpenAI just broke that rule. Meet GPT-5.6 Sol Ultrafast, a new speed tier for their most capable model, powered by Cerebras hardware. Same intelligence, no trade-off. The numbers: 750 tokens per second, up to 14x faster than standard processing. For context, you read at roughly 5-10 tokens per second. This thing is not waiting around. Why so fast? Normal GPUs constantly shuffle model weights between on-chip and off-chip memory, which creates a bottleneck. Cerebras keeps all 44 GB of weights sitting directly on-chip, so nothing waits. Tokens just flow. What you can actually build with this: - Real-time voice apps that feel instant
- Customer support bots with zero lag
- Coding agents that chain dozens of steps in seconds, not minutes
- Security and financial tools where delays cost money
Access is limited preview via the OpenAI API right now. You can sign up to be notified when capacity opens up.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
