| Hey, | Welcome to AlphaSignal, the most read source of news by AI engineers and researchers. Every day, we identity and summarize the top 1% of news, papers, models, and repos, so you’re always up to date.
Here’s today’s roundup: |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
./TOP_NEWS
| | Alibaba Releases Open-source Qwen3 Coder Flash
| 3,181 Likes |
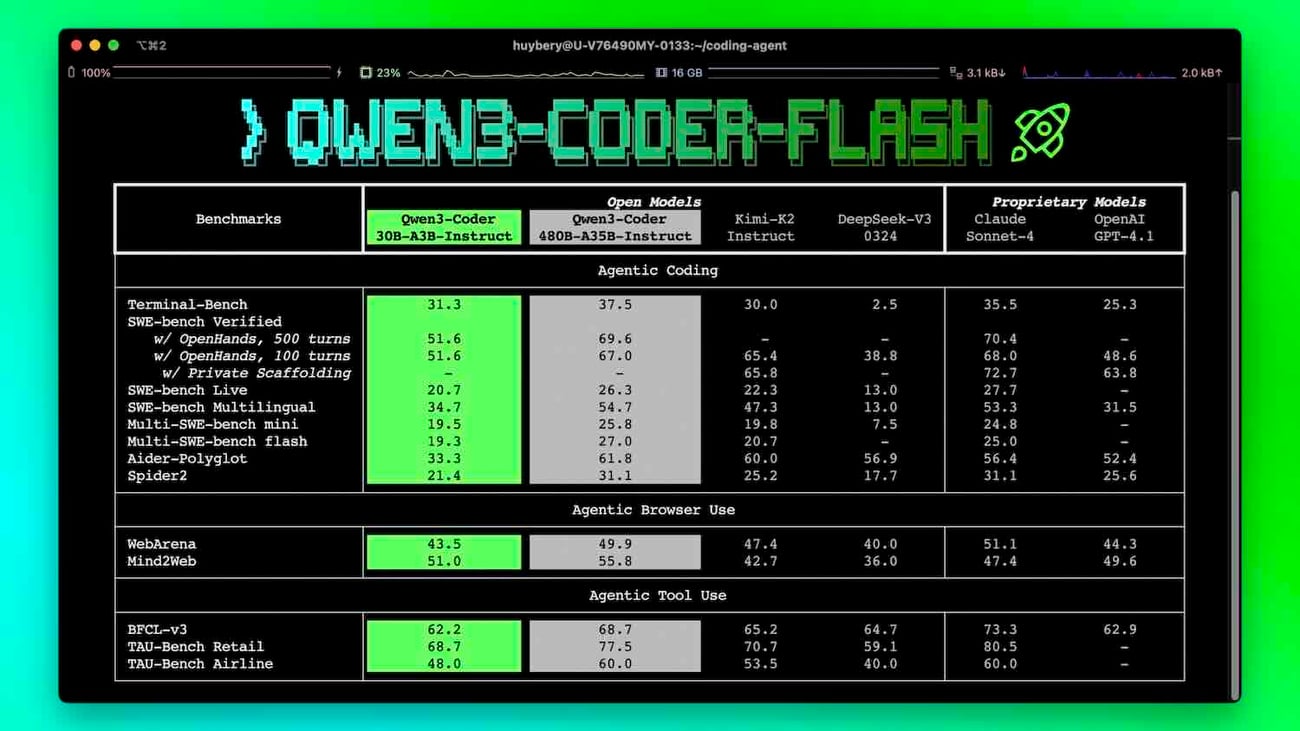
| Alibaba unveils Qwen3-Coder-Flash, a 30.5B code model that matches Claude Sonnet 4 on key coding tasks. The model runs on standard consumer hardware, setting a new bar for local deployment.
Architecture and Technical Specifications
Qwen3-Coder-Flash features a Mixture-of-Experts architecture for efficiency and performance. 128 experts, 8 activated per inference, with 3.3B parameters active at a time 256K native context window, expandable to 1M tokens using YaRN Full-precision inference requires 33GB of RAM; quantized versions run on 18GB Model file size is about 60GB for download and storage Benchmarks and Performance
Qwen3-Coder-Flash delivers strong results on several technical benchmarks for code and agent tasks.
Scores 51.6% on SWE-bench Verified for code reasoning and completion Achieves 51.0% on Mind2Web for agentic browser tasks Performs competitively on WebArena and BFCL for tool use and workflow integration Licensing and Compatibility
The model is fully open source under the Apache 2.0 license and integrates with popular tooling.
Weights are available on Hugging Face and Modelscope for unrestricted use Compatible with Hugging Face Transformers, LM Studio, Ollama, llama.cpp, MLX-LM, and KTransformers Supports agentic coding and function calling with OpenAI-compatible APIs Documentation and quickstart guides are available on Hugging Face and GitHub | |
| Try now
|
|
|
|
| One platform to build, test, and ship agents you’ll actually use. | Most agent frameworks bury you in complexity and edge cases you’ll never use.
Vellum cuts through the noise, it gives you direct control over what matters: context, memory, and integrations.
Decide exactly what your agent sees and uses Load only the docs and tools needed for each task Connect to 1,000+ platforms including Slack, Linear, HubSpot Trace, evaluate, and debug context issues in real time Deploy anywhere with a single click Build agents with context you can see and trust. |
| Try vellum
| partner with us |
|
|
|
./TOP_MODELS
| |
| 157,021 Downloads |
Higgs Audio V2 helps you generate expressive, multilingual speech with high-quality prosody and zero-shot TTS. It performs well on benchmarks like Seed-TTS Eval (WER 2.44, SIM 67.7%) and ESD (WER 1.78, SIM 86.1%). The model uses a 25 FPS audio tokenizer and a DualFFN architecture. |
|
|
| 352,110 Downloads |
Kimi K2-Instruct is a 32B-activated parameter mixture-of-experts (MoE) model designed for advanced reasoning, coding, and tool use. It handles tasks like autonomous problem-solving and code generation, achieving 53.7% pass@1 on LiveCodeBench and 65.8% accuracy on agentic coding tasks. Trained on 15.5T tokens, it uses the Muon optimizer for stability. |
|
|
| 94,192 Downloads |
Qwen3-30B-A3B-Instruct-2507 is an updated version of the Qwen3-30B-A3B non-thinking mode, with improvements in instruction following, reasoning, text comprehension, coding, and tool usage. It boosts long-tail knowledge across languages, aligns better with user preferences, and supports 256K long-context. |
| |
| |
|
|
./TUTORIAL
| |
Coding Qwen3 from scratch (notebook included) |
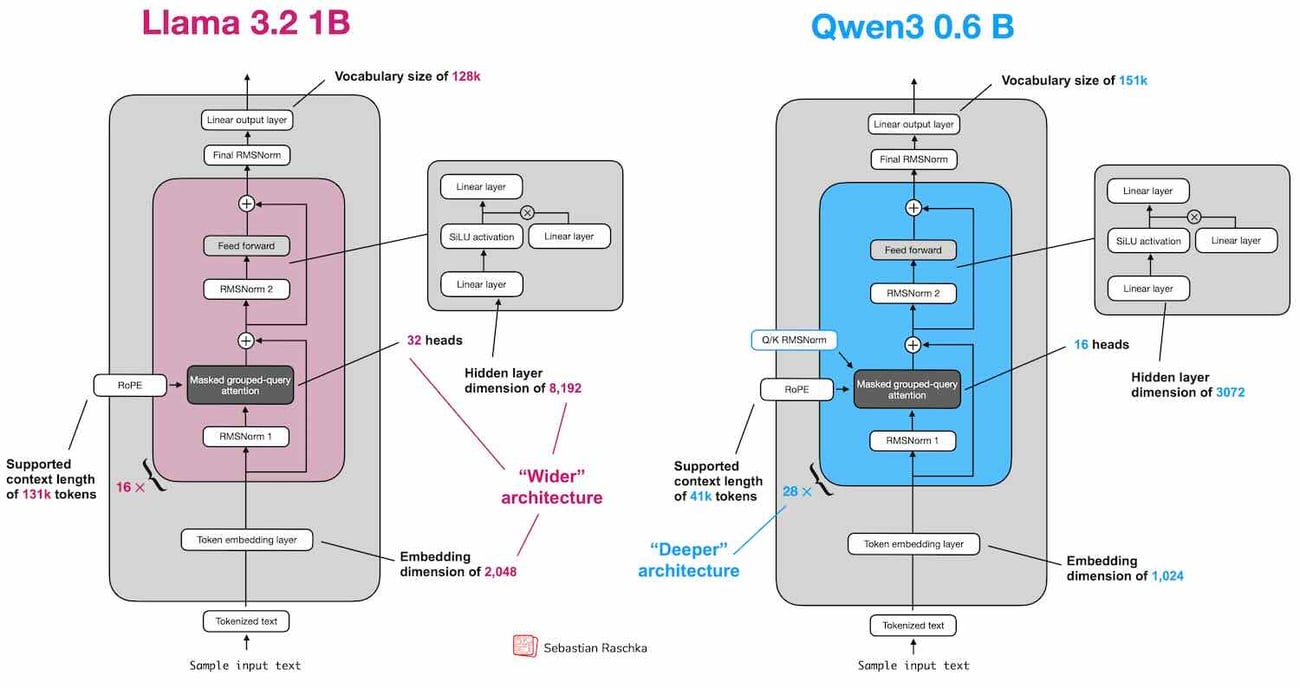
| Sebastian Raschka’s “Qwen3 From Scratch” tutorial provides a step-by-step guide to implementing the Qwen3 language model family using PyTorch.
The tutorial covers building the Qwen3 0.6B model, downloading pretrained weights, initializing the tokenizer, and running text generation.
Raschka compares Qwen3’s architecture to Llama 3, explaining trade-offs between depth and width, and details performance metrics for different hardware and model sizes.
The guide demonstrates use of the reasoning-focused model variant and offers tips for speeding up inference, including compilation, KV cache, and batched inference.
All code and instructions are available in the provided Jupyter notebook and repository. |
| Read more
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
