| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 4 min 31 sec | 🎖️ Top News
📌 Hume
⚡️ Trending Signals
📌 AskUI
💻 Top Repos
fish-speech: Generate high-quality, multilingual TTS with just a 30-second sample.
lobe-chat: Framework for building chat apps with Claude, Gemini, and Llama2.
VAR: Scalable image generation surpassing diffusion models with next-scale prediction.
🧠 Top Lecture |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| AI Model | OpenAI releases Sora Turbo, its fast, high-resolution video generation model for ChatGPT Plus and Pro users |
⇧ 19,238 Likes |
 |
What's New |
OpenAI launches Sora Turbo, an upgraded video generation model that turns text into realistic videos on the third day of its "12 Days of OpenAI" event. You can use it as a standalone product through ChatGPT Plus and Pro plans, with better speed and video quality compared to the original Sora.
Core Features and Functionality
- Sora generates videos up to 20 seconds long in various aspect ratios: widescreen, vertical, and square.
- You can remix, blend, or create new content from text prompts.
- The Turbo model significantly reduces generation times compared to earlier versions.
- You can input images or videos using the storyboard tool for detailed scene construction.
User Interface and Tools You can use Sora's intuitive tools, such as the storyboard tool, which lets you specify inputs for each frame. This feature allows you to input images or videos to create detailed scenes. You can also modify videos with the Remix tool and explore community-generated content through Featured and Recent feeds.
Performance and Usage Limits Sora Turbo improves video generation speed. Your usage limits depend on your plan:
- ChatGPT Plus: 50 videos at 480p or fewer at 720p per month.
- ChatGPT Pro: 500 priority videos at 1080p, up to 20 seconds long, with watermark-free downloads. Pro users can generate up to five videos simultaneously.
Pricing and Access
You can access Sora Turbo through the ChatGPT Plus plan for $20/month or the Pro plan for $200/month. The Pro plan provides higher video quality, more generation credits, and faster processing speeds. | |
| Read more
|
|
|
|
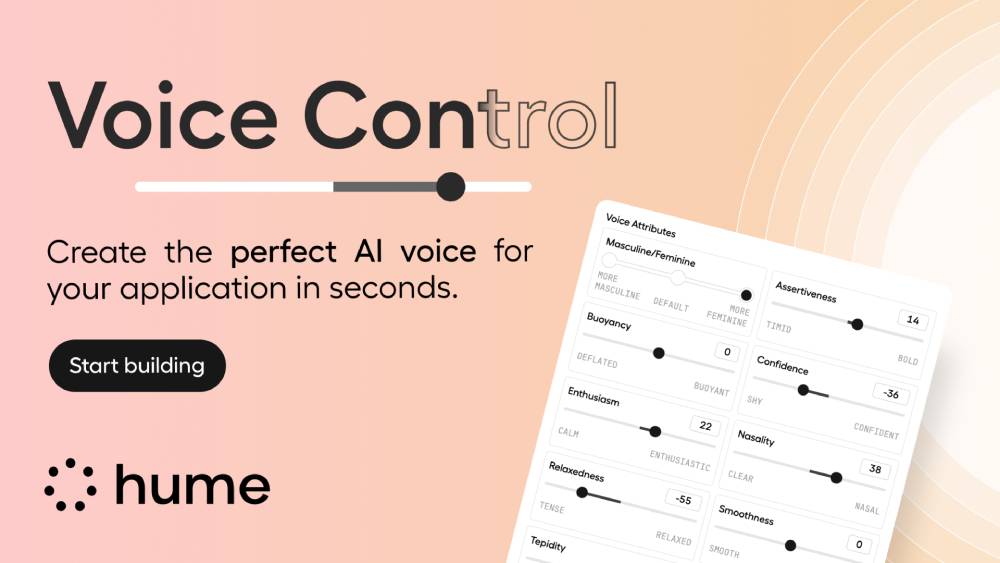
| Create Custom AI Voices with Precise Vocal Modulation | Hume AI just released Voice Control, a tool that lets you create custom AI voices without coding.
You can adjust voices along 10 key dimensions in real-time, including:
- Masculine/Feminine: Control the vocal gender tone
- Buoyancy: Change the voice density from flat to lively
- Confidence: Vary the voice's assuredness
- Relaxedness: Control stress levels from tense to relaxed
Use the intuitive sliders to fine-tune voices in real time and create the perfect voice for your application.
Voice Control avoids the risks of voice cloning by focusing on unique voice customization for use in customer service bots, virtual assistants, and other applications.
You can access Voice Control now in Hume’s virtual playground. Sign up and start your projects today.
|
| Customize your voice
| partner with us |
|
|
|
TRENDING SIGNALS
| LLM |
|
⇧ 13,642 Likes | |
Quantum Computing |
|
⇧ 80,327 Likes | |
Image Generation |
|
⇧ 12,438 Likes | |
Multimodal Model |
|
⇧ 5,238 Likes | |
AI Model Output |
|
⇧ 2,823 Likes | | |
|
|
|
|
Build intelligent computer agents for any OS with Python and LLMs
| AskUI Vision Agent is a powerful framework that helps you create custom computer agents.
Integrate Claude Sonnet 3.5 or Prompt-to-Action for automation.
Automate tasks across platforms like Windows, Linux, MacOS, and Android, with support for multi-monitor setups and OCR. |
FIND IT ON GITHUB ↗️ |
|
|
|
TRENDING REPOS
| Audio Generation |
| ☆ 16,571 Stars |
The Fish-Speech repo helps you generate high-quality, multilingual TTS with zero-shot or few-shot learning, using just a 10–30 second vocal sample. It supports multiple languages, offering low CER (2%) and WER for 5-minute texts. It features an easy-to-use, Gradio-based web UI compatible with Chrome, Firefox, Edge, and other browsers. |
| AI Chat Framework |
| ☆ 48,566 Stars |
This repo provides a versatile framework for building chat applications with support for models like Claude, Gemini, and Llama2. It includes features like file uploads, multi-modal support, local model integration, TTS, STT, visual recognition, and text-to-image generation, offering flexibility for diverse, customizable use cases. |
| Image Generation |
|
☆ 5,874 Stars |
Visual Autoregressive Modeling (VAR) introduces a novel approach for scalable image generation through next-scale prediction, achieving superior results compared to diffusion models. It includes pre-trained models (e.g., VAR-d16 to VAR-d36) with state-of-the-art FID scores, zero-shot generalizability, and power-law scaling laws. Demo scripts and training details are provided, with a user-friendly interface for image generation and model experimentation. |
| |
| |
|
|
TOP LECTURE
| Generative AI | Sora: Video Generation Models as World Simulators |
⇧ 1729 Likes |
 |
This lecture explores OpenAI's text-to-video diffusion model Sora.
Sora generates minute-long, high-quality videos based on text prompts, using diffusion and transformer models. It handles complex scenes, detailed environments, and multiple shots while maintaining consistency across frames. You can animate still images, extend videos, or fill missing frames.
Bill Peebles, author of Diffusion Transformers, presented the model at International Conference on Machine Learning (ICML) 2024.
Key Topics
- Modeling temporal dynamics in videos.
- Creating realistic environmental interactions.
- Scalability of generative architectures.
- Challenges in data-driven world simulation.
- Practical applications of Sora in predictive modeling and scene understanding.
|
| Watch now
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
