Prototyping against the best available frontier AI model is simple, but scaling to tens of millions of tokens creates cost chokeholds and latency bottlenecks. It also frequently fails to provide the specialized accuracy required to cover the last mile of edge cases.
The modern large language model (LLM) landscape is capable but fragmented. Pointing every request to the frontier, such as the expensive Claude Fable, or standard premium giants like Claude Opus 4.8 and GPT-5.6, is wasteful engineering.
Capable open-weight models like GLM-5.2, DeepSeek-v4, and Kimi-K2.7 can reliably run 70% to 80% of routine workloads at a fraction of the cost.
Model routing is the architectural middleware needed to navigate this fragmentation by mapping each request to the optimal model(s). Routing is not a magic fix for broken application logic or poor prompting. But when implemented properly, it is fundamental for building reliable, scalable, and optimized AI applications.
The architecture of a model router
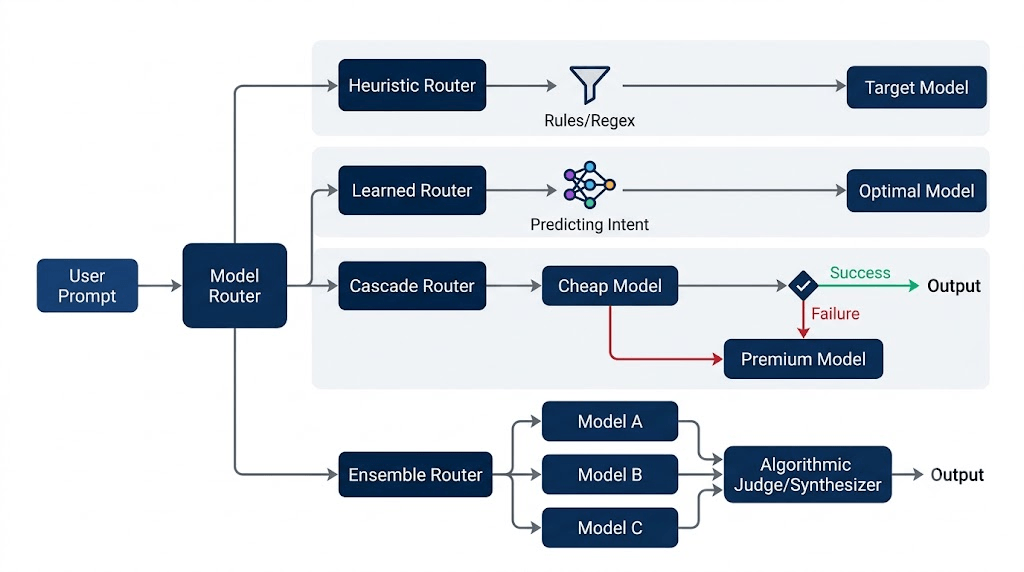
At its core, a router is an intelligent proxy that intercepts a prompt and dispatches it based on constraints like latency, cost budget, or complexity. There are several main paradigms to achieve this:
- Heuristic routers rely on hardcoded, rule-based matching such as keywords or prompt length. For example, if a regex script detects "SELECT * FROM," it automatically intercepts the call and dispatches it straight to a coding model like DeepSeek-v4.
- Learned routers run embedding classifiers that predict model performance based on semantic intent. For example, if the classifier detects that the prompt is related to "DevOps Troubleshooting," it will map it to GPT-5.6, which holds a high success rate over cheaper alternatives on internal evals.
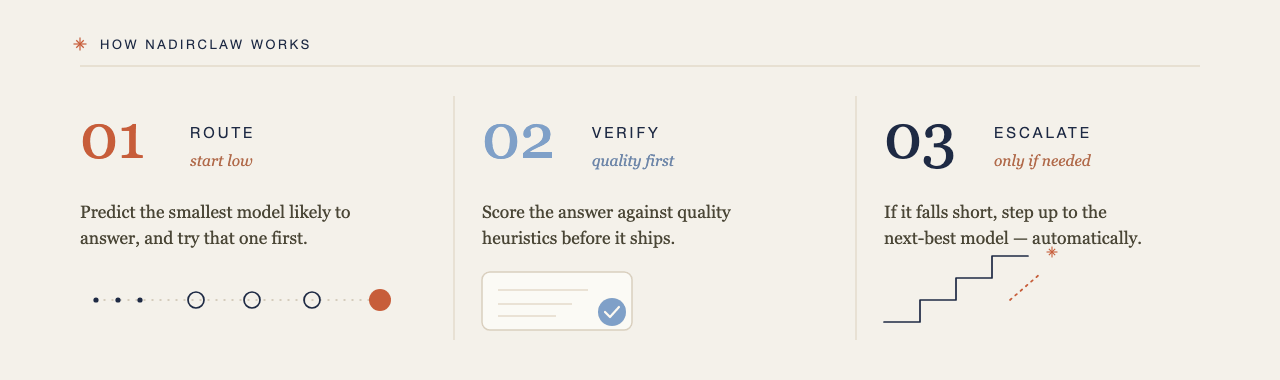
- Cascades are outcome-based pipelines that try a cheap model first and transparently escalate to a heavyweight if verification fails. For example, it starts with DeepSeek-v4-Flash. If a lightweight validator catches an invalid response or a model refusal, the prompt escalates to a stronger model.
- Ensembles (Fusion) runs multiple models concurrently and relies on an algorithmic judge to synthesize or select the best output. For example, you run a particularly sensitive code review task by GPT-5.6, Opus 4.8, and Gemini 3.1 Pro, and synthesize the results by another model to get a final response.
The managed router ecosystem: Commercial options
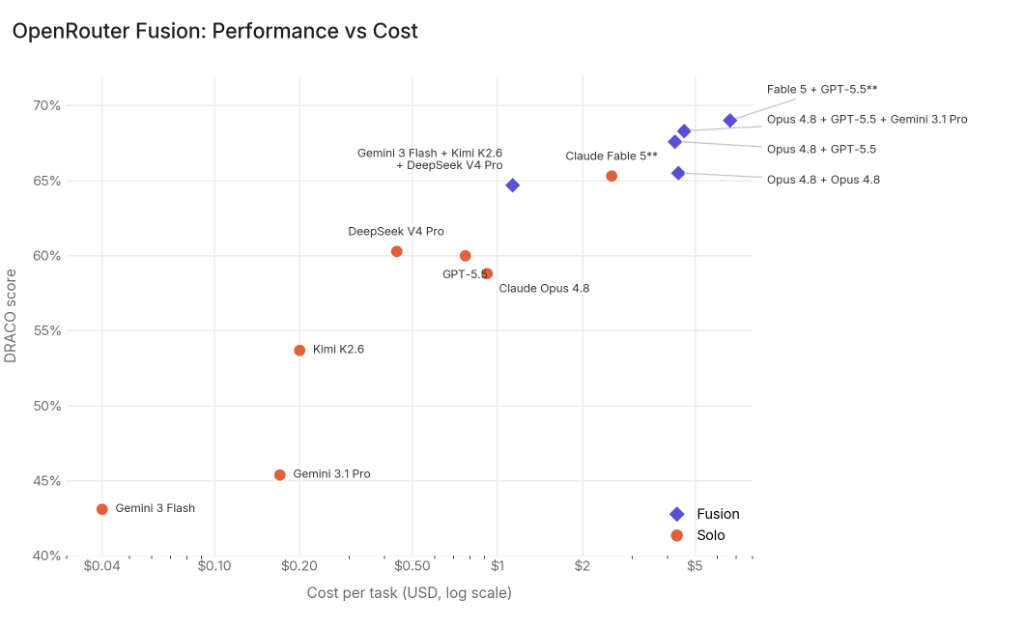
Several managed platforms offer routing-as-a-service, reducing the infrastructure overhead for engineering teams. OpenRouter's Fusion Router blends multiple model outputs to achieve higher aggregate performance than any standalone model.
On Perplexity's rigorous DRACO deep research benchmark, Fusion scored 64.7% with a budget panel consisting of Gemini 3 Flash, Kimi K2.6, and DeepSeek-v4 Pro. This beat standalone GPT-5.5 (60.0%) and Claude Opus 4.8 (58.8%) at roughly half the token cost.
OpenRouter also offers a Pareto Code Router, which maps the cost-to-intelligence curve using domain-specific metrics from Artificial Analysis. Developers adjust a minimum coding score from 0 to 1. Pareto Code Router supports a "nitro" mode that targets the fastest measured provider throughput in that quality tier.
Not Diamond takes an advanced learned routing approach that allows developers to train custom routers using their own evaluation data. Engineering teams can upload a dataset containing their domain-specific prompts, the models tested, and the resulting evaluation scores.
Not Diamond uses this data to train a specialized routing model that learns the nuances of the task and predicts which LLM will perform best for similar future requests. This allows developers to optimize routing logic for their internal metrics, such as strict formatting rules or specific coding guidelines.
The open source and self-hosted frontier
For teams requiring zero middleman latency and total data privacy, open-source routers provide local alternatives. NadirClaw is a drop-in, OpenAI-compatible proxy built to optimize LLM traffic.
Recognizing that 60% to 70% of developer assistant prompts are simple file-reads or formatting tasks, NadirClaw routes them via a 10-millisecond embedding classifier. Its built-in optimization engine strips out bloated tool schemas and redundant JSON arrays before dispatch, dropping token overhead by 30% to 70%.
On RouterArena benchmarks, NadirClaw's default cascade profiles hit a score of 0.7358 while slashing raw API bills by up to 70%.
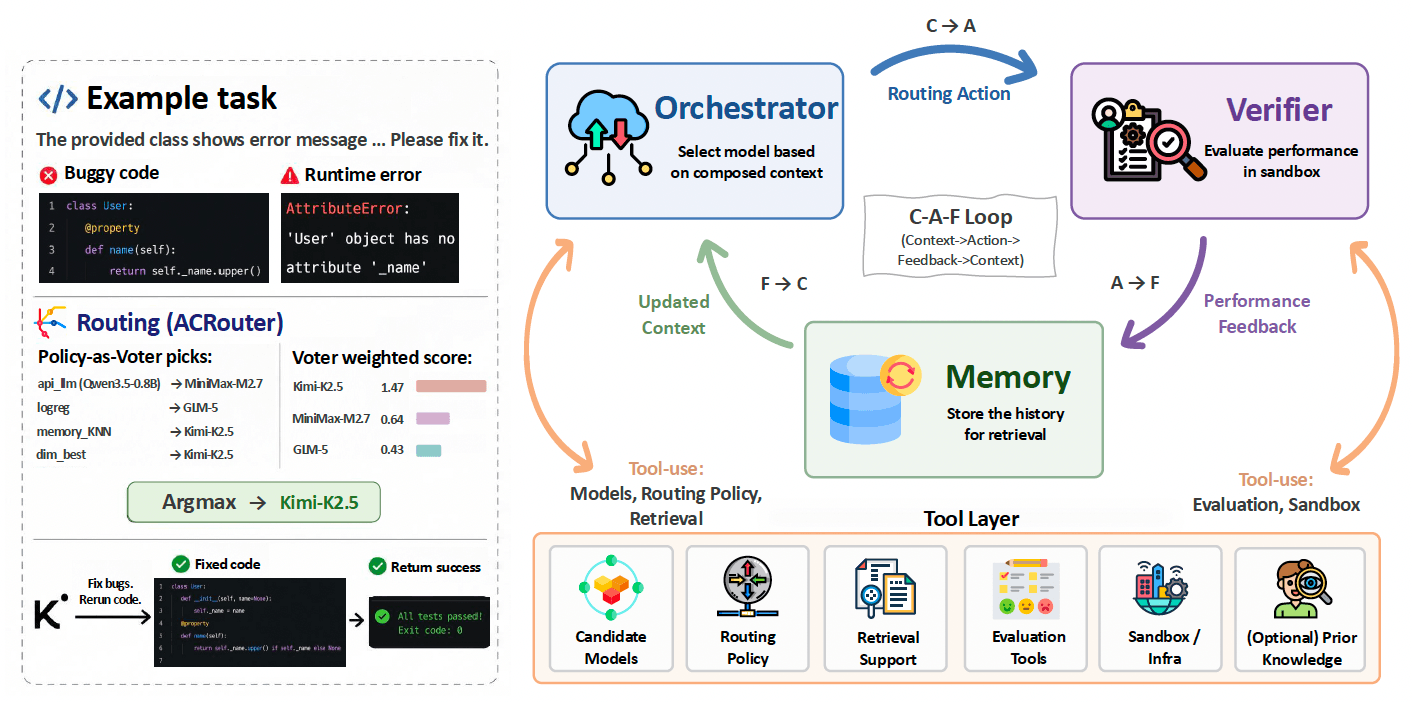
Another open-source framework is ACRouter, based on the Agent-as-a-Router paradigm. ACRouter solves the information deficit of static routing rules in dynamic environments by operating an autonomous Context-Action-Feedback loop.
The C-A-F loop relies on three interconnected components. First, a lightweight Orchestrator analyzes the incoming prompt alongside historical performance data retrieved from an internal Memory module.
The Orchestrator then routes the prompt to the optimal model, executing the action. Finally, a Verifier evaluates the model's output using objective metrics, such as unit tests for generated code, and writes the outcome back to the Memory module as feedback.
This continuous cycle allows the router to accumulate execution-grounded experience in production. When tested against elite models, including Claude Opus 4.6 and Qwen3-Max, ACRouter continuously improved by adapting automatically to out-of-distribution software tasks while pushing the cost/accuracy Pareto frontier.
The reality check: Limitations, step 0, and the smart AI stack
Routers bring a complexity premium to the AI stack. Local setups add infrastructure maintenance overhead, while cascading chains and agentic validation loops inherently introduce a latency tax.
Routing architectures also carry a strict verifiability constraint. They thrive on objective, binary signals, such as code passing a test suite, valid JSON schemas, or deterministic string parsing. Subjective tasks, like evaluating marketing copy or open-ended creative brainstorming, make verification and efficient routing difficult.
Because of this, gathering production feedback loops and building comprehensive evaluation pipelines must become a foundational, daily habit for your team. This internal groundwork is your "step 0."
The model landscape changes weekly, models commoditize, and the price-per-token continues to plunge. However, your internal evaluation datasets and historical prompt logs remain a permanent asset. This proprietary data is the fuel needed to power and future-proof your routing layer.
Elite engineering teams are not differentiated by the size of the frontier model they plug into but by their ability to orchestrate a multi-model ecosystem intelligently.