| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 4 min 59 sec | 🎖️ Top News
📌 Baseten
⚡️ Trending Signals
📌 AssemblyAI
📝 Top Papers
Rapid Response: Anthropic’s adaptive defense mechanism blocks new jailbreak attacks with minimal retraining.
LoRA vs Full Fine-tuning: Study analyzes the impact of LoRA on model generalization and its differences from full fine-tuning.
RAGCache: New method reduces RAG system latency by 4x and improves throughput
🧠 Python Tip |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| ChatGPT Desktop App | OpenAI announces ChatGPT access to all users on Windows, MacOS gets real-time assisstance |
⇧ 10,289 Likes |
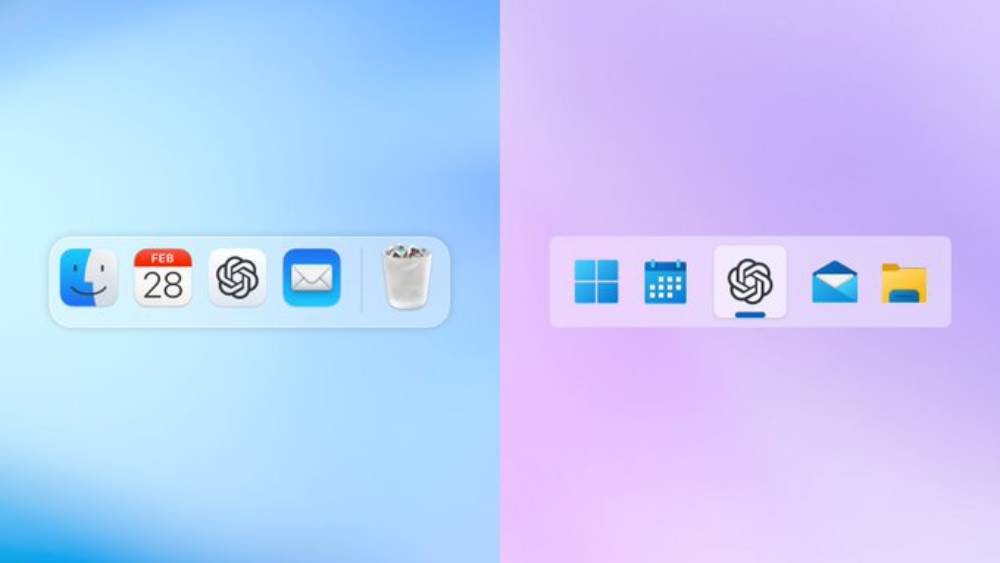 |
What's New | OpenAI released key updates to the ChatGPT desktop apps for Windows and MacOS.
ChatGPT for Windows is now available for all users with quick access via Alt + Space and companion windows that track tasks.
The MacOS update introduces a new level of interaction with users' environments. The core innovation of the MacOS update is that ChatGPT can now "see" the user's desktop and interact with specific applications.
Key Features
- Direct interaction with apps like VS Code, Xcode, Terminal, and iTerm
- 200 lines of terminal output visible to ChatGPT
- Ability to highlight specific code sections for focus
- Installation of extension for editor and terminal access
- Supports real-time guidance for coding and debugging
These features support direct interaction with the development environment, enhancing productivity by providing dynamic, context-specific guidance.
Setting Up for MacOS - Download the Mac Desktop app and VS Code if not already installed
- Install the extension (link starts download), open VS Code, press CMD + Shift + P, and type “Extensions: Install from VSIX”
- In ChatGPT, select “Work with Apps” and enable VS Code and Terminal access by clicking the “+” next to both options
|
|
|
Read more
|
|
|
|

| Run the fastest Whisper inference with Baseten | Baseten’s team built the fastest inference engine for Whisper, the open-source AI model for speech-to-text.
- Unmatched Speed: Transcribe 1 hour of audio in under 9 seconds
- Precision Transcriptions: Industry-best accuracy with tailored, domain-specific corrections
- Unbeatable Cost: Enjoy up to 80% savings on Whisper V3—our pricing beats any custom hardware provider
This is the fastest, most accurate, and lowest-cost Whisper inference available—even compared to custom hardware.
Engineering teams at companies like Bland AI and Patreon use Baseten’s Whisper deployments for secure, reliable, and HIPAA-compliant transcription. Run it on Baseten or self-host in your VPC. |
|
Learn more
| partner with us |
|
|
|
TRENDING SIGNALS
| Multi-modal Model |
|
⇧ 3,190 Likes | |
Agent |
|
⇧ 2,672 Likes | |
Prompt Engineering Tool |
|
⇧ 2,371 Likes | |
AI Application |
|
⇧ 1,293 Likes | |
AI Agents Adoption |
|
⇧ 607 Likes | | |
|
|
|
|
Transcribe Complex Audio with Unmatched Accuracy
| Universal-2 improves speech-to-text for complex audio. Capture alphanumerics, proper nouns, and specialized formats with high accuracy.
Get reliable, real-world transcriptions faster, and reduce errors in your audio data. |
Explore Universal-2 ↗️ |
|
|
|
TOP PAPERS
| LLM Adversarial Defense |
|
⇧ 1,251 Likes | Problem
Ensuring LLM safety against jailbreaks is challenging, with traditional methods failing to achieve full robustness. Attacks evolve rapidly, and existing defenses struggle to adapt to new strategies without extensive retraining.
Solution
Anthropic's Jailbreak Rapid Response introduces an adaptive defense mechanism that blocks new jailbreak classes after observing only a few examples. Using jailbreak proliferation, the method generates additional attack variants to fine-tune an input classifier, improving defense effectiveness.
Results
The approach reduces attack success rates by over 240× on previously detected jailbreaks and 15× on out-of-distribution attacks. The method scales effectively with improved proliferation quality, offering promising safety improvements for real-world LLMs. Anthropic has also open-sourced the benchmark, making it available on GitHub. |
| Model Fine-tuning |
|
| ⇧ 1,728 Likes | Problem
Low-Rank Adaptation (LoRA) achieves comparable performance to full fine-tuning with fewer trainable parameters, but it’s unclear if their learned solutions are truly equivalent. This raises concerns about the generalization capabilities of models fine-tuned with LoRA, especially when tested outside the adaptation task’s distribution.
Solution
This study analyzes the spectral properties of weight matrices from full fine-tuning and LoRA using singular value decomposition. It identifies that LoRA models introduce new high-ranking singular vectors, referred to as "intruder dimensions," which are absent in fully fine-tuned models. These dimensions impact the model’s generalization and adaptability.
Results
LoRA models with intruder dimensions perform similarly to fully fine-tuned models on the target task but show weaker generalization on out-of-distribution data. They also adapt less effectively to sequential tasks. Higher-rank LoRA models, which stabilize intruder dimensions, better mirror full fine-tuning, even when performing similarly on specific tasks. |
| Optimizing RAG |
|
⇧ 1,102 Likes | Problem
Retrieval-Augmented Generation (RAG) improves NLP tasks by combining large language models (LLMs) with external knowledge sources. However, RAG increases computation and memory costs due to long sequence generation, particularly caused by the knowledge injection process.
Solution
RAGCache addresses these challenges by dynamically caching intermediate knowledge states during retrieval. It organizes these states in a knowledge tree and stores them across GPU and host memory, applying a replacement policy optimized for LLM inference and RAG retrieval patterns. It also overlaps retrieval and inference to minimize latency.
Results
RAGCache reduces time to first token (TTFT) by up to 4x and improves throughput by up to 2.1x when integrated with vLLM and Faiss, demonstrating substantial improvements in both latency and throughput. These results show how RAGCache optimizes RAG system efficiency. | |
| |
| |
|
|
PYTHON TIP
| Speed Up Model Serialization | Saving and loading large models or datasets can be slow with Python's default pickle. A faster solution is using joblib, which is optimized for handling NumPy arrays and large objects efficiently.
Why This Worksjoblib employs optimized I/O and memory-mapping for numeric data, significantly outperforming pickle when serializing models or datasets. This is especially useful in ML workflows involving large objects.
Example |
from joblib import dump, load

# Save a model
dump(model, 'model.joblib')

# Load the model
loaded_model = load('model.joblib')
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. | | | |
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Work with us
|
|
|
|
|
