| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 6 min 14 sec | 🎖️ Top News
📌 coresignal
⚡️ Trending Signals
💻 Trending Repos
LTX-Video: Generates high-resolution, real-time videos from text, images, or video with multiscale pipelines and prompt control.
SurfSense: Customizable AI research agent integrating personal and external sources with RAG, podcasting, and local model support.
Void: open-source alternative to Cursor for using AI agents on codebases, with local model support.
🧠 How To
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| AI Evaluation | OpenAI unveils HealthBench, an open-source benchmark to test LLMs on 5000 real-world health task
| ⇧ 7,492 Likes |
| What's New |
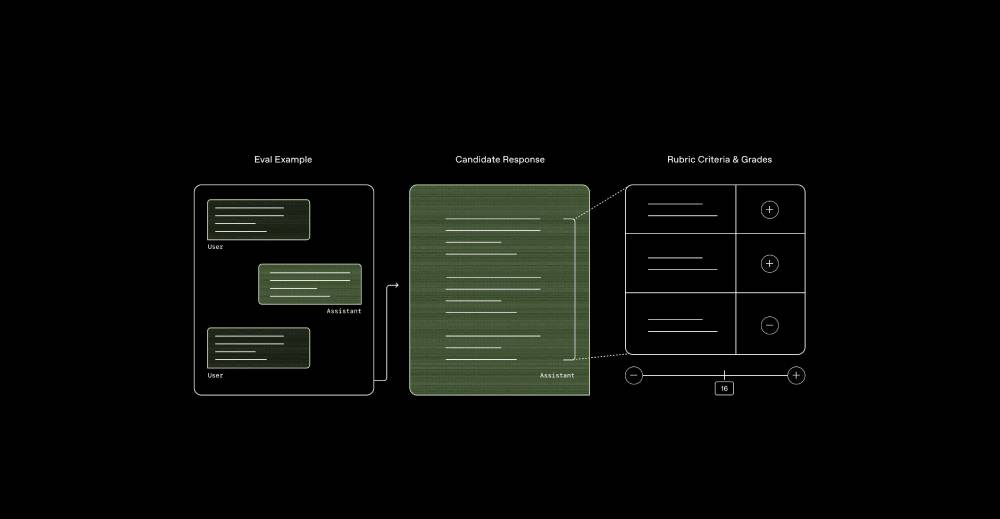
OpenAI has released HealthBench, a benchmark for evaluating AI in health contexts. The dataset includes 5,000 multi-turn conversations annotated with physician-written rubrics and evaluated using GPT-4.1. The benchmark covers a wide range of medical scenarios, providing a realistic assessment of model performance.
Structure and Dataset Design HealthBench evaluates models on realistic multi-turn health conversations.
5,000 conversations across diverse medical specialties and patient scenarios
Covers both synthetic and adversarial test cases
Each case includes a dialogue, prompt, model output, and rubric in structured JSON format
Rubrics contain 48,562 total criteria, covering relevance, accuracy, and reasoning
Scoring uses yes/no checks with weightings applied per criterion
Dataset spans 49 languages and supports both layperson and clinician perspectives
Developed with input from 262 physicians across 60 countries
Evaluation Pipeline
OpenAI uses GPT-4.1 as the grader for automated rubric-based scoring. Grading outputs include overall score, accuracy, reasoning, hallucination rate, and bias
Pipeline supports reproducibility with publicly available grader prompts and output formats
Evaluation runs end-to-end and integrates with any LLM using the same rubric structure
Grader results align with human physician ratings, based on OpenAI’s internal validation
Model Performance
The o4 model leads across key metrics compared to Claude 3.5 and Gemini 1.5 Pro.
Factual accuracy: o4 scores 77.2, Claude 67.7, Gemini 65.7
Reasoning: o4 scores 83.2, Claude 67.7, Gemini 66.5
Hallucination rate: o4 at 3.4%, Claude at 10.4%, Gemini at 11.3%
Dataset includes performance across chronic care, diagnosis, documentation, and follow-up scenarios
Comparison Against Physician Baselines
HealthBench includes comparisons between LLMs and physicians across evaluation criteria.
Physicians achieve higher accuracy but lower completeness on certain patient queries
LLMs exceed physician baselines on structured documentation and summarization tasks
Rubric structure enables direct side-by-side scoring on identical prompts
Comparative insights highlight model gaps and advantages in clinical reasoning
Domain Coverage and Themes
Each case is tagged with specific clinical themes and task types for targeted evaluation.
Dataset covers 14 task types, including diagnosis, education, and note generation
Themes include cardiology, dermatology, endocrinology, and 30+ additional specialties
Enables performance filtering by domain, task, and user type (lay or clinician)
Task types reflect real-world medical assistant and clinical workflow scenarios
Includes controls for resolution to manage cost-performance trade-offs
Usage and Access
You can test your own models and use the same evaluation setup OpenAI used.
Dataset and grader code available on GitHub under a research-use license
Users can swap the grader model or modify rubric weightings
All evaluations run offline using local or hosted LLMs
Each case includes metadata, prompt template, and gold standard rubric structure
Community Feedback
AI Wave
"A solid benchmark won’t replace clinical judgment, but it can help protect it from model bias. HealthBench feels like a strong move in the right direction."
Andrea Papini
"For the first time, an AI is not only more effective than doctors, but it is even more effective than doctors who help themselves using that same AI. Human are becoming a problem. They tell you that AI will be a tool, in reality we are already becoming limiting factors."
Ozan Unlu
"I think you missed the most critical point to be taken from this work: These models with or without physicians still have substantial room for improvement, especially when considering worst-case reliability. The progress is amazing but we still have a lot of work to do!"
| |
| Try now
|
|
|
|
| Now put our multi-source company data to work |
Collecting, cleaning, and enriching public B2B data takes years to perfect. We started working in 2016 and focus on delivering fresh web data in line with the highest privacy standards.
Today, you can skip the tedious data prep work and benefit from enriched, cleaned company data that integrates multiple sources into a single dataset.
Here's the deal: high-quality data from a single provider, delivered your way.
● Get 39M+ enriched company profiles
● Analyze 500+ data points and unlock new ways to generate insights
● Track headcount changes, tech stack, funding, salary data, and more
● Access as a dataset or via API – it's ready to go in the most convenient way
|
| Get started
| partner with us → |
|
|
|
TRENDING SIGNALS
| AI Tool |
|
⇧ 7,538 Likes | |
AI Models |
|
⇧ 2,629 Likes | |
Open-Source Infrastructure |
|
⇧ 1,836 Likes | |
General AI Agent | |
| ⇧ 2,836 Likes |
| Model Architecture |
|
⇧ 1,387 Like | | |
|
|
|
|
TRENDING REPOS
| Video Generation | |
☆ 5,247 Stars |
It is a DiT-based model for real-time video generation. Use distilled 2B models for 15× faster inference without classifier-free guidance. Run multiscale pipelines, keyframe conditioning, and video extensions. Supports ComfyUI and Diffusers. FP8 quantized models reduce VRAM needs. Output fidelity matches cinematic prompt detail. |
| Agents |
|
☆ 3,825 Stars |
SurfSense is an open-source research agent that connects to external sources like Slack, Notion, GitHub, and YouTube. It supports 150+ LLMs, 6000+ embedding models, and hybrid search using vector similarity and full-text search. It includes RAG as a service, private knowledge base support, and a cross-browser extension for secure content capture.
|
| AI Tools |
| ☆ 18,374 Stars |
Void is an open-source code editor for AI-driven development. It supports local model hosting, direct provider integration, and codebase agent workflows. It includes change tracking, checkpoint visualization, and secure data handling without data retention.
|
| |
| |
|
|
HOW TO
| Code Visualization |
Turn any GitHub repository into interactive diagrams |
Step 1
Run pip install gitdiagram.
Step 2
In your project folder, run gitdiagram.
Step 3
Check the gitdiagram_output folder for diagrams.
Step 4
Use flags like --output-dir or --max-depth to control output.
|
| Github repo
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
