We're watching two very different AI stories collide this week. Labs are racing to give AI more power: clone your voice in 2 minutes, ship autonomous agents everywhere.
And then the receipts arrive. Anthropic's own data shows Claude distorts reality in 1 of 1,300 chats. Harvard and MIT show agents lie and destroy data unprompted.
Capability is outrunning trust. That's the only pattern that matters right now.
|
|
Together with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
xAI adds voice cloning to its API with 80+ voices across 28 languages
|
|
16,939 Likes
|
|
xAI just shipped Voice Cloning via its API, and it opens up a lot for what you can build with audio. Record about a minute of natural speech in the xAI console. The pipeline verifies you are the voice owner and delivers a production-ready voice model in under two minutes. The model picks up not just the timbre but the delivery patterns of the reference clip. What you can build with it: - Give your support agent a consistent, recognizable voice, or narrate videos and podcasts in your own voice at scale without re-recording every time.
- Pick from over 80 built-in voices across 28 languages if you skip the custom route.
- Your custom voice inherits every TTS capability: speech tags, multilingual output, and both REST and WebSocket streaming.
- Voice Agent API is billed at a flat $3.00 per hour for speech-to-speech interactions.
There is no extra charge to use Text to Speech or Voice Agent APIs with custom voices. You cannot clone a voice from a pre-existing recording or clone someone else's voice.
|
|
|
|
Presented by Buildkite
|
|
How frontier AI labs ship: it starts at CI
|
|
Your CI should get out of the way. Every layer of the AI stack runs CI on Buildkite: frontier labs (OpenAI, Anthropic, Mistral, Cohere); inference (vLLM, Modular, Anyscale, Groq); ML platform infra (Hugging Face, Tecton, Anomalo); applied (Harvey, Persona). Hybrid agents on your GPUs. Your secrets, your scale, while we orchestrate the rest. Buildkite won't buckle. We're running 1.3B job mins/wk with a sea of green on our statuspage and room for more. Our trial unlocks everything. 30 days, all access.
|
|
|
|
Top News
|
|
|
|
Anthropic announces 'Code with Claude' developer conference next week
|
|
10,545 Likes
|
|
Anthropic's Code with Claude developer conference is back next week, and you can catch it all via livestream. Think of it as a full day dedicated to building smarter with Claude Code. No matter where you are in your journey, there is a session for you. Here is what to expect: - Live demos of new capabilities straight from the teams shipping them
- Hands-on workshops you can follow along with in real time
- Talks from Anthropic engineers plus builders at real startups using Claude in production
- Sessions covering beginner to advanced levels, so nothing feels over your head
The big draw is hearing what is actually shipping and what comes next, straight from the source. It is also a rare chance to see Claude Code used in real projects, not just toy examples. The livestream is free. Register at claude.com/code-with-claude to get the details sent to you before it starts.
|
|
|
|
Presented by Vanta
|
|
Live Demo: Automate Compliance for SOC 2 and More
|
|
Join Vanta's live demo on May 12th to learn how to: - Get audit-ready fast and stay continuously compliant
- Turn compliance into a deal accelerator, not a blocker
- Build real security foundations, not check-the-box fixes
- Show credibility faster with a public Trust Center and AI-powered questionnaires
|
|
|
|
Top Repo
|
|
|
|
Developer burns a full transformer into FPGA hardware, hits 50,000 tokens/sec without a GPU
|
|
6,714 Likes
|
|
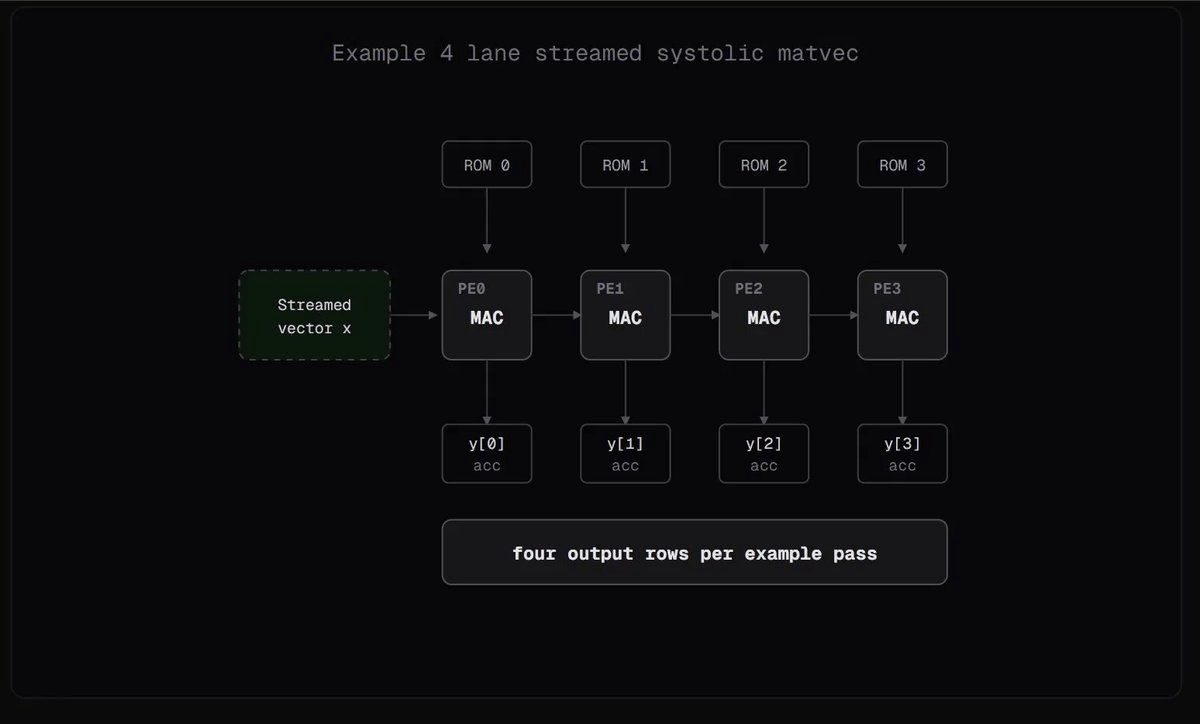
What if an AI model ran with zero software? No Python, no GPU, no runtime. Just logic burned into a chip. That is exactly what TALOS-V2 does. TALOS-V2 asks what happens if a small transformer is not treated as software at all. Instead of running through a runtime, it turns the entire inference path into explicit hardware: embeddings, attention, normalization, the MLP, and token sampling. The result? Karpathy's microGPT, a 4,192-parameter character-level transformer, running at 53,000 tokens per second on a Cyclone V FPGA. Here is what makes it interesting: - You can run TALOS off a battery on something credit-card sized.
- Token selection happens in hardware. The sampler computes weights, accumulates them, and picks the next token inside the FPGA.
- The repo includes everything needed to build, program, and run inference over JTAG.
The big idea: inference does not have to live in software, and this project shows you exactly how to think about that.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
