Hey, | Welcome to this week's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries ensure you're always up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior |
|
|
|
IN TODAY'S EMAIL | Read Time: 4 min 32 sec |
|
|
|
TOP NEWS | Grok-1 is Now Open-Source: The Largest Open LLM |  | What's New? | xAI finally open-source Grok-1 making it the largest open LLM ever built.
With 314-billion parameters, the Mixture of Experts (MoE) model utilizes 86 billion active parameters at any given time, enhancing its processing capabilities.
Unlike traditional models, Grok-1 employs Rotary Embeddings, avoiding fixed positional limitations and supporting a more dynamic data interpretation.
Key Specifications: - Parameters: 314 billion, with 25% of weights active per token.
- Architecture: Mixture of 8 Experts, using 2 per token.
- Layers: 64 transformer layers, integrating multihead attention and dense blocks.
- Tokenization: Utilizes a SentencePiece tokenizer, vocab size of 131,072.
- Embedding and Positional Encoding: 6,144 embedding size, matching rotary positional embeddings.
- Attention: 48 heads for queries, 8 for keys/values, each with a size of 128.
- Context Length: Capable of processing 8,192 tokens with bf16 precision.
Performance Metrics: - Outperforms LLaMa 2 70B and Mixtral 8x7B with a MMLU score of 73%, showcasing its efficiency and accuracy in various tests.
Implementation Details: - Requires significant GPU resources due to its size.
- Uses an inefficient MoE layer implementation to avoid custom kernel needs, focusing on model correctness validation.
- The model supports activation sharding and 8-bit quantization to optimize performance.
Open-Source Availability: - Released under the Apache 2.0 license, Grok-1’s weights and architecture are accessible for community use and contribution.
| | View repo |
|
|
|
 | The container-based GPU cloud developed by Latitude.sh | Launchpad efficiently leverages every piece of the hardware to start almost instantly, bringing unrelenting performance that makes other tools feel just too slow. Effortlessly fine-tune and deploy your Machine Learning models with hourly billing starting at $1.32 / hr.
The containers are provisioned directly on bare metal, which means their resources are fully dedicated. All containers are powered by 16 CPUs, 185 GB of RAM, 1 TB of NVMe Storage, and a single GPU, which you can choose from : | | Join the beta | partner with us |
|
|
|
TOP REPOS | --------------------- Open-Sora helps you generate high-quality videos efficiently via diffusion models, providing open-source tools for data preprocessing, training with acceleration techniques like sequence parallelism, and inference. It leverages transformer architectures like STDiT, optimized components like flash attention, VAEs, and text encoding with T5. Model weights for resolutions up to 512x512 are available. | | --------------------- Unsloth helps you finetune large language models like Mistral, Gemma, and Llama 2-5x faster using up to 70% less memory on NVIDIA GPUs. It employs techniques like LoRA, bitsandbytes, and custom Triton kernels for efficient training acceleration without losing accuracy. It supports conversational models, raw text, and direct preference optimization (DPO) for reward modeling. | | --------------------- PrivateGPT helps you build private, context-aware AI applications using large language models on local documents without internet. It provides an API for ingesting documents, generating embeddings, retrieving relevant context, and generating responses using retrieval-augmented generation pipelines based on LlamaIndex abstractions. It supports completions, streaming, and extends OpenAI API standards. | |
| |
|
|
Add an AI assistant to your product this quarter | Enable your users to interact with your product through a conversational interface built by industry experts. Spine AI’s copilots bring workflow automation, analytics and advanced search to your product with unparalleled ease with little effort from your team.
Book a demo ↗️ |
|
|
|
TOP PAPER | Apple Releases New Multimodal Models: MM1 Family | 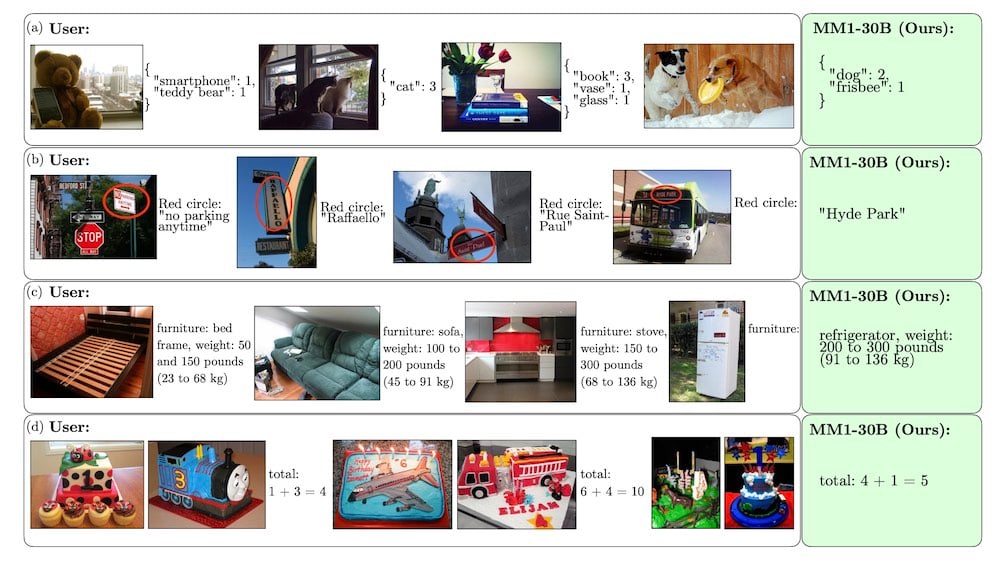 | What's New? | Apple has released MM1, a new family of multimodal AI models designed for processing visual and textual data. The release includes detailed information unusual for Apple. Model Composition: MM1 encompasses models with up to 30 billion parameters, trained on data including image captions, combined image-text, and text-only datasets.
Learning Efficiency: The 30 billion parameter version shows strong capabilities in few-shot learning, indicating effective learning from limited examples.
Benchmarking: MM1 competes with existing models like GPT-4V and Gemini Pro in pre-training and fine-tuning performance.
Technical Details: - Performance increases significantly with enhancements in the image encoder and adjustments in image resolution.
- Optimal data combination for training includes image-caption, interleaved image-text, and text-only data.
- The vision-language connector has a smaller effect on performance compared to other factors.
Performance Metrics: The MM1-30B model achieves a 39.4 score in zero-shot settings and 44.4 in eight-shot settings on the MathVista benchmark, demonstrating strong few-shot and reasoning abilities.
| | View research |
|
|
|
TOP OF REDDIT | | | ⇧ 933 | You can see cached snippets in Bing and DuckduckGo. Search for "OpenAI blog gpt-4.5 turbo" | 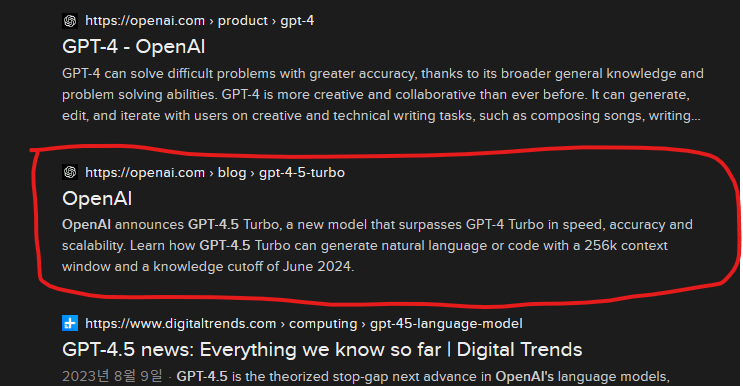 | | | | ⇧ 872 | | | | ⇧ 283 | I managed to find 8 bugs in Google's Gemma implementation in multiple repos! This caused finetuning runs to not work correctly. The full list of issues include: Must add <bos> or else losses will be very high. There’s a typo for model in the technical report!
sqrt(3072)=55.4256 but bfloat16 is 55.5. Layernorm (w+1) must be in float32. Keras mixed_bfloat16 RoPE is wrong. RoPE is sensitive to y*(1/x) vs y/x. RoPE should be float32 - already pushed to transformers 4.38.2. GELU should be approx tanh not exact.
| |
| |
|
|
| | Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics. | | Thank You. |
| | Want to promote your company, product, job, or event to 175,000+ AI researchers and engineers? You can reach out here. | |
|
|
|
|
