Hey, | Welcome to today's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries are there to keep you up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior | |
|
|
IN TODAY'S SIGNAL
| Top Paper: Meta's game-changing Multi-Token prediction
2 Top News: Breakthrough in MLPs and OpenAI going after Google
5 Trending Signals
3 Trending HuggingFace Spaces: OpenBioLLM, Open Med LLM Leaderboard and Hyper-SD. | Read Time: 5 min 12 sec |
|
|
|
Enjoying this newsletter?
Please forward it to a friend or colleague. It helps us keep this content free.
|
|
|
|
TOP PAPER
| Language Models | Meta's New Groundbreaking Paper on Multi-Token Prediction for Better and Faster LLMs |
⇧ 1902 Likes |
 |
Most current large language models are trained with a next-token prediction loss. However, they require large amount of data and often fail to capture longer-term dependencies effectively.
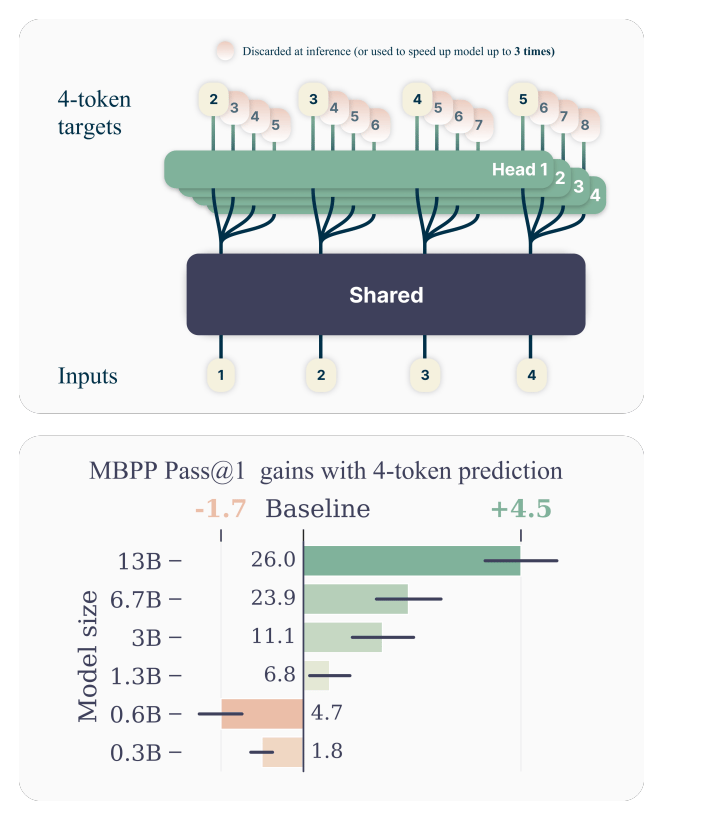
Meta's new groundbreaking paper "Better & Faster Large Language Models via Multi-token Prediction" suggests that training language models to predict multiple future tokens at once results in higher sample efficiency.
Performance:
Enhanced Efficiency: Multi-token prediction improves sample efficiency and speeds up inference times by up to 3x, particularly with larger models and batch sizes.
Better Performance on Benchmarks: This technique shows substantial improvement over traditional next-token prediction models on coding tasks and generative benchmarks.
Scalability Benefits: The benefits of multi-token prediction become more significant as model size increases, which implies greater improvements for larger models.
Robustness Across Epochs: Using Multi-token prediction maintains performance advantages even when models are trained for multiple epochs, which demonstrates robustness and durability of training gains. How it works:
- Overall architecture: It consists of a common trunk that processes the input sequence to generate a latent representation of the observed context. On top of that, multiple output heads are each responsible for predicting a different future token simultaneously and independently.
- Multi-token Prediction Task: Instead of predicting just the next token, the model predicts several future tokens from each position in the input sequence. Each output head makes its prediction independently based on the shared context provided by the trunk.
- Training Process: During training, the model is optimized for predicting each of the future tokens independently. This approach trains the model to improve its predictions by considering multiple future outcomes at each step. The predictions are generated in parallel across the multiple heads, so this doesn’t add any computation overhead.
- Efficient Inference: At inference time, the model can use the trained output heads to generate multiple tokens at once, speeding up the process.
| Community Feedback |
TDM (e/λ)
A significant takeaway from the Multi-token prediction paper isn't just its speed (which would be underwhelming on its own) but that predicting more than one token at a time also enhances the model’s accuracy across various coding evaluations. |
Charlie Greenman
This would mean most likely with this architecture AI can not only be 3 times faster, but 3 times cheaper. |
|
Read the paper
|
|
|
|
| Get On-demand Instances in Seconds | Accelerate your training and inference workloads with dedicated GPU instances powered by NVIDIA’s H100 Tensor Core available at Latitude.sh's platform.
With pre-installed AI software, high-performance networking, and enterprise-grade hardware, you get from zero to training your LLMs with just a few clicks. |
|
GET MY GPUs
| partner with us → |
|
|
|
TOP NEWS
| Research |
|
⇧ 16393 Likes |
A new paper has taken the AI industry by storm, introducing a novel neural network, Kolmogorov-Arnold Networks (KANs), which replaces MLPs' fixed activation functions with learnable ones on weights, eliminating linear weights.
KANs enhance accuracy, interpretability, use significantly fewer parameters (200 vs. 300,000 in some MLPs), and effectively prevent catastrophic forgetting. However, their complex activation functions demand more computational resources. | |
Industry |
|
⇧ 1012 Likes |
OpenAI's SSL certificate logs confirm the creation of search . chatgpt . com, indicating the development of a web search product. This service, likely powered by Microsoft Bing, leverages OpenAI's GPT-4, customized for search. The integration is supported by OpenAI's existing web crawler, GPTBot, and the Browse with Bing feature available to ChatGPT Plus users. | |
|
|
|
|
Learn AI/ML From Experts in Just 2 Weeks
| Join a class of experienced software engineers and level up your machine learning skills. After two intensive weeks, you’ll have a first-principles understanding of ML from concept to production and be ready solve problems with ML. This course is deeply technical, requires a full time commitment, and is only open to experienced developers. |
Apply now ↗️ |
|
|
|
TRENDING SIGNALS
| iOS |
| ⇧ 1039 Likes |
| Browser |
| ⇧ 1572 Likes |
| Multimodal Models |
| ⇧ 2290 Likes |
| LLMs |
| ⇧ 1251 Likes |
| Multimodal Models |
|
⇧ 1578 Likes | | |
|
|
|
|
TOP OF HUGGINGFACE
| Specialized Model |
| ⇩ 3,915 Downloads |
OpenBioLLM-8B is an advanced open source language model designed specifically for the biomedical domain. Developed by Saama AI Labs, this model was fine-tuned on a vast corpus of high-quality biomedical data from the powerful foundations of the Meta-Llama-3-8B and Meta-Llama-3-8B models.
The 70B parameter model outperforms GPT-4, Gemini, Meditron-70B, and Med-PaLM 1 and 2. OpenBioLLM-8B represents an important step forward in democratizing advanced language AI for the biomedical community |
| Leaderboard |
| ⇩ 500 Downloads |
The Open Medical LLM Leaderboard aims to track, rank and evaluate the performance of large language models (LLMs) on medical question answering tasks.
It evaluates LLMs across a diverse array of medical datasets, including MedQA (USMLE), PubMedQA, MedMCQA, and subsets of MMLU related to medicine and biology. Theses datasets contain multiple-choice and open-ended questions that require medical reasoning and understanding.
The OpenBio-LLM-70B is the leading model according to this benchmark, yet the recent Med-Gemini model is still not included in the leaderboard. | |
Text-to-Image Model |
| ⇩ 48,621 Downloads |
Hyper-SD is one of the new State-of-the-Art diffusion model acceleration techniques. It's a new framework that allows for high fidelity in step compression and mitigates performance losses for Diffusion Models distillation.
In this HF Space, the models distilled from SDXL Base 1.0 and Stable-Diffusion v1-5 are released. Multiple demos are available for testing, such as the Hyper-SD Scribble demo and the Hyper-SDXL One-step Text-to-Image demo. Model checkpoints and indications for usage are also provided in the model card.
| | |
| |
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics.
|
|
|
|
Want to promote your company, product, job, or event to 180,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|


