Today's theme is simple: bigger is no longer better. Google wraps your PDFs into TikTok-style videos, and a 7M parameter model quietly embarrasses frontier LLMs on reasoning at 1/10,000th the cost.
The industry spent years chasing scale. Now the wins are coming from smarter inference, not bigger models. Same pattern with robots borrowing audio codec tricks for 27x token compression.
We're entering the efficiency era. And honestly, it's more exciting.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Google NotebookLM now turns complex documents into 60-second vertical videos
|
|
6,807 Likes
|
|
NotebookLM Short Video Overviews just dropped, and it's basically TikTok for your study notes. Upload any document, and it spits out a 60-second vertical video that breaks down a concept with narration and animations. No editing, no scripting. Just upload and generate. Here's how it works under the hood: Nano Banana 2 Lite, officially Gemini 3.1 Flash-Lite Image, is Google's fastest image generation model, hitting 4-second image generation. Speed is the whole point. Fast generation means you can make a bunch of these back to back, like scrolling a feed. What you can actually do with it: - Turn a dense PDF or research paper into a quick visual explainer
- Generate multiple videos per notebook, each focused on a different concept
- Download and share the videos with teammates
Short Video Overviews only support English and are available to Google AI Ultra and Pro subscribers ages 18+. Free-plan users will get access too, confirmed by Google, but no date yet.
|
|
|
|
Presented by Reducto
|
|
Reducto ranks #1 in long doc extraction benchmark
|
|
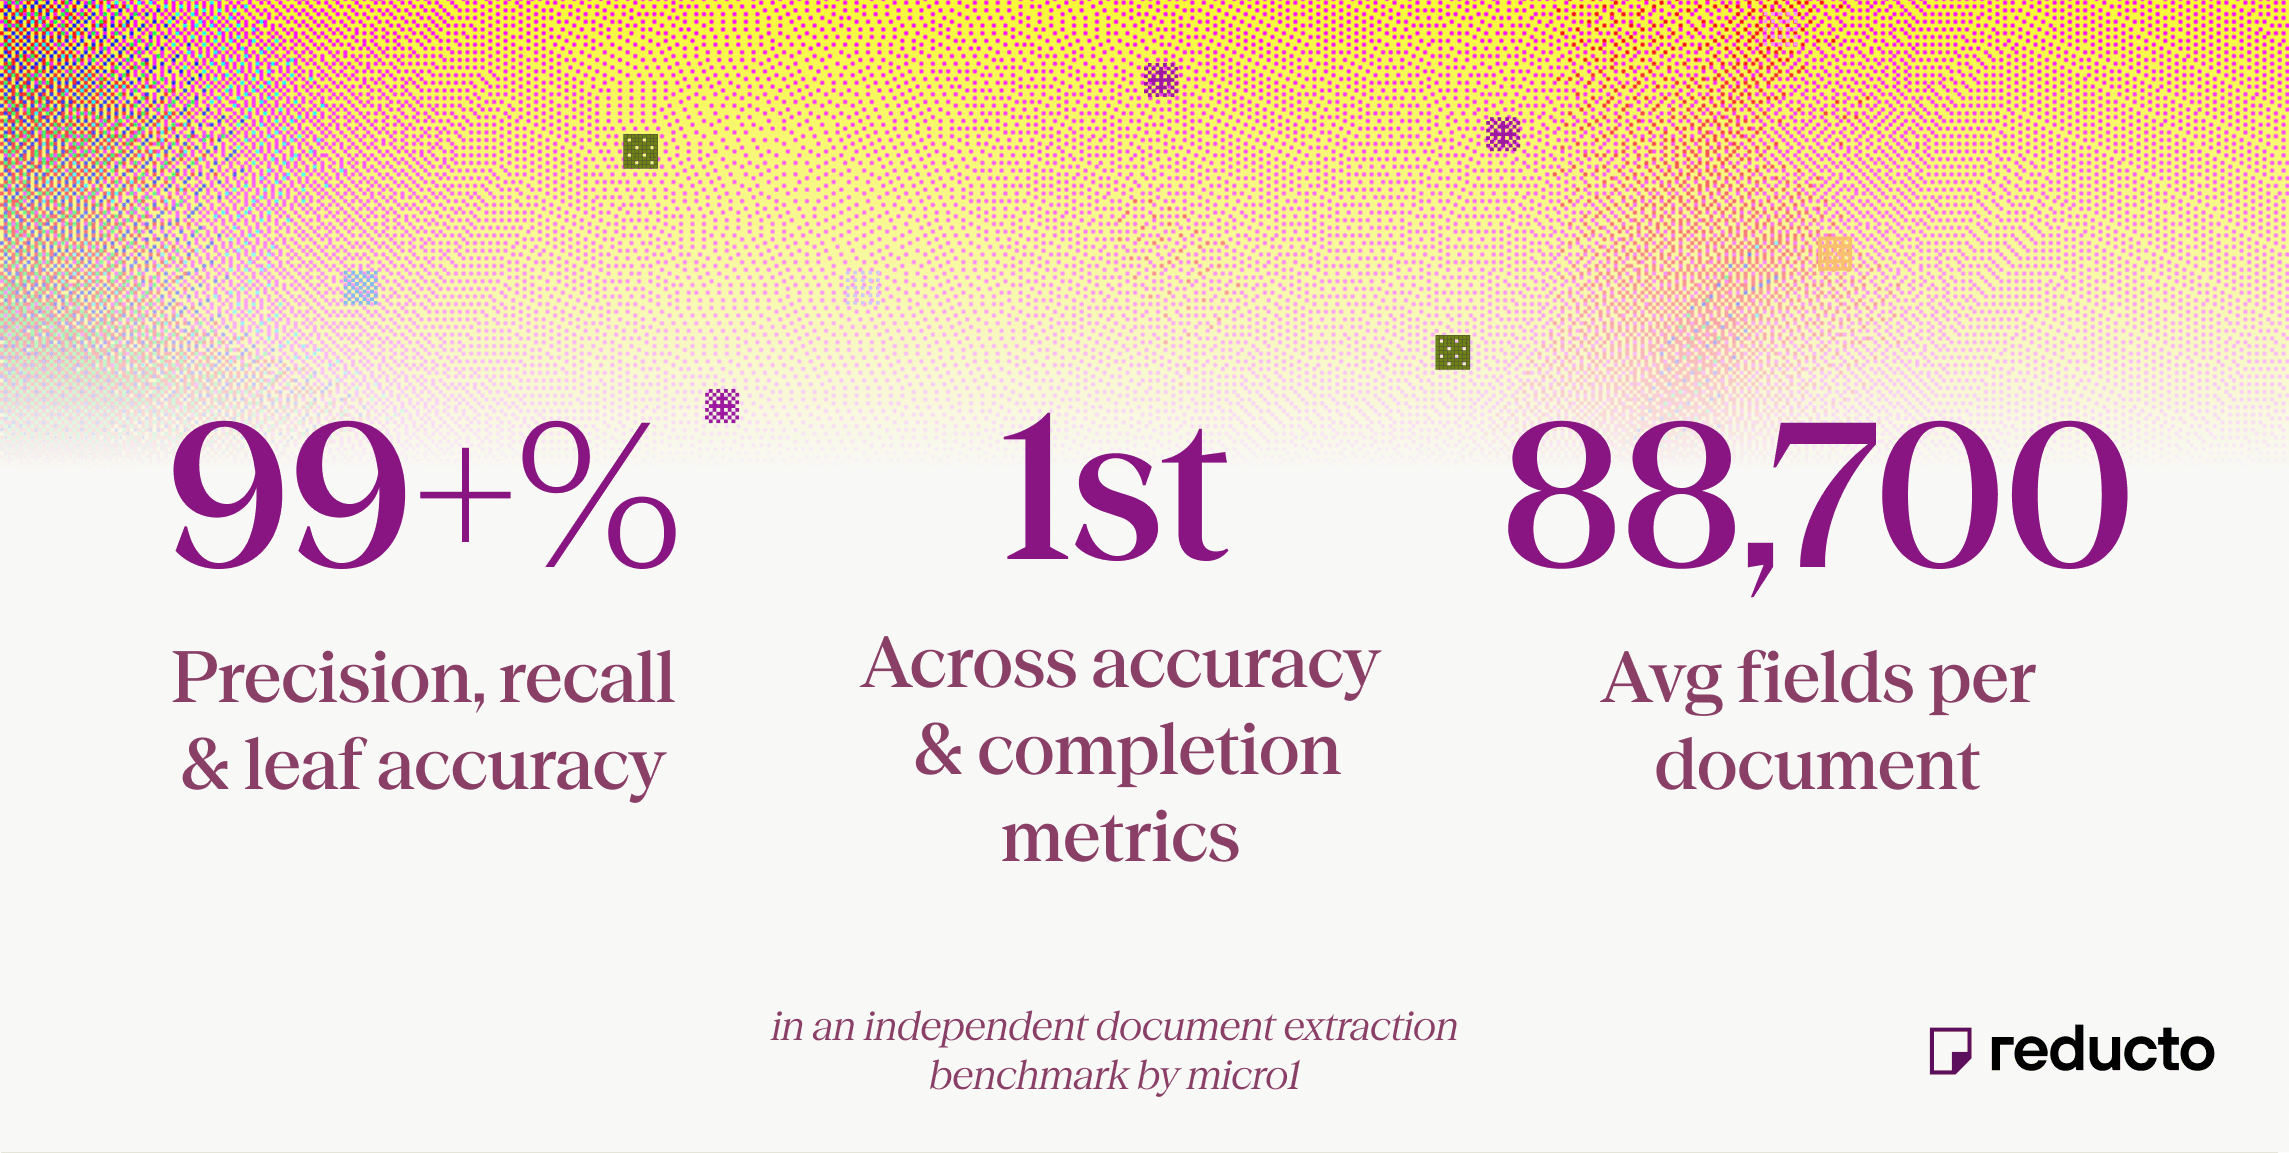
Reducto Deep Extract turns long, dense PDFs into structured data through an API developers can build on. In micro1’s independent LongExtractBench, on documents averaging 350+ pages and 88,000+ fields each, Reducto ranked first overall with 99.6% precision, 99.6% recall, 99.3% leaf accuracy, and 0 failures.
Send a schema, get clean JSON back, and test it on invoices, claims, financial statements, and other PDFs that break standard OCR or model-only pipelines.
|
|
|
|
Top Model
|
|
|
|
National Design Studio releases a 14.7MB on-device model that strips personal data before it reaches any server
|
|
6,706 Likes
|
|
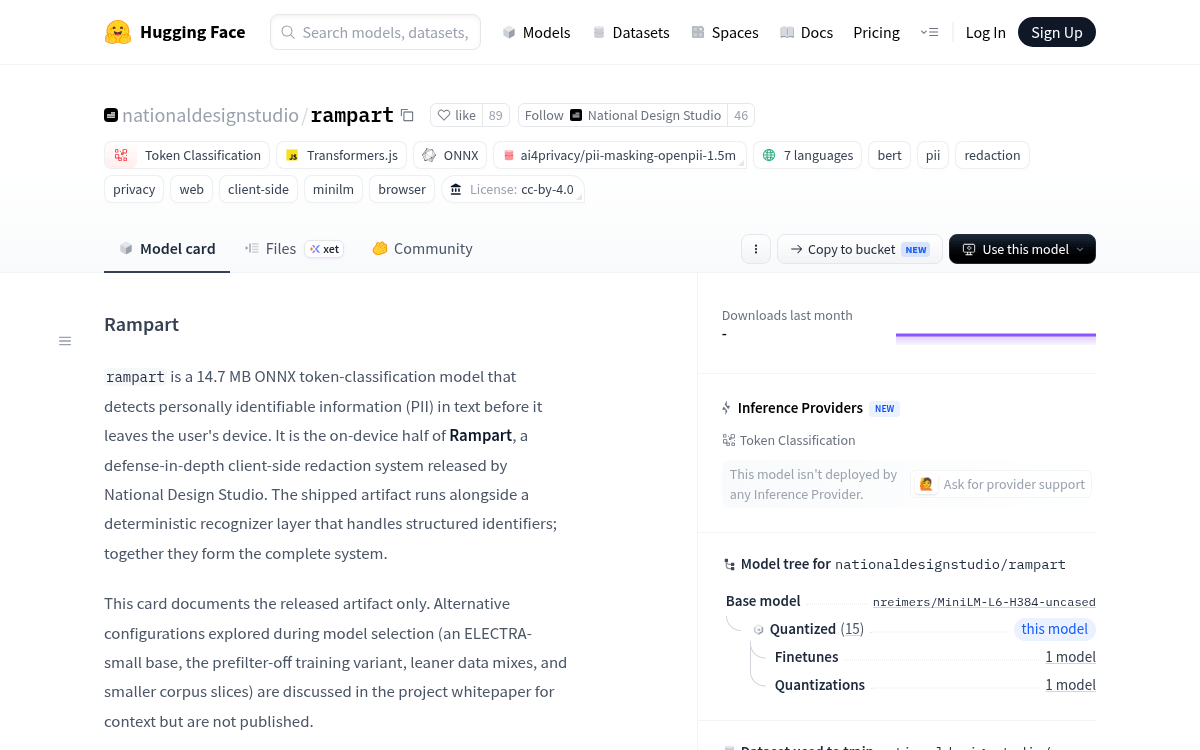
Every time you type something personal into an AI chatbot, that text flies off to a server. Rampart stops that. It's a tiny 14.7MB model that runs entirely in your browser, scanning your text and swapping out sensitive info before anything gets sent. So "My name is Alex Rivera and my SSN is 472-81-0094" becomes "My name is [GIVEN_NAME_1] [SURNAME_1] and my SSN is [SSN_1]." The AI still understands your request. Your real data never leaves your device. Here's what it catches: - Names, addresses, phone numbers, passport and license numbers
- SSNs and credit cards via a separate rule-based checker with checksum validation
- Works across 7 languages: English, Spanish, French, German, Italian, Portuguese, Dutch
It hits 98.42% recall on private terms, runs at 3.9ms in the browser on WebGPU, and ships as an npm package. Just call
createGuard()
and you're live. It's open source under CC BY 4.0 on HuggingFace.
|
|
|
|
Presented by CopilotKit
|
|
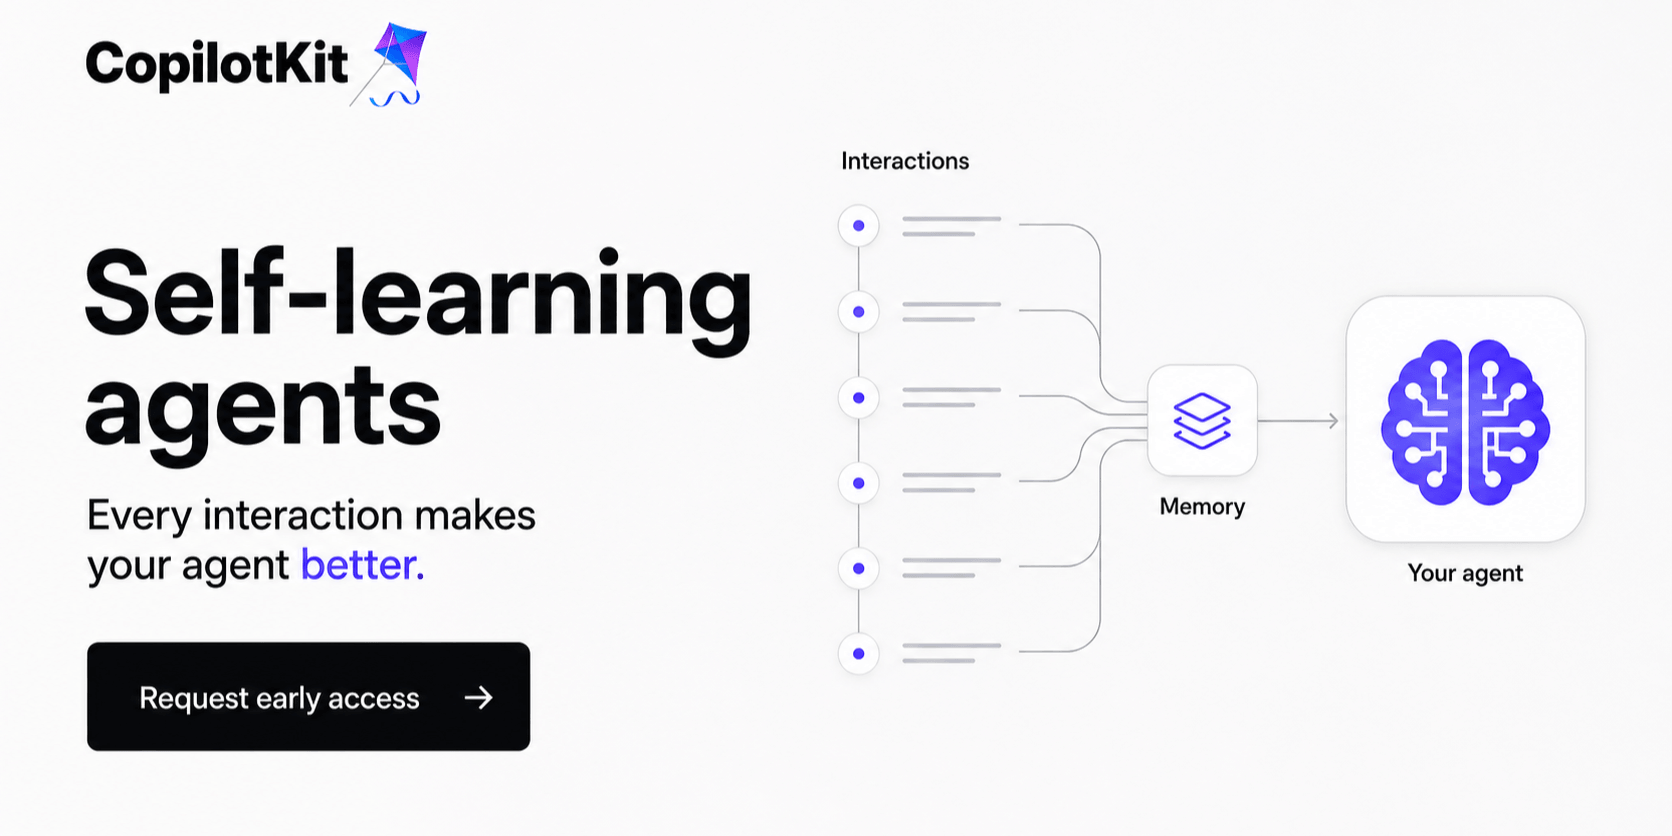
Your agent should learn from every interaction.
|
|
Each one is a signal for improvement. CopilotKit is the only product that observes both Agent and User interactions by Continuous Learning from Human Feedback. Made possible via the open AG-UI protocol. Self learning turns every user correction and preference into a more knowledgeable asset for your product.
|
|
|
|
Top Model
|
|
|
|
Mitsua diffusion model trained only on copyright-free images is now on Hugging Face
|
|
2,424 Likes
|
|
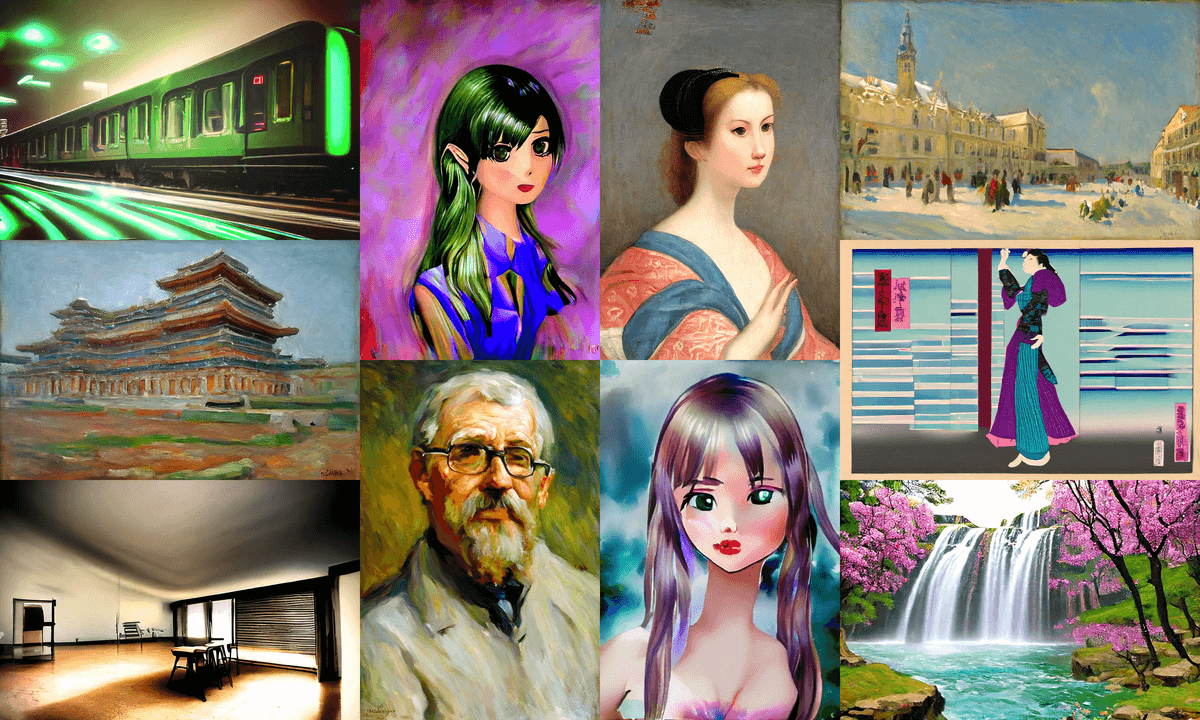
Mitsua Diffusion One is a text-to-image AI model trained entirely on public domain and CC0 images. No scraped web data. No copyright drama. Just clean, legal training data. The catch? It's honest about its limits. The model was built from scratch using roughly 11 million images from sources like the Met, Smithsonian, Flickr CC0, and Wikimedia Commons. Here's what makes it useful to you: - Fully copyright-safe outputs you can use commercially
- Training data list is fully public, so you know exactly what went in
- A base checkpoint is available specifically for fine-tuning
- Licensed under Mitsua Open RAIL-M, allowing commercial use
Image quality is low right now. But that's actually the point. Playing with it shows you firsthand why data volume and diversity matter so much in AI training. You can grab it on HuggingFace under the Mitsua org and start experimenting today.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
