Hey | Welcome back to AlphaSignal, where we bring you the latest developments in the world of AI.
In the past few days 1,500+ AI papers have been released, and among them, our model has picked the six.
Lets now dive straight into the papers!
Lior |
|
|
|
| IN TODAY'S SUMMARY | Chain of Code
Sequential Modeling
Magicoder
Other notable papers
Reading time: 3 min 12 sec |
|
|
|
| TOP PUBLICATION | Chain of Code: Reasoning with a Language Model-Augmented Code Emulator | Deepmind: Chengshu Li, Jacky Liang, Andy Zeng, Xinyun Chen, Karol Hausman, Dorsa Sadigh, Sergey Levine, Li Fei-Fei, Fei Xia, Brian Ichter | 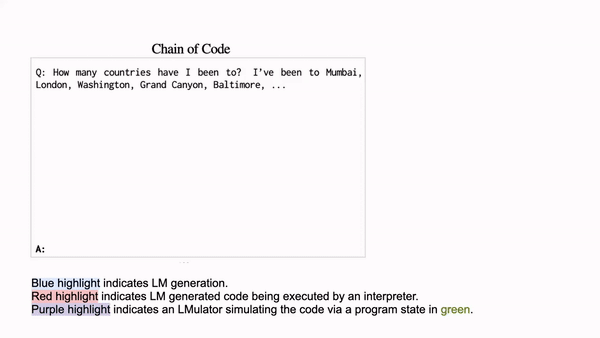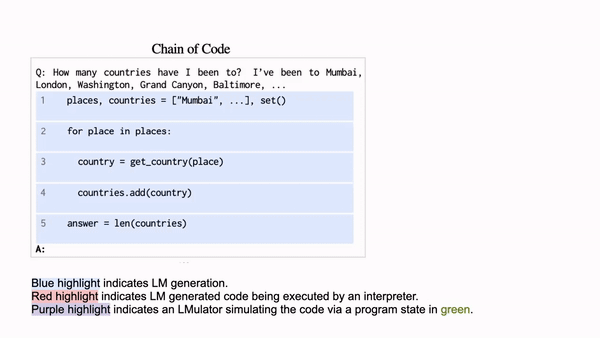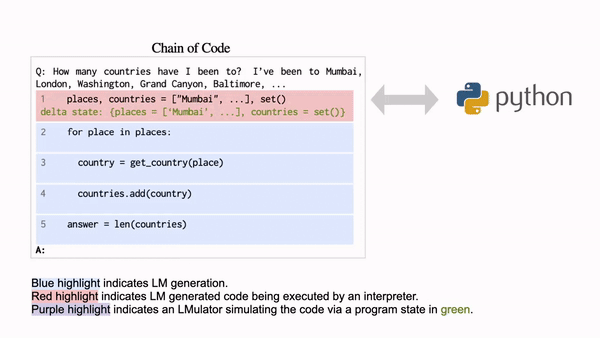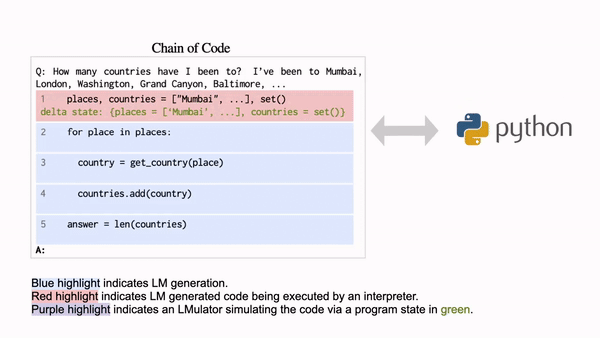 | What’s New | Chain of Code (CoT) significantly enhances language models' (LMs) reasoning capabilities by integrating code emulation, achieving a notable 12% improvement in performance over previous methods. | Problem | Traditional LMs face challenges in accurately processing complex logic and linguistic tasks, especially when these tasks require understanding and manipulating code-like structures. | Solution | CoT addresses this by allowing LMs to format tasks as pseudocode, which is then interpreted by a specialized emulator. This 'LMulator' effectively simulates code execution, providing a more robust reasoning framework for LMs. | Results | CoT's effectiveness is demonstrated through its performance on the BIG-Bench Hard benchmark, where it achieves an 84% success rate, outperforming the previous Chain of Thought method by 12%. This showcases its ability to broaden the range of reasoning tasks LMs can handle. | | Read the paper |
|
|
|
|  | Still struggling to bill for AI and LLM tools?
Leave it to Orb. | Charging by tokens or credits? We’ve got you covered.
Whichever pricing model you choose - package, matrix, tiered - Orb makes it easy to implement.
Just choose your pricing model and billable metric and you’re done.
Companies like Vercel, Replit, and Airbyte trust Orb to track consumption, prevent fraud, and align pricing to value (even down to GPU runtime), so they can build the products we all know and love, instead.
Special Offer: The first 10 qualified AlphaSignal readers to sign up get a free trial for Orb. | | Try orb free |
|
|
|
| TOP PUBLICATION | Sequential Modeling Enables Scalable Learning for Large Vision Models | Yutong Bai, Xinyang Geng, Karttikeya Mangalam, Amir Bar, Alan Yuille, Trevor Darrell, Jitendra Malik, Alexei A Efros | | Repo | 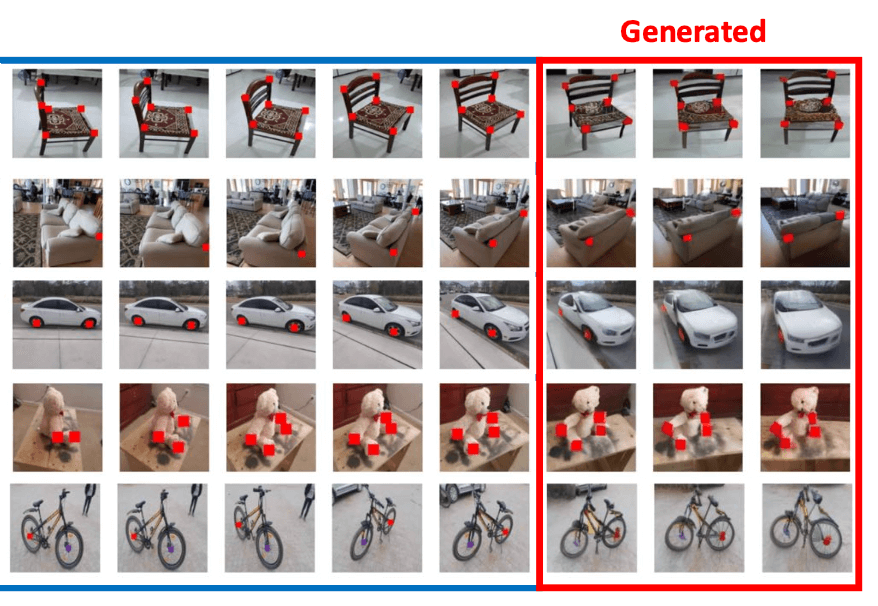 | What's New | The authors introduce a visual language model (LVM) trained on 1.64 billion unlabeled images to perform conditional image generation through visual prompting at test time. | Problem | Traditional vision models rely heavily on language data, limiting their direct interpretation of visual information. This research tackles the need for a more direct, pixel-based understanding in vision models. | Solution | The authors tokenize raw images into discrete visual tokens using VQGAN, concatenate tokens from images and annotations into “visual sentences”, and train a 3 billion parameter Transformer model to predict the next token. | Results | The LVM model demonstrates strong scalability as model size and data diversity increase. It can perform visual reasoning for various downstream tasks through suitable visual prompt construction at test time, including video prediction (49.8 perplexity), segmentation (50.8 mIOU), and object detection (49.6 mIOU). | | Read the paper |
|
|
|
| TOP PUBLICATION | Magicoder: Source Code Is All You Need | Yuxiang Wei, Zhe Wang, Jiawei Liu, Yifeng Ding, Lingming Zhang | 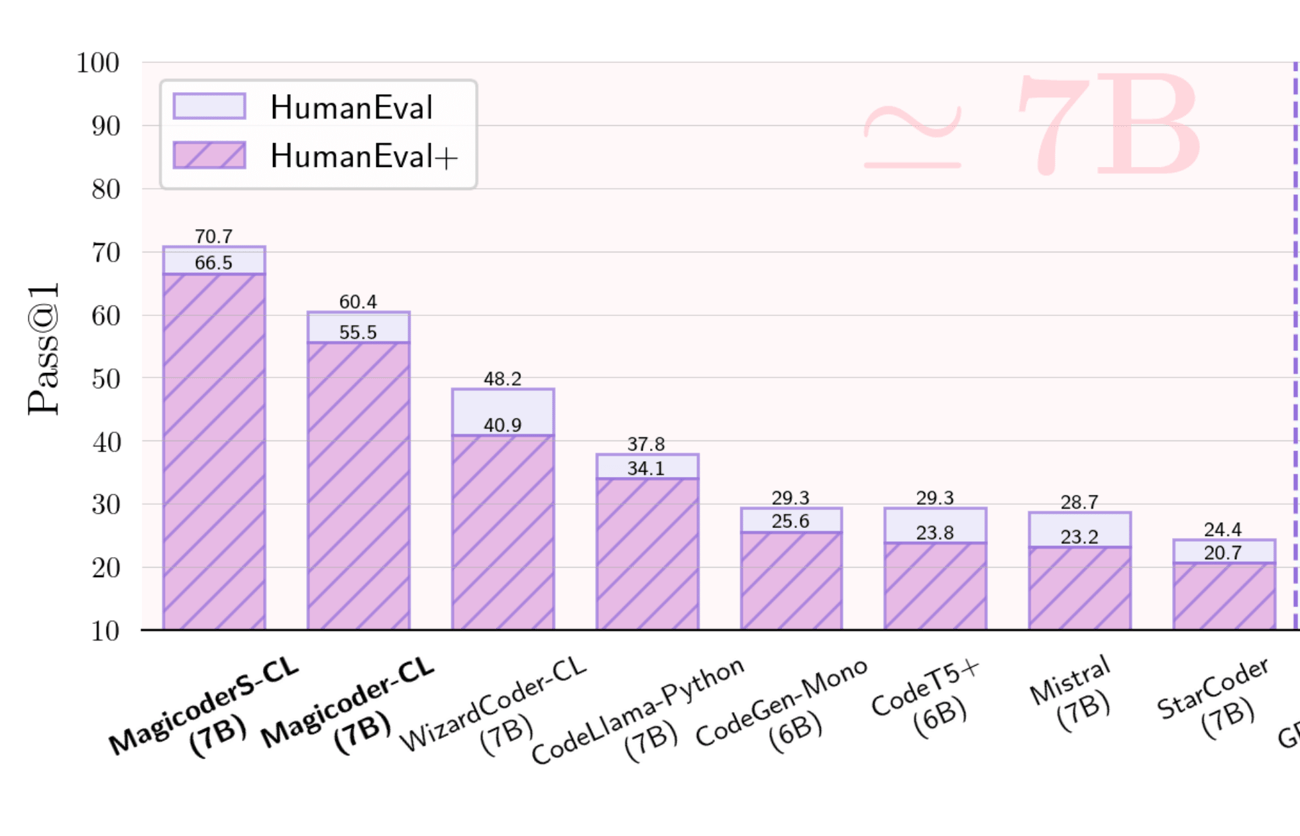 | What's New | Magicoder introduces a series of Large Language Models (LLMs) for code, excelling in a range of coding benchmarks. Its novel approach uses open-source code snippets for high-quality data generation. | Problem | The project addresses the issue of bias in synthetic data generated by LLMs. This bias limits the diversity and realism of the data, impacting the quality of machine learning models. | Solution | Researchers developed OSS-Instruct, a method to integrate open-source code into LLMs. This approach enriches synthetic instruction data, leading to more diverse and realistic outputs. They combined this with existing methods to create an enhanced Magicoder model. | Results | Magicoder outperforms top code models, including surpassing ChatGPT on HumanEval+ (66.5 vs. 65.9 in pass@1). It demonstrates superior performance in Python text-to-code generation, multilingual coding, and data-science program completion. | | Read the paper | |
|
|
|
| “Here's the paper you need to read understand today” - Sasha Rush
MegaBlocks introduces block-sparse GPU kernels for MoE training, eliminating token dropping and optimizing for modern GPUs. Achieves up to 40% faster training than Tutel MoEs and 2.4x over Megatron-LM DNNs, enhancing efficiency on GPU architectures.
|
| |
|
|
| Generates hyper-realistic 3D assets that are viewable, renderable and editable from a single image. |
| |
|
|
| Pearl is a new open source RL library that allows you to mix and match components for policy learning, exploration, safety, and history summarization to create a unique RL agent. |
| |
|
|
| | | Want to promote your company, product, job, or event to 150,000+ AI researchers and engineers? You can reach out here. | |
|
|
|
|
