|
Hey,
Your daily briefing is ready. You can finally take a break from the AI firehose.
Our algos spent the night splitting signal from noise and pulled the top news, models, papers, and repos.
Here’s the must-read:
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer.
Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top Paper
|
|
|
|
Microsoft reveals predictable temporal patterns in Copilot usage by analyzing 37.5M Copilot conversation summaries
|
|
1,696 Likes
|
|
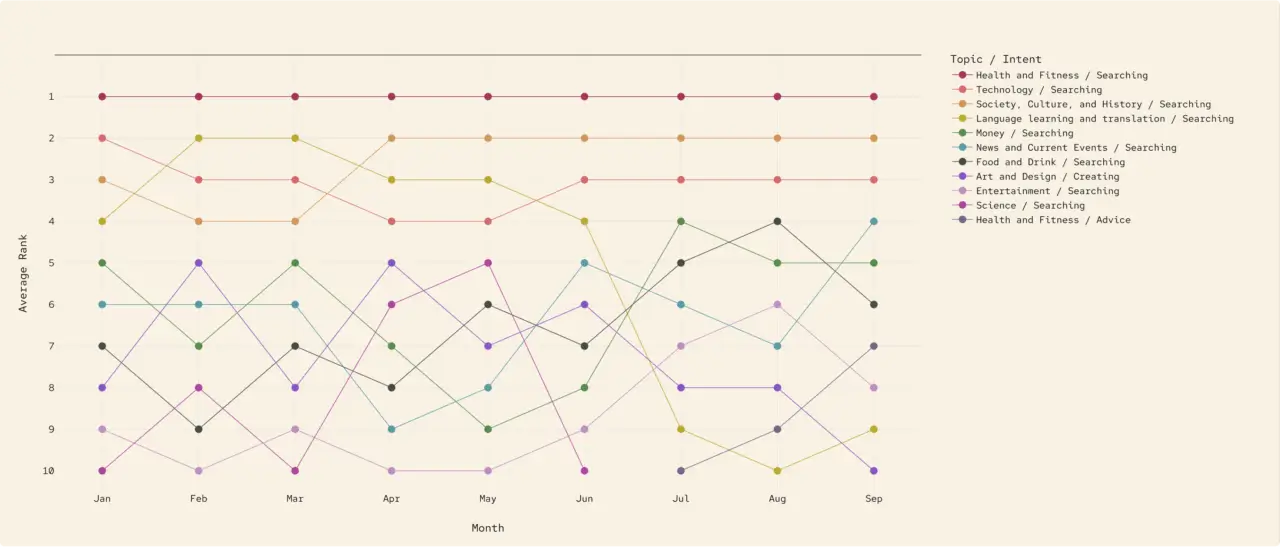
Microsoft AI wanted to understand how people actually use Copilot, so the team pulled summaries from 37.5 million conversations and searched for patterns in when different topics rise and fall.
The question was simple: does the clock shape what users ask? The answer turned out stronger than expected, with one pattern standing out across the entire dataset.
They found that time drives behavior more than any single feature. Health ranks highest on mobile across all hours and months. Programming climbs during weekdays while games take the weekend.
February builds toward a Valentine’s spike in relationship questions. Late-night hours tilt toward philosophy, while travel dominates daytime planning.
Key results
-
Health ranks first on mobile across the full nine-month window.
-
Programming rises Monday-Friday while games peak on weekends in August.
-
Relationship queries spike on February 14, with wellness rising earlier in the month.
-
Travel peaks during daytime; philosophy rises in early morning hours.
|
|
|
|
Your Multi-API Setup Is a Cost Center. Here’s the Low-Lift Fix.
|
|
Sponsored
|
|
You’ve got one API for transcription, another for speaker diarization, a third for redaction, and it still doesn’t cover topic detection. You’re not just managing product; you’re managing a spreadsheet of vendors, usage tiers, and integration breakpoints.
When budgets tighten, that pile of invoices gets real. And every hour lost to vendor-side debugging is another hour that doesn’t move your feature set forward.
AssemblyAI handles:
- Multilingual Speech-to-text across async and streaming
- Speaker detection, topic detection, and PII redaction in one stack
- Pay-as-you-go pricing: $0.15/hr, no lock-in, no “call for quote”
Your team stops wasting cycles on five brittle integrations and starts shipping, without explaining another cost overrun.
If you’re tired of guessing which service just 502’d your pipeline or which “accuracy” claim falls apart outside demo data, you can actually check the benchmarks for non-English audio, too.
You can get started in a few minutes, no multi-call onboarding required. Sign up and test it on your own stack.
|
|
|
|
partner with us
|
|
Top News
|
|
|
|
Cursor releases Debug Mode so agents debug using real runtime logs instead of static guesses
|
|
1,948 Likes
|
|
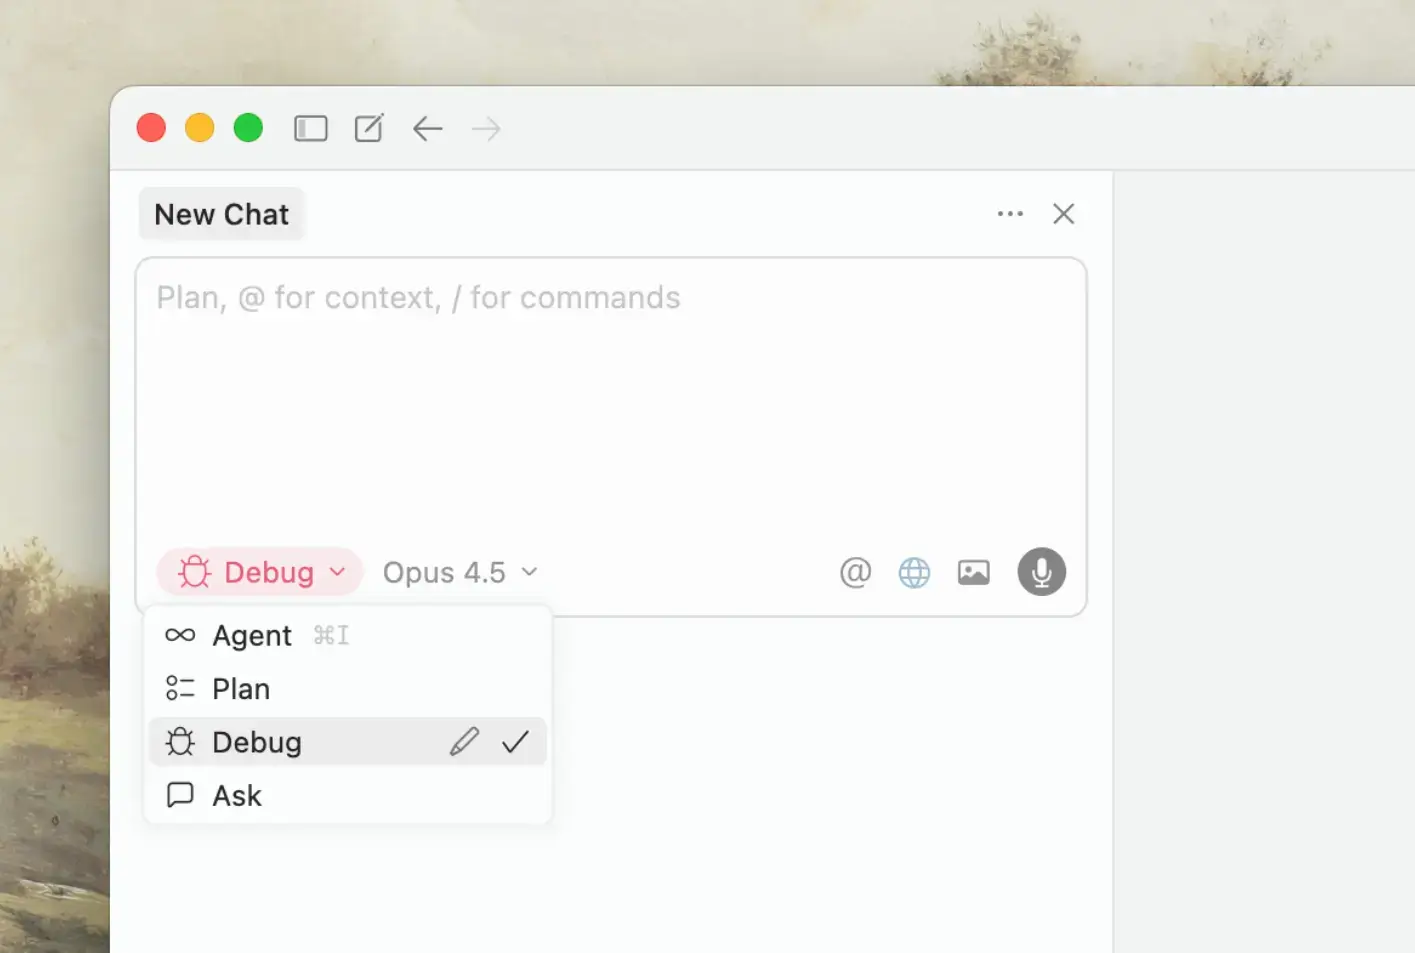
Cursor’s new Debug Mode starts with a simple setup: you describe a stubborn bug, the kind that eats weekends, and the agent reads your codebase with fresh eyes.
Static guesses rarely catch issues that only appear when the code actually runs. This insight pushes Cursor to flip the model: instead of guessing, it gathers real evidence from your runtime.
The breakthrough comes when Debug Mode instruments your code and asks you to reproduce the bug. It watches variable states, execution paths, and timing, then narrows the fault to a small, targeted fix instead of sprawling edits.
The impact is a debugging loop that works like a seasoned engineer sitting beside you, asking for one more run, checking logs, and adjusting the hypothesis until the root cause surfaces.
Key features and results:
-
Generates multiple hypotheses before proposing fixes for better fault isolation.
-
Injects temporary logs that capture real runtime data across execution paths.
-
Produces precise patches, often only two or three lines long.
-
Asks you to verify fixes to refine unclear or borderline outcomes.
|
|
|
|
Top News
|
|
|
|
Google debuts FACTS, a unified benchmark measuring factual recall, retrieval reasoning, grounding, and visual accuracy
|
|
1,358 Likes
|
|
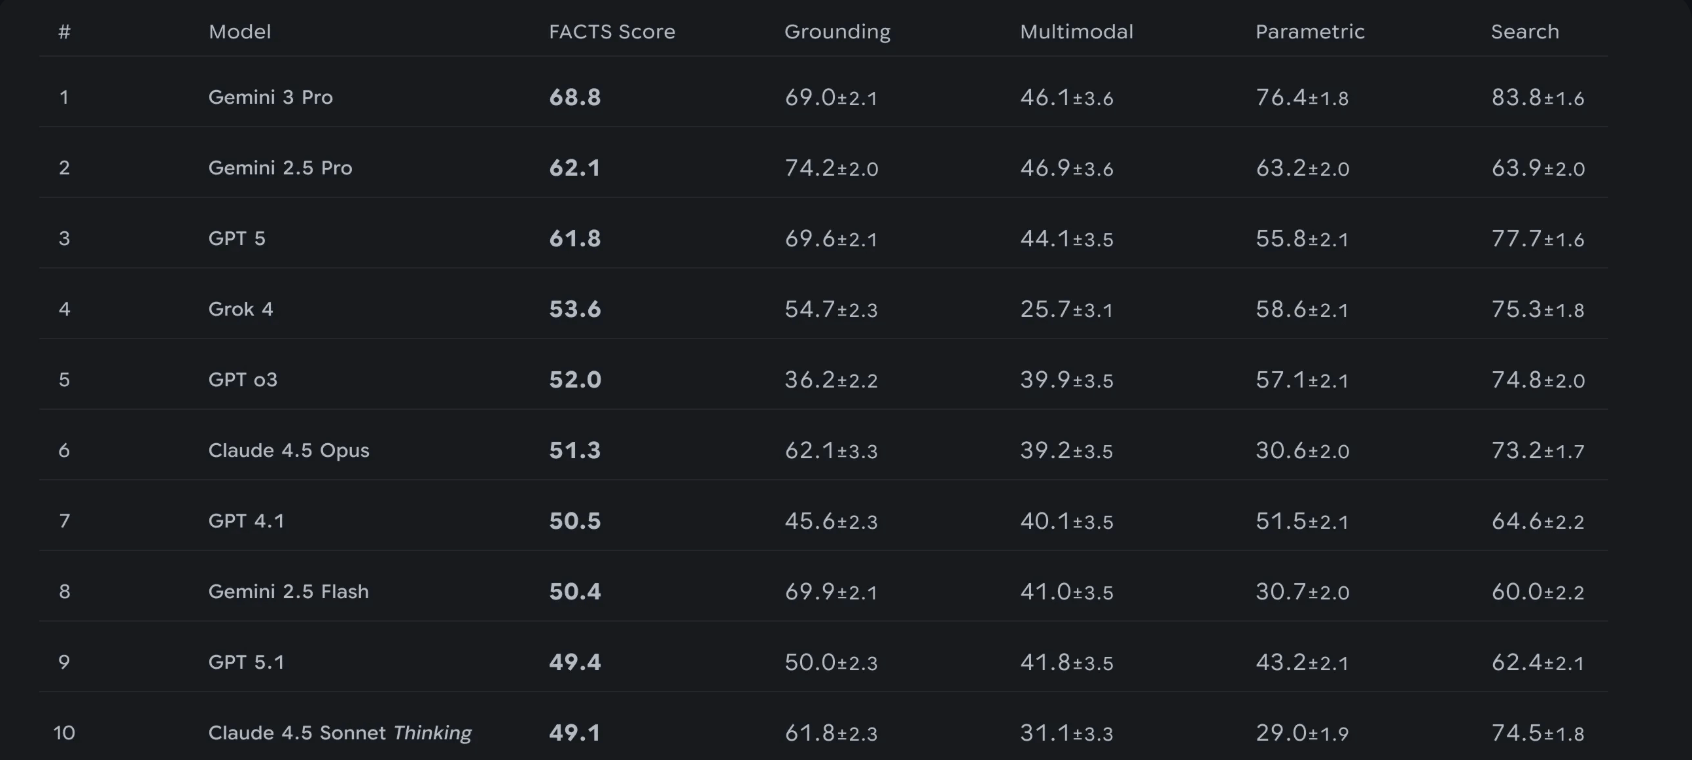
Google releases the FACTS Benchmark Suite to provide a structured way to measure factual accuracy across language models.
The industry keeps pushing LLMs into roles where accuracy matters, yet no single test has covered knowledge recall, web search, grounding, and image reasoning together. The standout moment arrives when Gemini 3 Pro posts a 68.8% overall score, the highest recorded so far.
The core challenge centers on identifying where models fail and why. FACTS addresses this by isolating four skill areas and evaluating them under controlled conditions.
The insight comes from merging parametric questions, standardized search, multimodal prompts, and context-based grounding. Together, they show where models fail and why.
The breakthrough is a consistent framework you can run locally using the 3,513 public examples.
Key features:
-
Tests internal knowledge through 1,052 trivia questions without external tools.
-
Evaluates multi-step reasoning under a unified search system.
-
Measures factual accuracy from image-based prompts across varied categories.
-
Checks consistency with provided text using an extended grounding protocol.
How to use it:
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
