The theme today is speed. Not hype, not benchmarks for their own sake. Actual latency being crushed across the stack: robots planning 19x faster, TTS at 110ms, KV cache shared across nodes.
We're watching inference go from "impressive demo" to "ships in production." Every layer of the AI stack is getting a performance pass right now, simultaneously.
And HeyGen's frame.md ties it together: agents don't just need to think faster, they need to produce faster.
|
|
Together with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top Paper
|
|
|
|
New robot planner runs 19x faster and cuts jerky movement by 38%
|
|
521 Likes
|
|
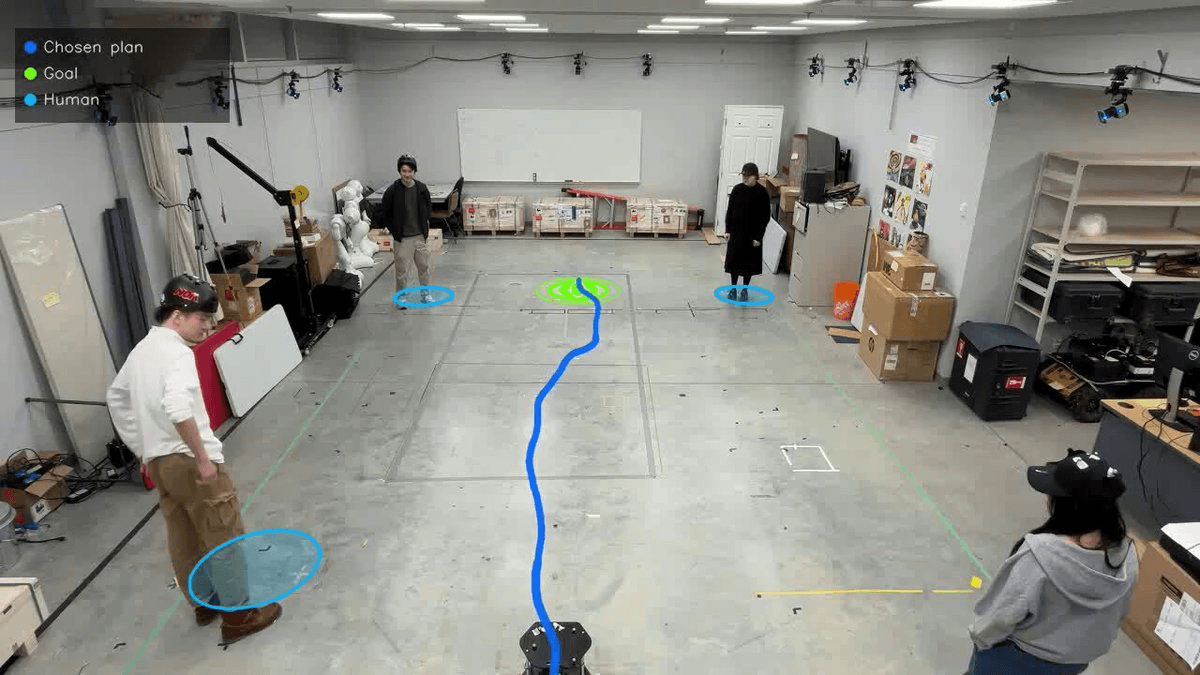
Robots that plan their own paths have a problem: they're slow and move like they've had too much coffee. Jerky, laggy, not great for real-world use. The usual approach uses diffusion models, which work like AI image generators but for robot paths. The catch? They need many calculation steps to produce one plan, making them too slow for a robot that needs to react right now. This paper swaps that out for a technique called IMLE, which learns to generate a good path in a single step instead of many. Think of it like skipping the rough drafts and going straight to the final answer. The results are pretty satisfying: - Planning speed jumped from 4.3 to 83 plans per second, a 19x speedup
- Smoother movement, 38% less jerkiness
- Runs in real time on both CPU and GPU
- Tested on a real mobile robot navigating around moving people
This opens up real-time robot navigation without needing expensive hardware. Code is available on GitHub.
|
|
|
|
Presented by Slack
|
|
30 Ways to Automate Work in Slack
|
|
Your team is spending time on work that shouldn't require human attention - status updates, approvals, follow-ups, and handoffs that repeat day after day.
Slack automation changes that. From auto-routing requests to triggering cross-tool workflows, this guide covers 30 practical ways teams are cutting manual work and reclaiming focus. Whether you're just getting started or looking to go deeper, you'll find real examples you can put into action today.
|
|
|
|
Top Model
|
|
|
|
Unsloth releases dynamic compression to run Gemma 4 12B more efficiently
|
|
509 Likes
|
|
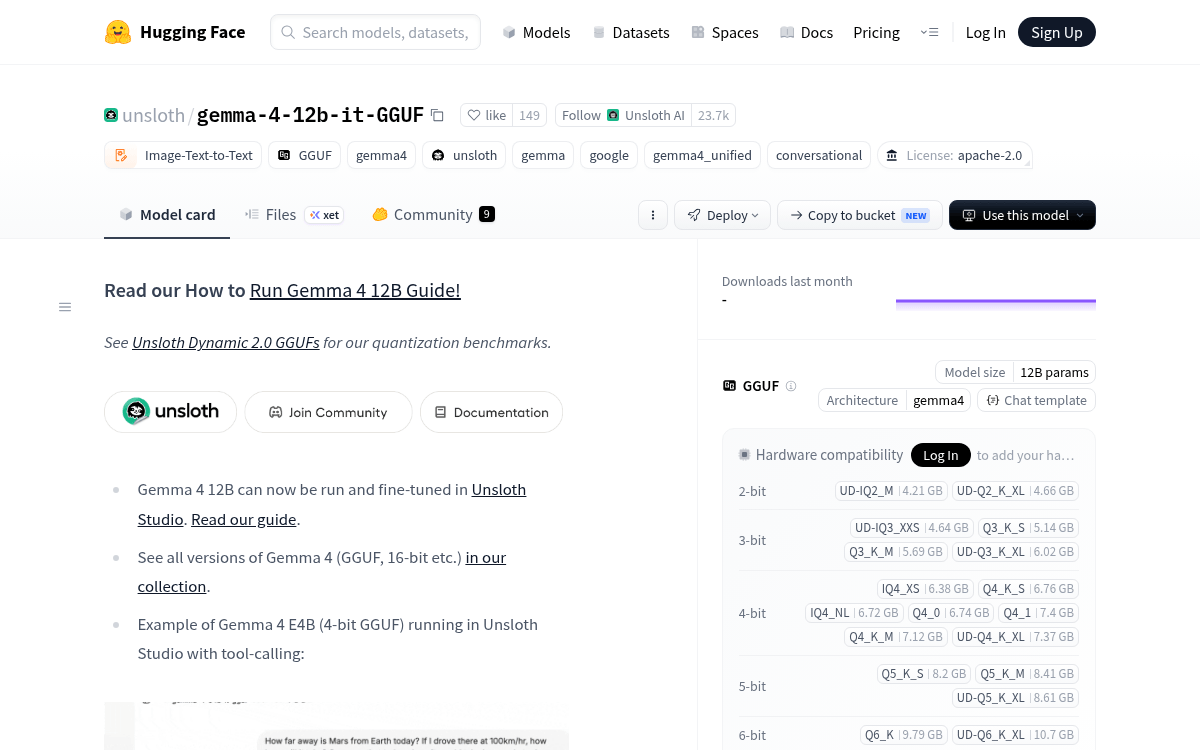
Google just dropped Gemma 4 12B, and Unsloth made it actually runnable on your laptop. Here's the deal. A 12-billion parameter AI model normally needs serious hardware. Unsloth's Dynamic GGUFs fix that by compressing the model smartly, squeezing it down so it fits in 8GB of RAM. Think of it like a zip file that barely loses quality. So what can you actually do with it? Quite a lot: - Chat with text, images, and audio in one model, no extra setup needed
- Feed it a 256K context window, roughly 200,000 words of input at once
- Build coding tools, agents that take actions, or multimodal apps
- Run and fine-tune it locally via Unsloth Studio
It's open source under Apache 2.0, so you can use it commercially. Grab the GGUF files on Hugging Face under unsloth/gemma-4-12b-it-GGUF and start running it today.
|
|
|
|
Presented by FriendliAI
|
|
The Fast, Reliable Inference Behind Your Agents
|
|
Slow inference stalls agents. Unreliable inference stops them. FriendliAI keeps yours fast and always on ⎯ 2–5× faster, 99.99% reliable, 50–90% lower cost. Powering inference for Claude Code, Cursor, Kilo, OpenCode, OpenClaw, and more.
|
|
|
|
Top Repo
|
|
|
|
HeyGen ships frame.md, a spec that teaches AI agents to make branded videos
|
|
384 Likes
|
|
Your design.md was great for keeping brand colors and fonts consistent across web pages and decks. But hand it to an AI agent and ask for a video? It spits out a webpage. That's the gap frame.md fixes. frame.md is a new spec built on top of design.md, but rewritten for the camera. It tells your AI agent how to think in scenes, motion, and timing instead of web layouts. The agent stops guessing and starts composing actual branded video. It plugs into HyperFrames, an open-source framework where you write plain HTML and render it as an MP4. No React, no proprietary timeline editor. Just HTML with timing attributes, animated with GSAP or CSS, then rendered via headless Chrome and FFmpeg. Here's what you can build with it: - Product launch and feature announcement videos
- Animated data charts and chart races
- Social clips with captions and overlays
- PDF or doc to video explainers
Get started: npx hyperframes init my-video, then npx hyperframes render. Works with Claude Code, Cursor, Gemini CLI, and Codex. Apache 2.0, no render fees.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
