| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 15 sec | 🎖️ Top News
📌 Ori
⚡️ Trending Signals
Tweet went viral showing Microsoft's new open source Phi 3.5 vision model's power at OCR/text extraction.
Cerebras launched fastest Llama3.1 inference API with Llama 3.1 8B at 1,700 tokens/sec.
Anthropic launches Artifacts on Mobile devices, both iOS and Android
NVIDIA releases NIM Agent Blueprints, to help every enterprises to jumpstart in deploying customized LLM solutions.
XAI updates Grok: Image prompts, model selection, prompt editing, text selection.
📌 Avail Corpus
📦 Top HF Models
Zamba2-1.2B: Efficient 1.2B LLM with SOTA performance, using hybrid SSM-attention architecture for on-device use.
Rene-v0.1-1.3b: Model with a hybrid Mamba-2 SSM backbone, and tailored to on-device inference.
AI21-Jamba-1.5-Large: Fast, multilingual models with 256K context for diverse AI applications.
🧠 Tutorial
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Language Model |
|
⇧ 3,966 Likes |
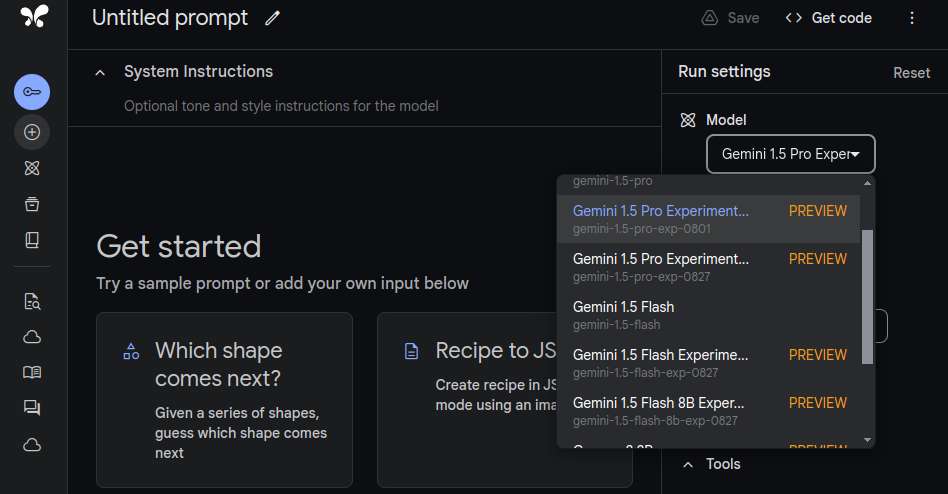 |
What's New | Google released three new models in a day.
An improved version of Gemini 1.5 Flash (Exp 0827) An even smaller version of Flash: Gemini 1.5 Flash 8B. An experimental version of Pro: Gemini 1.5 Pro (Exp 0827). Key Points
These models build on the Gemini 1.5 architecture, which uses a mixture-of-experts approach to balance performance and computational efficiency.
Flash-8B: 8 billion parameters, performance comparable to 70B models Pro (0827): Excels particularly in coding and complex prompt handling, serving as a drop-in replacement for its predecessor. Flash (0827): In the Chatbot Arena rankings, based on over 20,000 community votes, it jumped from 23rd to 6th place. All models: Available through Gemini API for developer integration Evaluation: Based on 20,000+ community votes in Chatbot Arena
Gemini 1.5 Flash-8B it outperforms Gemma-2-9b and matches LLaMA-3-70b in capabilities. This is a major improvements in its general capabilities and potential for real-world applications and broader deployment on resource-constrained devices.
Access
These experimental releases aim to gather developer feedback and inform future wider deployments. Developers can access the models through the Gemini API and provide insights via the Gemini API Developer Forum, contributing to an iterative refinement process based on real-world usage. | |
|
Read more
|
|
|
|
| Ori: $100 credit for AI workload acceleration. Flexible, scalable cloud infrastructure. |
Elevate your AI workloads with our scalable, efficient, and robust cloud infrastructure, powered by the cutting-edge NVIDIA H100 SXM. Enjoy on-demand access to virtual machines, reserve a dedicated instance, or request a bare metal cluster – the choice is yours.
High performance: Take advantage of the H100 SXM GPU to accelerate your AI model training and inference tasks. Flexible scalability: Effortlessly scale as your demands grow, with support for multi-GPU setups and high memory bandwidth.
Transparent costs: Enjoy personalized pricing and configurations tailored to your specific requirements. Sign up to Ori and claim $100 in free credit when you launch a H100 SXM.
|
|
Launch gpu instance
| partner with us |
|
|
|
TRENDING SIGNALS
| Vision Model |
|
⇧1,100Likes | |
LLM Inference |
|
⇧ 1,499 Likes | |
Anthropic |
| ⇧882 Likes |
| LLM |
|
⇧ 702 Likes | |
LLM |
| ⇧ 6000 Likes |
| |
|
|
|
|
|
AI developers use Avail's Corpus to source high quality training data
| Avail Corpus has aggregated >500K hours of HD video, >1M hours of studio quality audio, and billions of words. Corpus is partnered with leading model developers on everything from pre-training data needs to live data feeds for answer retrieval. They are SOC-II compliant, and backed by top VCs including General Catalyst and 776. |
Browse their Premium Database ↗️ |
|
|
|
|
TOP MODELS
| LLM | |
⇧66 Downloads |
Zamba2-mini was released yesterday, and helps you run a powerful 1.2B parameter LLM on-device with just 700MB of memory at 4-bit quantization. It outperforms 2-3B models in benchmarks while being 2x faster in time-to-first-token and 1.29x lower in generation latency compared to Phi3-3.8B. The hybrid SSM-attention architecture combines Mamba2 blocks with shared attention layers, achieving SOTA performance for its size. |
| Agents |
|
| ⇧ 113 Downloads |
Rene lets you run a 1.3B-parameter language model on your device. It uses state space models (SSMs) for efficiency, outperforming Apple's OpenELM and Google's Gemma-2B across benchmarks. It's open-source, supports 8-bit and 4-bit quantization without quality loss, and achieves state-of-the-art performance for models under 2B parameters. |
| Code Manager |
|
⇧ 478 Downloads |
Offer a 256K token context window, outperforming competitors on the RULER benchmark. Jamba 1.5 Large (94B active/398B total). The SSM-Transformer architecture provides up to 2.5x faster inference on long contexts. Scores 65.4, beating Llama 3.1 70B and 405B. They support 9 languages, structured JSON output, and function calling. |
| |
|
|
|
|
|
PYTHON TIP
| How to use Abstract Factory pattern in Python | The Abstract Factory pattern helps you create families of related objects without specifying their concrete classes.
Here's a simple example: |
from abc import ABC, abstractmethod

class AbstractFactory(ABC):
    @abstractmethod
    def create_product_a(self):
        pass

    @abstractmethod
    def create_product_b(self):
        pass

class ConcreteFactory1(AbstractFactory):
    def create_product_a(self):
        return ConcreteProductA1()

    def create_product_b(self):
        return ConcreteProductB1()

# Similar implementation for ConcreteFactory2
# and product classes
| |
The @abstractmethod decorator in Python marks a method as abstract, requiring any class that inherits from the abstract base class to implement that method. It ensures that concrete subclasses provide their own implementation of the decorated method, enforcing a consistent interface across all derived classes.
How the above implementation was helpful: It allows the creation of families of related objects (ProductA and ProductB) without specifying their concrete classes in the client code. Ensures that the products created by a factory are compatible with each other. It makes it easy to introduce new variants of products without breaking existing code. For example, adding a `ConcreteFactory2` that creates different product variants would not require changes to the client code that uses the abstract factory
This pattern is useful when your system must be independent of how its products are created. It promotes consistency within product families and makes adding new product families easier. |
|
|
|
Want to promote your company, product, service, or event to 190,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
