| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 3 min 24 sec | 🎖️ Top News
⚡️ Trending Signals
📌 Lambda
📄 Top Papers
rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking
Agent Laboratory: Using LLM Agents as Research Assistants
Don't Do RAG: When Cache-Augmented Generation is All You Need for Knowledge Tasks |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Open Source | UC Berkeley releases a $450 open-source reasoning model that matches o1 |
⇧ 1,498 Likes |
| What's New |
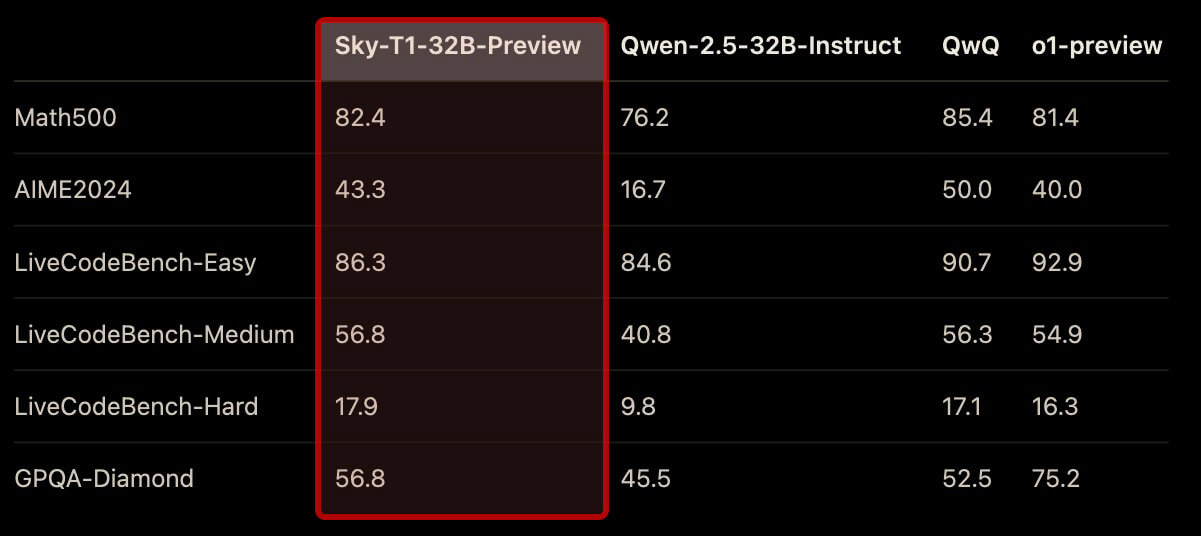
UC Berkeley’s NovaSky team releases Sky-T1-32B-Preview, an open-source reasoning model that matches OpenAI’s o1-preview on key benchmarks. The model offers advanced reasoning in math and coding, achieving high performance with a training cost below $450.
Open-Source Availability
NovaSky provides comprehensive resources for Sky-T1-32B-Preview, including: - Data: 17,000 training samples covering math, coding, science, and puzzles.
- Code: Scripts for data curation, training, and evaluation.
- Model Weights: The complete 32-billion-parameter model.
- Technical Report: Detailed methodology and WandB logs.
Data Curation Process
The team generates initial data using QwQ-32B-Preview and applies reject sampling to ensure quality. They curate a balanced dataset comprising: - 5,000 coding samples from APPs and TACO.
- 10,000 math samples from AIME, MATH, and NuminaMATH.
- 1,000 science and puzzle samples from STILL-2. Data reformatting improves parsing accuracy, boosting coding problem accuracy from ~25% to over 90%.
Training Methodology
NovaSky fine-tunes Qwen2.5-32B-Instruct with the curated dataset. The training parameters include: - Epochs: 3
- Learning Rate: 1e-5
- Batch Size: 96 Training completes in 19 hours on eight H100 GPUs using DeepSpeed Zero-3 offloading and Llama-Factory, keeping costs below $450.
Performance Metrics
Sky-T1-32B-Preview demonstrates strong performance across benchmarks: - Math500: 82.4%
- AIME2024: 43.3%
- LiveCodeBench-Easy: 86.3%
- LiveCodeBench-Medium: 56.8%
- LiveCodeBench-Hard: 17.9%
- GPQA-Diamond: 56.8%
Core Innovations
The model achieves competitive performance through a balanced data mixture that addresses the distinct reasoning needs of math and coding. Training a larger 32B model reduces repetitive content and enhances accuracy. The reject sampling and data reformatting processes ensure high-quality training inputs, enabling effective learning from diverse domains. | |
|
| Read more
|
|
|
|
TRENDING SIGNALS
| Coding Model |
|
⇧ 4325 Likes | |
AI Agent |
|
⇧ 3,635 Likes | |
XAI |
|
⇧ 6234 Likes | |
Open Source |
|
⇧ 2592 Likes | |
Research |
| ⇧ 2663 Likes |
| |
| |
|
|
Future-proof your workloads with NVIDIA GH200s on Lambda at just $1.49/GPU/hr
| NVIDIA Blackwell is almost here. To take full advantage of the new and powerful architecture, you need to start transitioning any existing or planned workflows that run on x86 processors to run on an ARM-based platform.
Testing on NVIDIA GH200 will get you ready for the latest generation. At just $1.49/hr on Lambda until the end of March, GH200s deliver 3x the performance of A100 at a similar price.
|
Get started today ↗️ |
|
|
|
TOP PAPERS
| Reasoning |
|
⇧ 4013 Likes | Problem:
Small language models (SLMs) cannot match larger models like OpenAI o1 in complex mathematical reasoning tasks.
Solution:
rStar-Math leverages Monte Carlo Tree Search (MCTS) with a policy SLM guided by a process reward model (PPM). It introduces:
- Code-augmented Chain-of-Thought data synthesis using extensive MCTS rollouts to create verified reasoning paths.
- A novel PPM training method that avoids naïve step-level annotations for better process evaluation.
- A self-evolution process that iteratively enhances both the policy SLM and PPM from scratch.
Results:
On the MATH benchmark, rStar-Math boosts Qwen2.5-Math-7B from 58.8% to 90.0% and Phi3-mini-3.8B from 41.4% to 86.4%, outperforming o1-preview by +4.5% and +0.9%. On the AIME, it solves 53.3% (8/15) of problems |
| Agents |
|
⇧ 3808 Likes | Problem:
Scientific discovery is slow and costly, requiring extensive time and resources from idea to results.
Solution:
Agent Laboratory, an autonomous LLM-based framework, automates the research process by handling literature review, experimentation, and report writing. It integrates specialized LLM-driven agents and allows human feedback at each stage, adapting to various computational resources from MacBooks to GPU clusters.
Results:
Agent Laboratory using o1-preview achieved the highest research outcomes and reduced research expenses by 84%. Its mle-solver secured four medals on MLE-bench, outperforming competitors. Generated ML code attained state-of-the-art performance. Human feedback improved paper quality from an average score of 3.8 to 4.38 out of 10. Additionally, gpt-4o completed workflows in 1165 seconds at $2.33, the most cost-effective model. |
| RAG |
|
⇧ 2480 Likes | |
Problem Retrieval-Augmented Generation (RAG) increases system latency by an average of 200ms per query and suffers a 15% error rate in document selection. Additionally, RAG's architecture complexity complicates maintenance and scalability for large-scale applications.
Solution We introduce Cache-Augmented Generation (CAG), which preloads all relevant documents into a long-context Large Language Model (LLM) and caches its key-value (KV) parameters. This approach eliminates real-time retrieval by enabling the LLM to generate responses directly from the preloaded context.
Results CAG reduces retrieval latency by 100%, cuts document selection errors by 10%, and achieves a 5% higher accuracy on the QA benchmark compared to RAG. Performance tests on three datasets showed a 20% improvement in response time and maintained context relevance with a 98% relevance score. No new model was presented. |
| |
| |
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 220,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
