Hey | Welcome back to AlphaSignal, where we bring you the latest developments in the world of AI.
In the past few days 1,500+ AI papers have been released, and among them, our model has picked the six.
Lets now dive straight into the papers!
Lior |
|
|
|
IN TODAY'S SUMMARY | Mobile ALOHA LLM Maybe LongLM LLaMA Pro Other notable papers
Reading time: 3 min 34 sec |
|
|
|
TOP PUBLICATION | Mobile ALOHA: Learning Bimanual Mobile Manipulation with Low-Cost Whole-Body Teleoperation | Zipeng Fu, Tony Z. Zhao, Chelsea Finn | | Project |  | What's New | Stanford researchers introduced Mobile-ALOHA, an open-source robot designed for bimanual tasks. Its new features include improved teleoperation for complex activities like cooking, enhanced mobility for faster movement, and stable handling of heavy objects.
Mobile ALOHA enhances bimanual mobile manipulation through low-cost, whole-body teleoperation, achieving up to 90% task success rates by integrating a mobile base and teleoperation with existing datasets. | Problem | Traditional robotic systems focus on static, table-top manipulation, lacking the mobility and adaptability for real-world, versatile tasks. This limits their practical applications in dynamic, everyday environments. | Solution | The solution involved developing Mobile ALOHA, incorporating AgileX Tracer AGV for mobility and stability. Teleoperation was enabled for simultaneous control of all robotic degrees of freedom. The team used imitation learning, co-training the robot with 20-50 demonstrations per task, combining new mobile data with static ALOHA datasets. | Results | Mobile ALOHA's approach led to a significant performance boost in complex tasks, such as cooking and storage, with success rates up to 90%. It's built cost-effectively, under $32k, including onboard power and compute, addressing both hardware and software challenges in robotics. | | Read the paper |
|
|
|
 | Get Rabbit’s First AI Device – R1 – Your Pocket Companion | Rabbit Inc. is set to unveil a game-changer in the AI world with its Rabbit R1 assistant at CES 2024 on January 9.
The OS, called rabbit OS, is capable of understanding complex user intentions, operating user interfaces, and performing actions on behalf of the user. Talk to r1 and r1 Will Do it for You: r1 understands your commands in natural language and executes them for you.
Streamlined Digital Life: rabbit’s AI-powered operating system mimics and learns the way you interact with apps and do it for you in the way you would.
Revolutionize Human-Machine Interaction with LAM: rabbit’s proprietary foundational model Large Action Model brings a new level of simplicity to your everyday life.
Sign up for the waitlist now for the January 9th launch. | | Join the waitlist |
|
|
|
TOP PUBLICATION | LLM Maybe LongLM: Self-Extend LLM Context Window Without Tuning | Hongye Jin, Xiaotian Han, Jingfeng Yang, Zhimeng Jiang, Zirui Liu, Chia-Yuan Chang, Huiyuan Chen, Xia Hu |  | What's New | With only four lines of code modification, the proposed method can effortlessly extend existing LLMs’ context window without any fine-tuning. | Problem | Traditional LLMs struggle with processing long input sequences due to limited training sequence length. This restriction hampers their application in tasks requiring long-context comprehension. | Solution | Self-Extend employs a dual attention approach: grouped attention for distant tokens and normal attention for close ones. It applies a floor operation to token positions, merging these attentions before the softmax step. This method requires minimal code changes and no additional training. | Results | Self-Extend successfully extended LLMs' context window beyond their pretraining limits, maintaining low perplexity (PPL) over extended contexts. For example, it expanded Llama-2's context from 4k to over 16k tokens. It achieved 100% accuracy in passkey retrieval tasks, outperforming models with sliding window attention (SWA) in handling long contexts. | | Read the paper |
|
|
|
TOP PUBLICATION | LLaMA Pro: Progressive LLaMA with Block Expansion | Chengyue Wu, Yukang Gan, Yixiao Ge, Zeyu Lu, Jiahao Wang, Ye Feng, Ping Luo, Ying Shan | 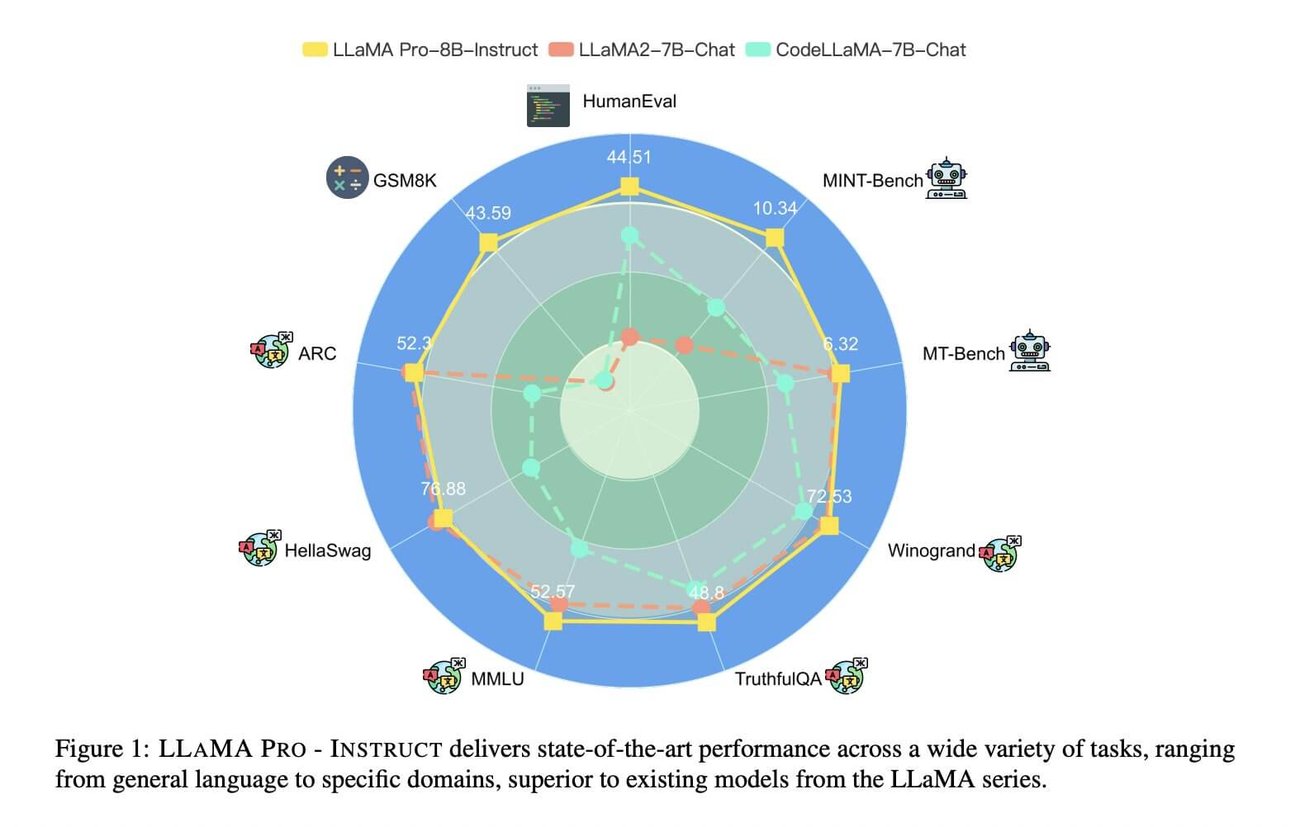 | What’s New | LLaMA Pro enhances LLMs with block expansion, adding eight Transformer blocks to LLaMA2-7B for specialized domain performance while retaining general language proficiency. | Problem | Traditional LLMs, when fine-tuned for domain-specific tasks like coding or mathematics, experience catastrophic forgetting, losing their broad language proficiency. This limits their application in specialized fields while maintaining general language effectiveness. | Solution | The approach involves expanding LLaMA2-7B from 32 to 40 Transformer blocks. LLaMA Pro fine-tunes only the added blocks with domain-specific data, leaving the original blocks intact. This method preserves the model's general linguistic ability while embedding new, specialized knowledge. | Results | With 8.3 billion parameters, LLaMA Pro outperforms other LLaMA models in general and domain-specific tasks, showing marked improvements in benchmarks over models like CodeLLaMA-7B, demonstrating effective balance between general language processing and specialized domain knowledge. | | Read the paper |
|
|
|
| Google announced Instruct-Imagen, a multi-modal instruction-based image generation model which enables varied visual tasks and zero-shot generation on new, complex instructions. It marks an initial but significant leap forward general-purpose visual generative model. |
| |
|
|
| CALM introduces a method for augmenting large language models (LLMs) by composing them with specialized models, preserving original capabilities while enabling new tasks. It employs cross-attention for efficient integration, showing up to 13% improvement in low-resource language tasks and 40% in code generation. This approach offers a scalable, modular solution for enhancing LLMs without retraining. |
| |
|
|
| DiffusionLight is a new technique to estimate lighting from any in-the-wild input image by inpainting a chrome ball into the image with diffusion models. |
| |
|
|
| | | Want to promote your company, product, job, or event to 150,000+ AI researchers and engineers? You can reach out here. | |
|
|
|
|
