OpenAI shipped a custom chip and a model update on the same day. That's not a coincidence.
The pattern is clear: the real AI moat is no longer the model, it's the full stack. Jalapeño is OpenAI's bet that owning inference silicon is the only way to make the unit economics work. $20.9B operating loss has a way of focusing the mind.
Every layer is getting vertically integrated, fast.
|
|
In Partnership with
|
·
|
|
|
|
|
|
Announcement: AlphaSignal Event
|
|
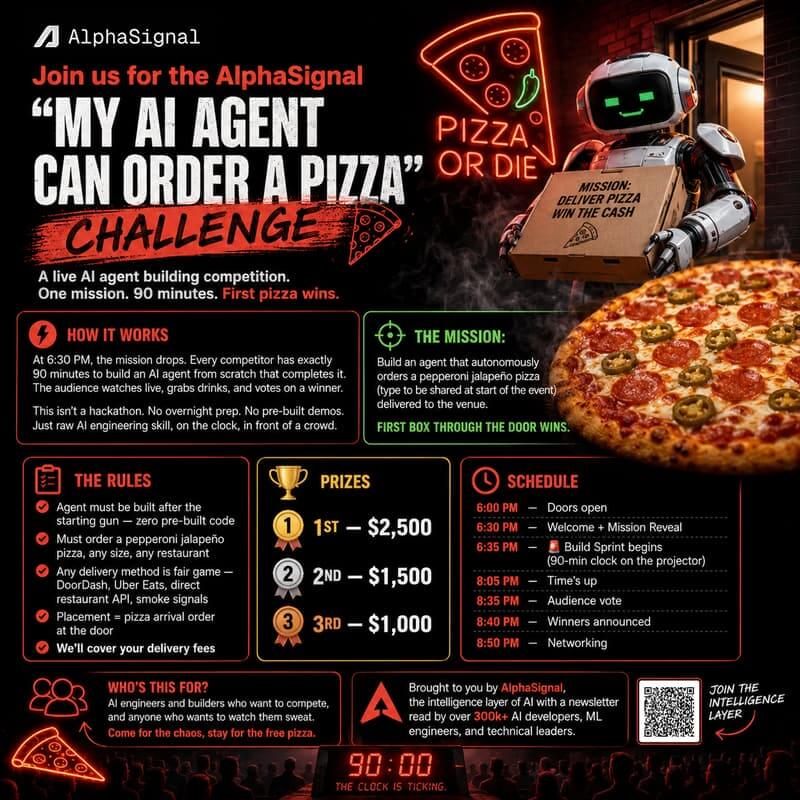
We're hosting a live AI agent battle on August 6 in San Francisco! 90 minutes countdown with one mission: build an agent from scratch that orders a pepperoni jalapeño pizza delivered to the venue. First box through the door wins. No pre-built code, no overnight prep, just raw AI engineering on the clock in front of a live crowd. Prizes: $2,500 / $1,500 / $1,000 Join us for a night of live coding, free pizza, and networking with SF's best AI builders. It's free to attend - reserve your spot today.
|
|
|
|
Top News
|
|
|
|
OpenAI reveals its first custom AI chip built with Broadcom
|
|
19,258 Likes
|
|
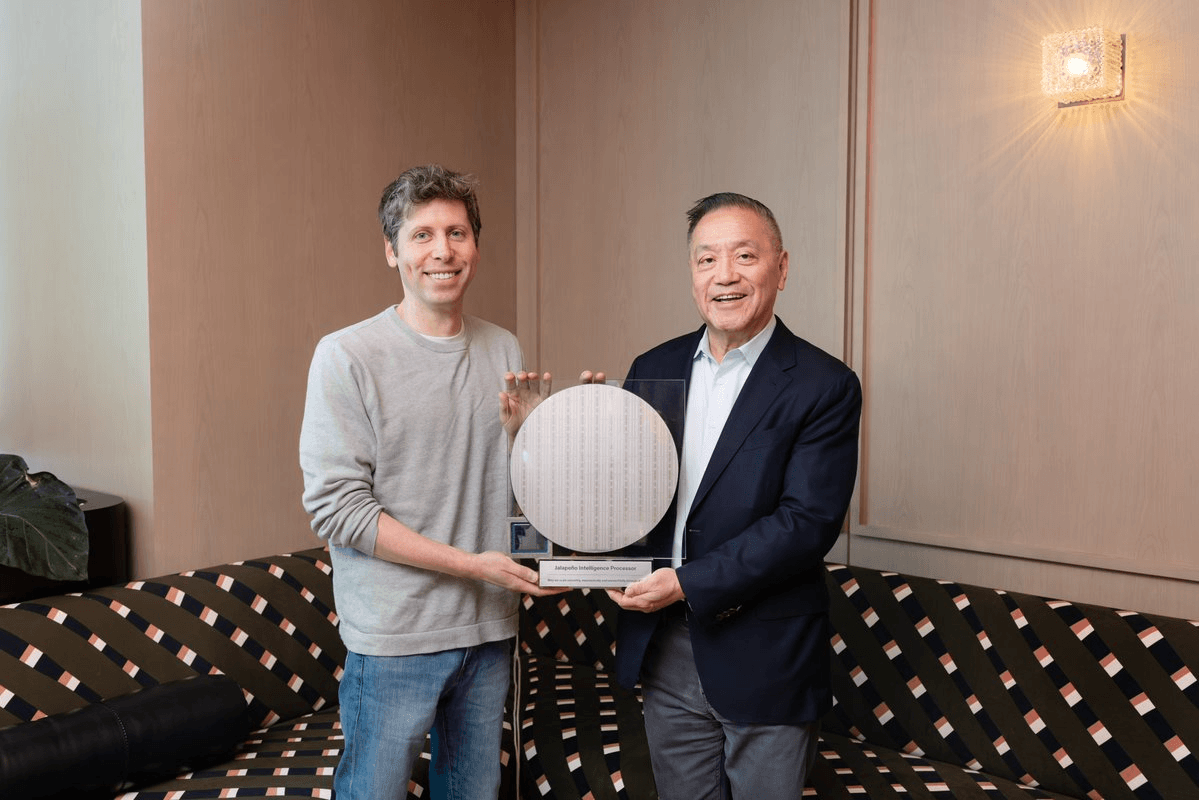
OpenAI just built its own chip. Meet Jalapeño, a custom processor built with Broadcom, designed from scratch specifically to run AI models faster and cheaper. Here's the key thing to understand: this chip handles inference, meaning the part where a model actually answers your question. Not training. Just serving responses to users at massive scale. Why does this matter? OpenAI was burning through Nvidia GPUs to power ChatGPT and Codex. Those are expensive and in short supply. A purpose-built chip means lower costs, faster responses, and more capacity. - Built in just 9 months, which is reportedly the fastest ever for a chip this complex
- Early tests show better performance-per-watt than current top chips
- Already running GPT-5.3-Codex-Spark in the lab
- Designed to support any LLM, not just OpenAI's own models
OpenAI even used its own AI models to help design the chip. The takeaway: cheaper inference means cheaper API calls, faster Codex responses, and more reliable access when demand spikes.
|
|
|
|
Presented by ASUS
|
|
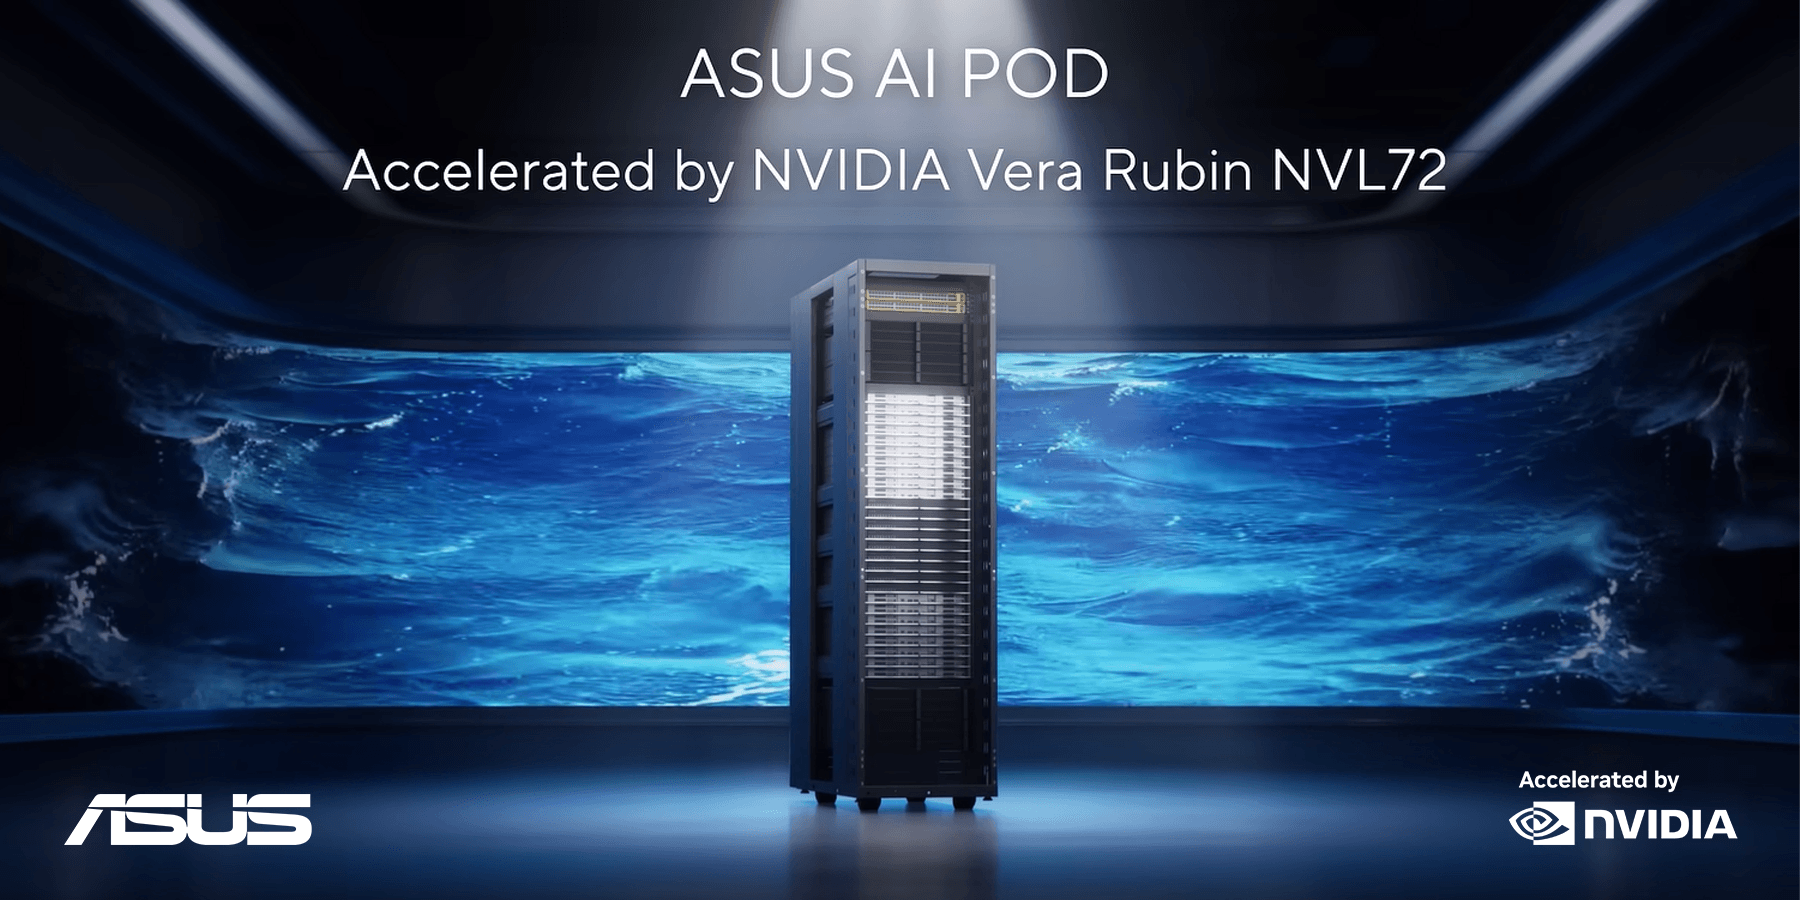
ASUS AI POD: Built for Trillion-Parameter AI
|
|
The ASUS AI POD with NVIDIA Vera Rubin NVL72 is a rack-scale AI system engineered for the next generation of AI reasoning. The NVIDIA Vera Rubin Superchip delivers 10X NVFP4 inference performance per megawatt, 10X lower inference token cost, and 2.8X HBM4 memory bandwidth versus previous generations. ASUS AIDC automates software cluster setup, enabling modern AI factories to be online within 30 minutes. Trusted AI. Total Flexibility: ASUS AI POD with NVIDIA Vera Rubin NVL72
|
|
|
|
Top News
|
|
|
|
OpenAI upgrades GPT-5.5 Instant with smarter intent and better recommendations
|
|
7,604 Likes
|
|
OpenAI just pushed an update to GPT-5.5 Instant, the model that powers most ChatGPT conversations. This is not a new model, it is a tune-up to the one already running by default. So what actually changed? The model is now better at figuring out what you actually want, not just what you literally typed. It identifies the underlying goal behind a question, carries context across multiple turns, and follows complex instructions more reliably when a request includes several constraints. The other big fix: it stops being stubborn. When you add constraints, clarify what you mean, or push back on an answer, the model adapts instead of just repeating its original response. Here is what improved: - Intent understanding: reads the goal, not just the words
- Multi-constraint handling: addresses all requirements in one shot
- Shopping and local queries: better use of location context, combining product info, business details, and images more coherently
In the API, access it as "chat-latest". Paid users get it now, free users tomorrow.
|
|
|
|
Presented by Checksum
|
|
More PRs, same test suite. That's the bottleneck.
|
|
Your AI coding agent ships PRs fast but your test suite is the bottleneck. Checksum fixes it: continuous, self-healing E2E Playwright tests inside your CI/CD that you own. Catch bugs before they merge. No flaky suites to babysit.
|
|
|
|
Top News
|
|
|
|
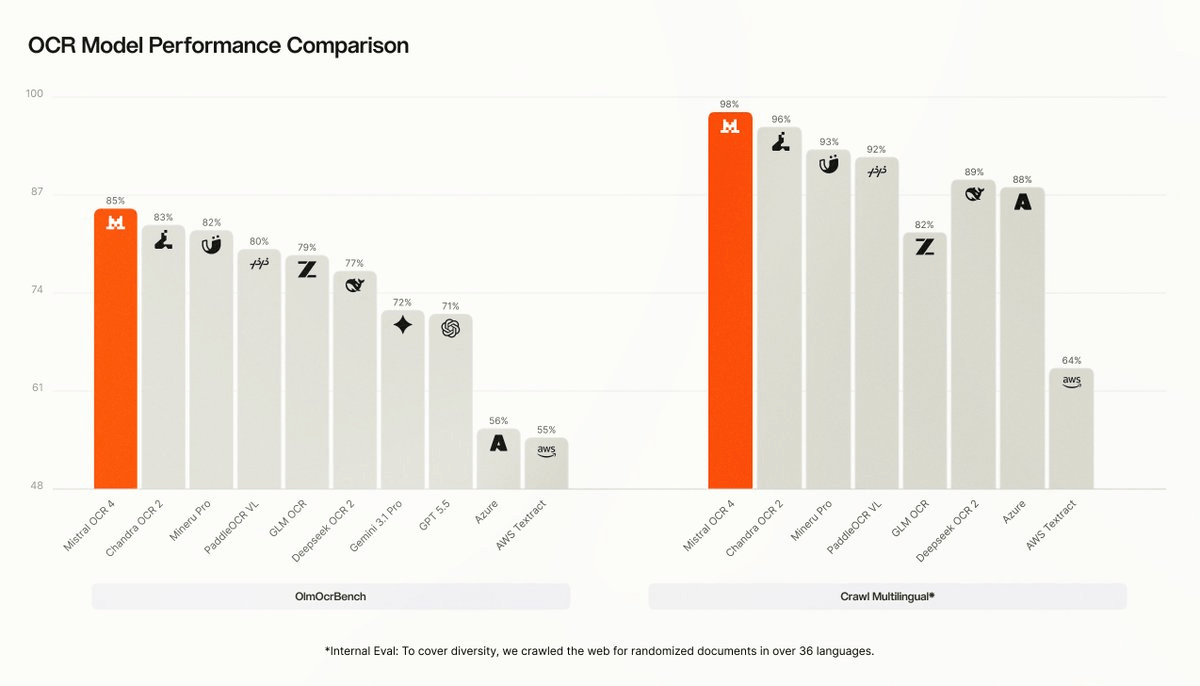
Mistral releases OCR 4 with 72% win rate across 600+ real-world documents
|
|
6,187 Likes
|
|
Most OCR tools just dump raw text at you. Mistral OCR 4 does something smarter: it returns a full map of your document. Every block of content gets a bounding box (its exact position on the page), a type label like title, table, equation, or signature, plus a confidence score so you know how sure the model is. That means you stop guessing where things are and start acting on them. What does this unlock for you? - Cleaner RAG pipelines: classified blocks become better retrieval chunks, not messy text walls
- Smarter agents: flag low-confidence regions for human review automatically
- Compliance-safe: self-host the whole thing in a single container, documents never leave your environment
- Broad language support: 170 languages, with real gains on rare ones where other tools fall apart
Pricing is $4 per 1,000 pages via API, or $2 with batch. Available now on Mistral Studio, Amazon SageMaker, and Microsoft Foundry.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
