| Hey | Welcome to AlphaSignal, the most read source of news by AI engineers and researchers. Every day, we identity and summarize the top 1% of news, papers, models, and repos, so you’re always up to date.
Here’s today’s roundup: |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP_NEWS
| | Google's Gemini 2.5 Flash Image ranks #1 on LM Arena for image editing, beating OpenAI and Flux
| 60,386 Likes |
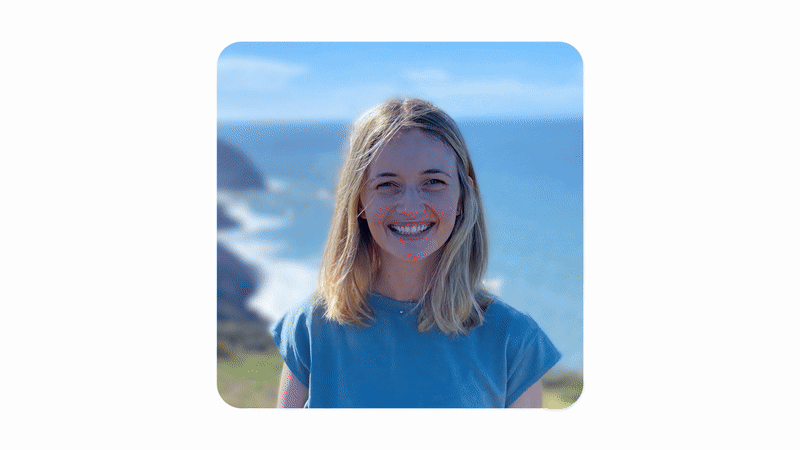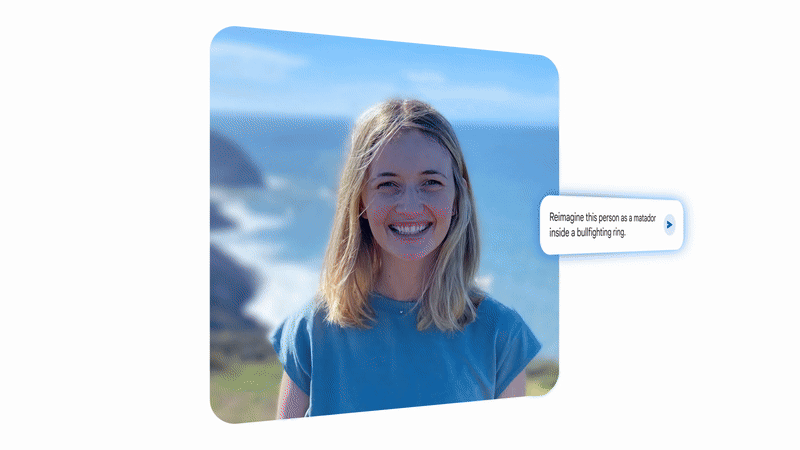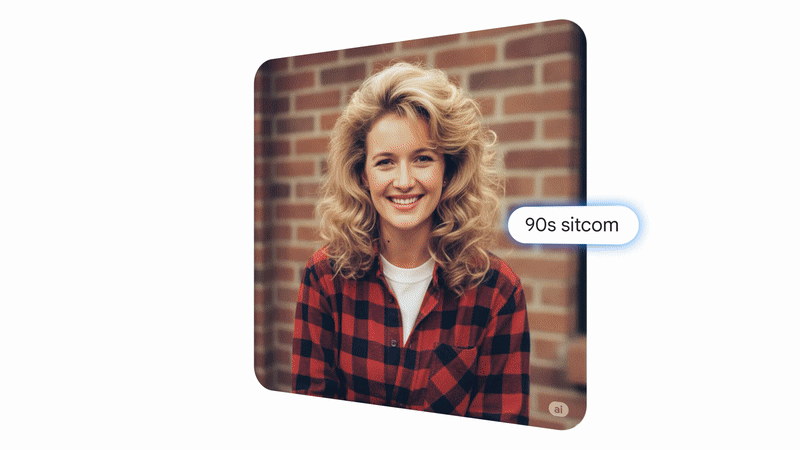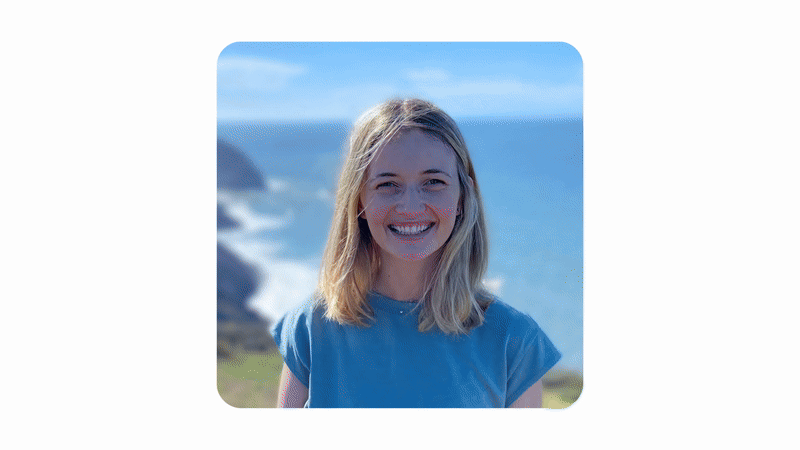
| Google released Gemini 2.5 Flash Image (internally known as nano-banana), its new SOTA image generation and editing model. It supports multi-step image editing, character consistency, and world-knowledge-based transformations, all controlled through natural language prompts.
This means a single model can now handle complex editing workflows, from template-driven automation to character-consistent storytelling and product design.
Key Features
Supports multi-turn edits while keeping results consistent. Maintains character likeness across scenes and edits. Enables precise local edits with natural language like, blur, remove, recolor. Performs multi-image fusion for blending objects or scenes. Uses Gemini’s world knowledge to make contextually accurate edits like adding correct plants to a scene. Adds SynthID watermarking to all generated or edited images. Performance
Ranked #1 on LM Arena’s Image Edit leaderboard, surpassing Flux-Kontext (No. 2) by a wide margin. Outperformed competing models such as OpenAI’s gpt-image and BFL’s Flux-Kontext on cost-to-performance ratio. Pricing and Cost Controls
Priced at $30 per 1M output tokens. Each image equals 1,290 output tokens (~$0.039 per image). Slightly cheaper than comparable models like OpenAI’s gpt-image and BFL’s Flux-Kontext. Input/output for text still follows Gemini 2.5 Flash pricing. Availability
Available now via the Gemini API and Google AI Studio (preview). Enterprise access through Vertex AI. Integrated into Google AI Studio’s Build Mode for prototyping and remixing apps with minimal code. Also available through OpenRouter.ai and fal.ai developer platform. | |
| Try now
|
|
|
|
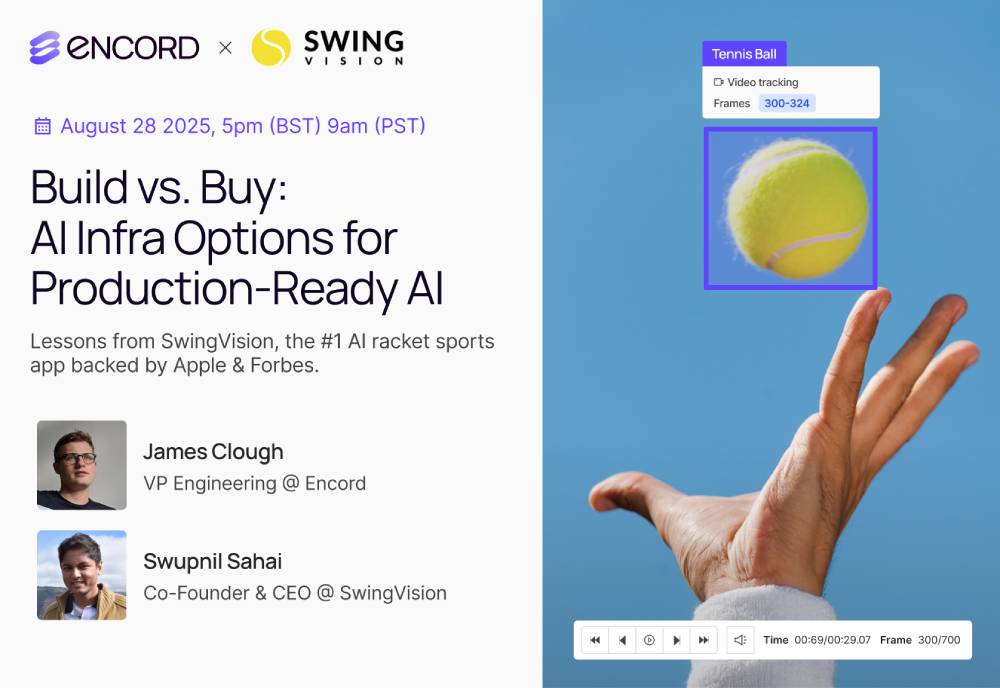
| Happening Tomorrow: Boost Production AI Iteration by 30% & Cut Infra Debt |
Join Encord’s upcoming webinar and get a comprehensive framework for how SwingVision scaled real-time computer vision with minimal overhead. Walk away with actionable ways to slash technical debt and raise model velocity, without overbuilding.
See how you can: Architect a stack that enables faster iteration cycles
Identify edge cases early and maintain model accuracy
Optimize engineering effort to focus on high-impact features
Reduce time-to-market by choosing where to build vs. integrate
Join to see how top teams avoid common traps and move faster. |
| Save your spot
| partner with us |
|
|
|
TOP_SIGNALS
| |
|
6,826 Likes | |
|
1,583 Likes | |
|
2,258 Likes | |
|
| 664 Likes |
|
|
1,943 Likes | | |
|
|
|
|
TOP_PAPERS
| |
| 1,358 Likes |
Using payroll records through July 2025, the report shows early‑career workers in AI‑vulnerable roles face a 13% employment decline. The decline arises from job reductions, not wage cuts, while older and less‑exposed workers hold steady or grow. |
|
|
| 1,148 Likes |
This paper proposes a memory-based framework that continuously trains LLM agents without updating model weights. It skips gradient updates, instead learning policies through episodic memory and case reuse. |
|
|
| 538 Likes |
Google proposes a text-based regression method where LLMs predict compute efficiency from raw system logs. The model avoids feature engineering, generalizes to unseen clusters, and enables fast, uncertainty-aware simulation for industrial-scale optimization. |
| |
| |
|
|
PRODUCT_DEEP_DIVE
| |
How Google Built Nano-Banana: Smart, Multistep Image Generation |
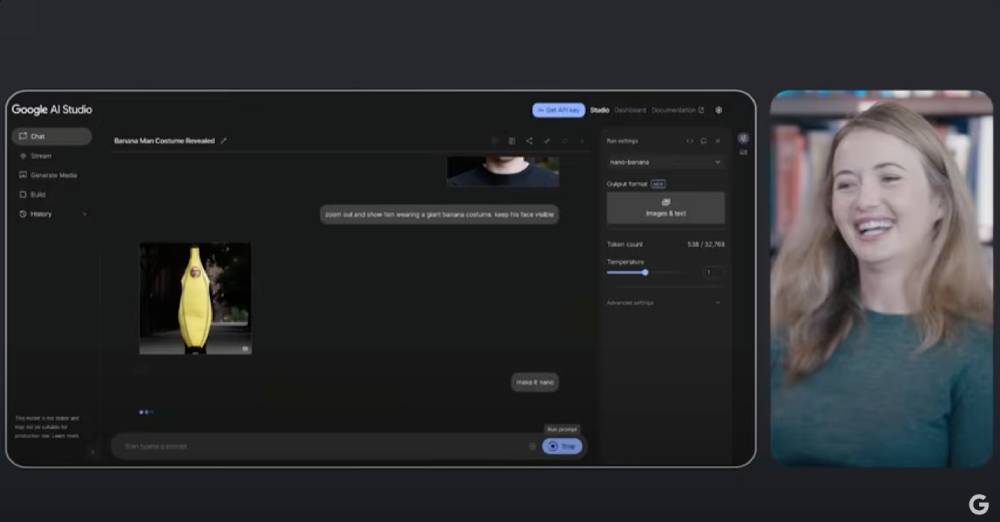
| Google shared a behind-the-scenes look at Gemini Flash 2.5 ("nano-banana"), its new image model. The team explains how it handles complex edits over multiple turns, keeps characters consistent, and follows vague prompts more intelligently.
They also share how feedback from users helped improve the model since version 2.0.
Key Takeaways Understand how the model supports multi-turn image editing
See how it interprets vague prompts using world knowledge
Learn why text rendering acts as a proxy for image quality
Explore how image understanding and generation transfer capabilities
Know when to use Gemini vs. Imagine for different tasks
Build iterative visual workflows using natural language prompts Watch to understand how interleaved generation enables smarter, more controllable image editing pipelines. |
| Watch now
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
