|
Hey,
Your daily briefing is ready. You can finally take a break from the AI firehose.
Our algos spent the night splitting signal from noise and pulled the top news, models, papers, and repos.
Here’s the must-read:
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer.
Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
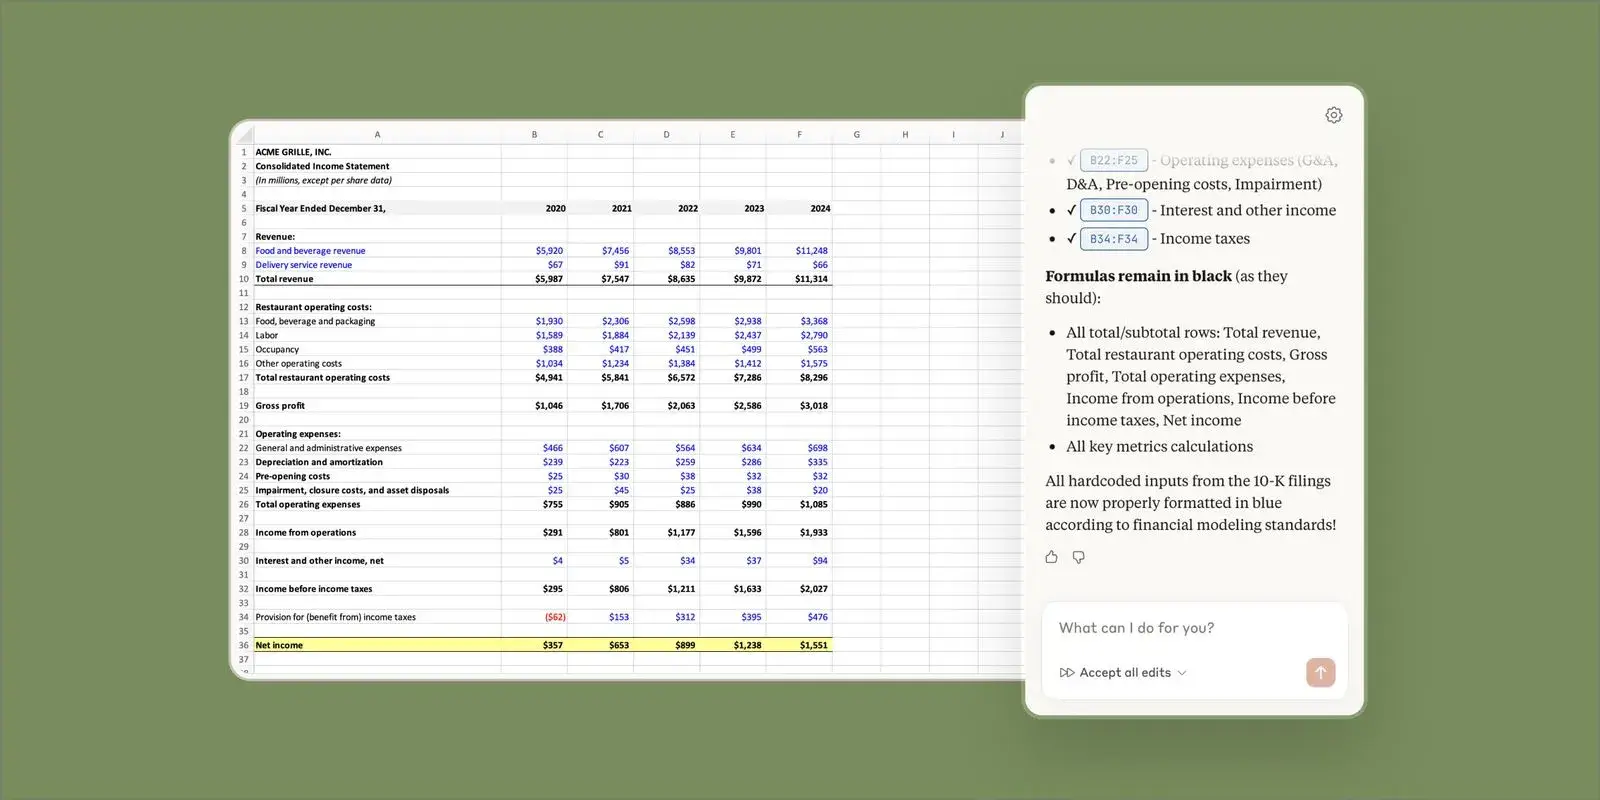
Anthropic integrates Claude into Excel to deliver full-workbook reasoning with precise cell-level tracing
|
|
44,653 Likes
|
|
The idea is simple: move Claude from chat windows into the place where analysts and engineers already spend hours, large, fragile spreadsheets.
The hard part is context. Excel models hide logic across tabs, nested formulas, and long dependency chains. Claude’s key advance is that it reads the entire workbook and explains it with precise cell references.
You can open Claude inside Excel with Control+Option+C on macOS or Control+Alt+C on Windows. From there, you ask questions in plain language. Claude answers with citations that point to exact cells, so you can verify every step.
For longer workflows, Claude compresses earlier context automatically so sessions do not break mid-analysis.
Core capabilities
-
Reads full workbooks, including nested formulas and cross-sheet dependencies
-
Explains calculations with exact cell-level citations
-
Supports multi-file drag-and-drop in a single session
-
Updates assumptions without overwriting existing cells or formulas
|
|
|
|
Presented by Fiddler
|
|
Live Webinar: Prevent AI Agents from Going Rogue
|
|
AI agents are reshaping how enterprises operate. Join Fiddler AI and David Kenny, Executive Chairman at Nielsen, for a candid conversation on what it means for the enterprise when agents take over decision-making, and what it takes to maintain control.
What you’ll learn:
-
How agents reshape operations, workforce, and enterprise decision-making
-
What new risks emerge when humans delegate authority
-
Why a control plane is essential to operationalizing and scaling agents safely across the organization
|
|
|
|
partner with us
|
|
Top Repo
|
|
|
|
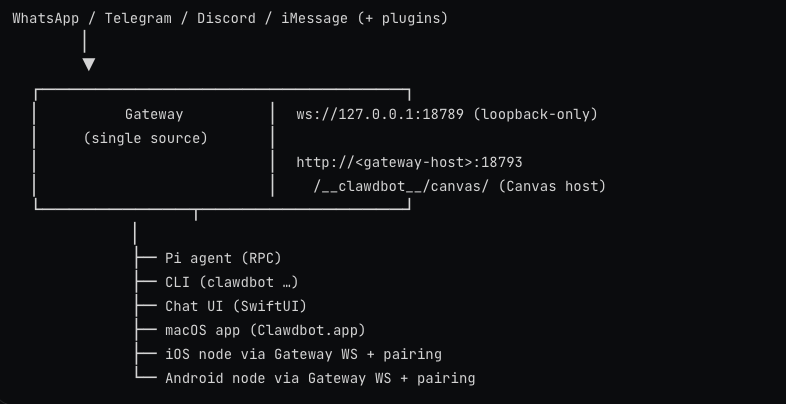
Clawdbot delivers an open-source local assistant that performs file, browser, and shell actions anywhere
|
|
49,284 Likes
|
|
Clawdbot starts with a simple idea: put an AI assistant fully on your own machine, then let it act.
Instead of a hosted chatbot, you run a local Gateway that connects models, tools, and messaging apps into one always-on system. The assistant does real work on your computer, not just text replies.
The Gateway acts as the control plane. It routes messages, stores memory, and triggers tools. Models such as Claude or GPT handle reasoning through your own subscriptions.
It is Local-first, which means files, shells, browsers, and schedules live on your device, not a remote server.
You install Clawdbot through a global CLI and an onboarding wizard. The wizard sets up channels, agents, and a background daemon. After that, you talk to it from chat apps or the CLI.
Core features
-
Single local Gateway that manages agents, memory, tools, and sessions
-
Multi-channel inbox across WhatsApp, Slack, Discord, Signal, Teams, and others
-
Local tools for files, shell commands, browser control, cron jobs
-
Model swapping through config files with no code changes
Usage and scope
-
Run on macOS, Linux, or Windows via WSL2 with Node.js 22+
-
Support Anthropic and OpenAI models with OAuth or API keys
-
Keep agents alive across sessions with persistent on-disk memory
|
|
|
|
Top Paper
|
|
|
|
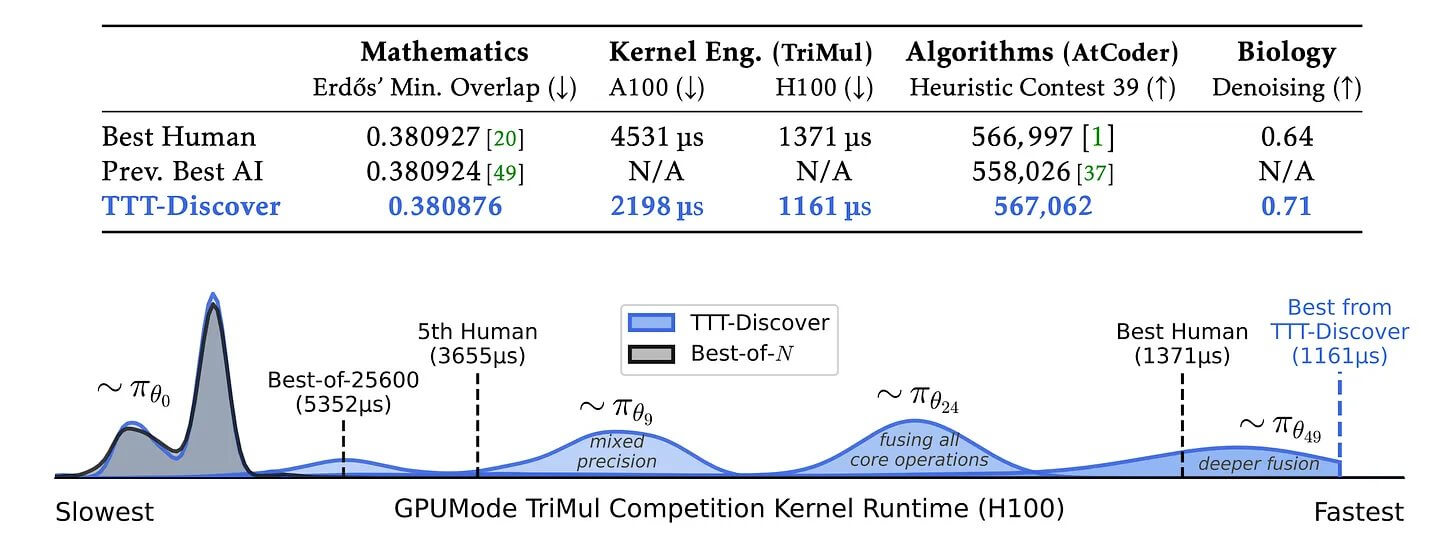
NVIDIA and Stanford show models gain accuracy by treating each test problem as a learning environment
|
|
2,538 Likes
|
|
TTT-Discover starts with a simple question: why does AI stop learning right when the real problem begins?
Researchers from NVIDIA and Stanford University answer it by letting a model keep training while it solves one hard task. The breakthrough is that test time becomes learning time, not just repeated prompting. That shift produces state-of-the-art results using an open model.
The problem is that prior test-time scaling methods search harder but never improve the model itself. TTT-Discover changes this by applying reinforcement learning at test time. Reinforcement learning means the model tries solutions, receives numeric feedback, and updates its weights toward higher scores.
How it works
-
Treats one test problem as a reinforcement learning environment with a continuous reward
-
Updates model weights during evaluation while keeping the base model unchanged
-
Optimizes for the single best solution, not average output quality
Results
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
