| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 4 min 42 sec | 🎖️ Top News
⚡️ Trending Signals
📌 AssemblyAI
📝 Top Papers
Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions.
Adding Error Bars to Evals: A Statistical Approach to Language Model Evaluations.
SAMURAI: Adapting Segment Anything Model for Zero-Shot Visual Tracking with Motion-Aware Memory.
🧠 Python Tip |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Multi-modal Model | Google reclaims LLM top spot from OpenAI; Gemini-exp-1121 available on Google AI Studio |
⇧ 2,389 Likes |
 |
What's New |
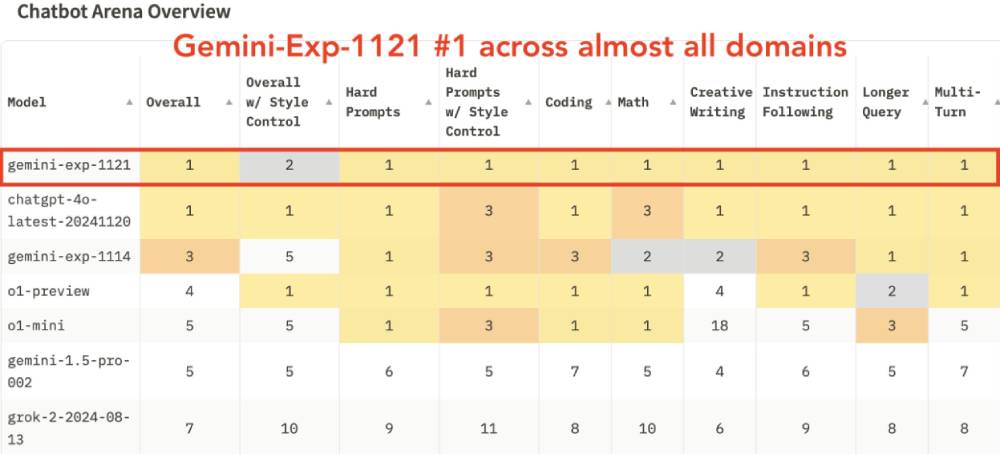
Google DeepMind releases the Gemini-Exp-1121 model, offering enhanced performance in coding, reasoning, and vision tasks.
This version ranks #1 overall in the AI Arena, tied with GPT-4o-1120, and excels in specific tasks like coding and vision.
Key Performance Metrics Gemini-Exp-1121’s ranking improvements are substantial:
- Overall ranking moved from #3 to #1 in the Arena.
- In the StyleCtrl category, it moved from #5 to #2.
- In Hard Prompts (StyleCtrl), it achieved #1, up from #3.
- It leads in coding (#1), math (#1), and vision (#1).
- In creative writing, it climbed from #2 to #1.
Benchmarking
On the AI Arena platform, Gemini-Exp-1121 leads overall rankings. However, you should be aware that it performs differently on other platforms like Livebench, where it lags behind models such as GPT-4o and Claude.
How to Access it? - Access Gemini-Exp-1121 via Google AI Studio or the Gemini API.
|
|
| Try now
|
|
|
|
TRENDING SIGNALS
| VLM |
|
⇧ 549 Likes | |
Open-Source Model |
|
⇧ 2,172 Likes | |
AI Tool |
|
⇧ 1,461 Likes | |
Chatbot Update |
|
⇧ 1,673 Likes | |
Open-source Dataset |
|
⇧ 521 Likes | | |
|
|
|
|
Build Next-gen product with your Audio Data
| AssemblyAI's new speech-to-text model tackles real-world challenges, accurately identifying speakers, key moments, and complex phrases like “Q4 revenue target is $3M.”
Create trusted insights for better meeting summaries, CRM updates, and conversational tools.
|
Try Universal-2 Now ↗️ |
|
|
|
TOP PAPERS
| Reasoning LLM |
|
⇧ 821 Likes | Problem
Existing AI models excel in structured tasks but struggle with open-ended reasoning, where answers are ambiguous, and metrics are undefined.
Solution
Alibaba developed Marco-o1, a Large Reasoning Model (LRM) designed for real-world problem-solving. It integrates Chain-of-Thought (CoT) fine-tuning, Monte Carlo Tree Search (MCTS), and adaptive reasoning strategies to tackle complex challenges effectively.
Results
Marco-o1 outperforms earlier models, boosting MGSM dataset accuracy by 6.17% (English) and 5.60% (Chinese). Its dynamic reflection mechanism helps you refine solutions, while improvements in translation tasks capture cultural nuances. Upcoming updates will enhance decision-making with reward modeling, making it even more reliable.
|
| Evaluation Method |
|
⇧ 1,452 Likes | Problem
AI model evaluations often focus on benchmarks with diverse questions. However, it's unclear whether differences in model performance are due to real improvements or random chance. Current evaluation methods lack statistical rigor, making it hard to interpret results meaningfully.
Solution
Anthropic's research provides statistical recommendations for more reliable eval reporting. It advocates using the Central Limit Theorem (CLT) for better measurement, clustering standard errors when questions are related, and reducing variance within questions. It also emphasizes paired difference tests for comparing models and introduces power analysis to guide eval design.
Results
The paper demonstrates that applying CLT and clustering standard errors improves accuracy, while paired difference tests reduce variance and offer clearer insights. Power analysis helps determine the number of questions required for meaningful tests. By adopting these methods, researchers can report eval results with greater precision and confidence. |
| Object Tracking Model |
|
⇧ 1,273 Likes | Problem
SAM 2 performs well in object segmentation, but it struggles with visual object tracking, particularly in crowded scenes or when dealing with fast-moving or occluded objects. The fixed-window memory approach does not optimize memory selection, which leads to error propagation and inaccurate tracking.
Solution
This paper introduces SAMURAI, an enhanced version of SAM 2 designed for visual tracking. SAMURAI incorporates motion cues to improve object motion prediction and refine mask selection. It also introduces an optimized memory selection mechanism that prevents errors, especially in crowded scenes, by prioritizing relevant memory. SAMURAI works in real-time and requires no retraining or fine-tuning.
Results
SAMURAI shows significant improvements in tracking performance. It achieves a 7.1% AUC gain on LaSOText and a 3.5% AO gain on GOT-10k. SAMURAI outperforms other trackers and matches the performance of fully supervised methods, highlighting its robustness and potential for real-world applications in dynamic environments.
|
| |
| |
|
|
PYTHON TIP
| Build Dynamic ML Pipelines with Minimal Code | Python Fire is excellent for creating CLIs to dynamically run ML or data science functions without predefining argument parsing logic.
How it Works Use fire.Fire() on any Python object (function, class, or module) to turn it into a CLI. This simplifies running experiments or testing with different parameters.
Why to Use
Auto-generates CLIs for ML tasks.
Facilitates rapid experimentation.
Reduces boilerplate code for argument handling. Example |
import fire

def train_model(data_path, epochs=10, lr=0.001):
    """
    Train a model.
    Args:
        data_path (str): Path to training data.
        epochs (int): Number of epochs.
        lr (float): Learning rate.
    """
    print(f"Training with data=,
            epochs=, lr=")

if __name__ == "__main__":
    fire.Fire(train_model)
| How to Use
From the command line, run the following code:
|
python script.py --data_path="data.csv" --epochs=20 --lr=0.01
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
