| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 28 sec | 🎖️ Top News
📌 WorkOS
Enterprise-ready AI with SSO, SCIM, RBAC. Robust security, Quick integration, free user management, trusted by top startups.
⚡️ Trending Signals
⚙️ Top Lectures
🧠 Deep Dive
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| AI Agents | LLMs Outpace Humans in Novel Idea Generation |
⇧ 4, 996 Likes |
 |
What's New |
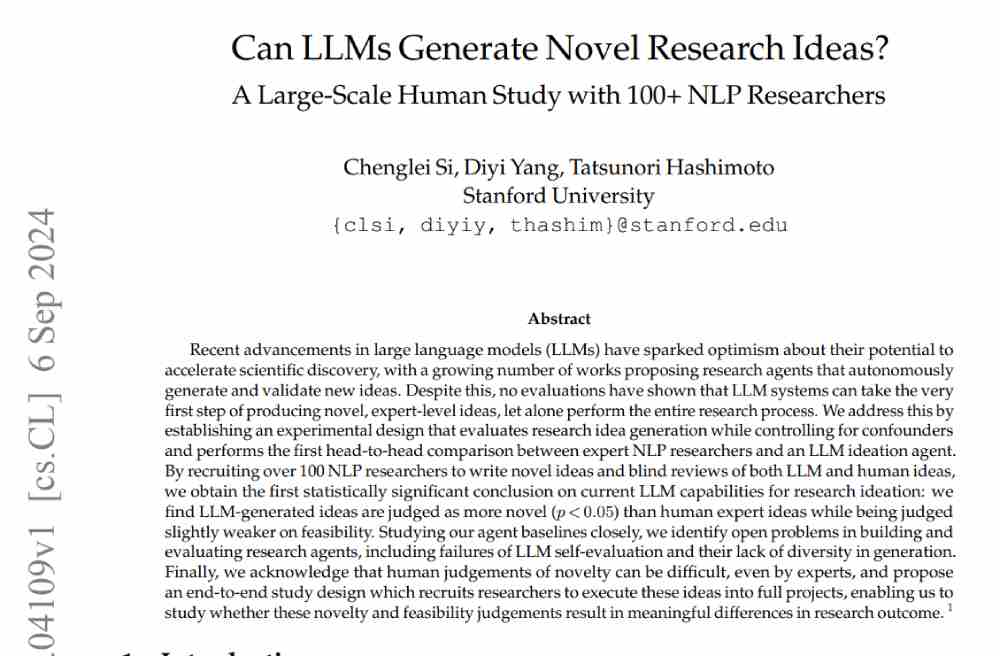
Stanford researchers conducted a large-scale comparison of research ideas generated by large language models (LLMs) and human NLP experts. The study concludes that the AI generated research ideas are more novel and exciting than experts in the field, with no significant difference in the idea's feasibility.
Overview of study process Over 100 experts from 36 institutions, mostly PhDs and postdocs, contributed to idea generation and blind review processes. Those human experts perform blind review of 49 ideas from each of the three conditions: expert-written ideas, AI-generated ideas, and AI-generated ideas reranked by a human expert. Then they standardized the format and style of ideas from all conditions before the blind review. Finally they found AI ideas are judged as significantly more novel than human ideas (p < 0.05 )
The study employed an LLM ideation agent using retrieval-augmented generation, overgeneration (4000 per topic), and LLM-based ranking. Researchers implemented strict controls to ensure fair comparison, including standardized idea formats and matched topic distributions between AI and human ideas. They used an LLM to normalize writing styles while preserving original content.
Expert reviewers evaluated ideas on multiple criteria Novelty Excitement Feasibility Expected effectiveness Overall quality
The study also revealed some limitations in LLM idea generation
Only 5% of AI-generated ideas were non-duplicates, indicating a lack of diversity. LLM-based idea evaluation also showed weaknesses, with the best LLM evaluator achieving 53.3% accuracy compared to 56.1% human inter-reviewer consistency. |
|
|
Read the paper
|
|
|
|
| WorkOS for AI: integrate in minutes and deploy enterprise plans on day 1 | Selling AI to enterprise means getting serious about security, user identity, and access management — involving features like single sign-on, SCIM, and RBAC/FGA.
With WorkOS, you can proactively drive enterprise growth with a few lines of code.
Flexible and easy-to-use APIs help you ship enterprise features in minutes instead of months. User management is free up to 1 million MAUs and comes with bot protection, MFA, and roles and permissions. Great user experience all around — from high-quality documentation for your engineers, to self-serve onboarding for your customers.
WorkOS is trusted by the hottest AI startups: Perplexity, Copy.ai, Cursor, Jasper, and many others. |
|
Start integrating today
| partner with us |
|
|
|
TRENDING SIGNALS
| AI in Healthcare |
|
⇧ 3,800 Likes | |
LLM Benchmarks |
|
⇧ 886 Likes | |
Computer Vision |
|
⇧ 464 Likes | |
Transformers |
|
⇧ 667 Likes | |
Future of AI |
|
⇧ 5,432 Likes | | |
|
|
|
|
|
TOP LECTURES
| LLM Inferencing |
|
⇧ 185 Likes |
Learn about Cerebras' breakthrough in LLM inference speed and integrating with LlamaIndex. You'll discover how their Wafer-Scale Engine-3 achieves 1800 tokens/second for Llama 3.1-8b and 450 tokens/second for Llama 3.1-70b. Explore the CS-3 system's scalability through clustering and its API integration. Includes example code of deploying this high-throughput LLM api using Cerebras Cloud or with on-premise solutions. |
| Prompting |
|
⇧ 5,400 Likes |
This feature caches static content in prompts, reducing processing time and costs. You'll understand how to implement caching, its pricing structure, and best practices. Discover strategies for optimizing different use cases like conversational agents and document processing. Gain insights into cache performance tracking and troubleshooting common issues. |
| LLM |
|
⇧ 5,100 Likes | You'll code a simple tokenizer, implement GPT-2 and Llama 2 architectures, pretrain models and perform instruction finetuning. You'll also learn to evaluate model performance using benchmarks and conversational tests. |
| |
| |
|
|
DEEP DIVE
| LLM Inferencing | How to use Enum Mode in Gemini API to constrain the model to pick between pre-defined options |
⇧ 871 Likes |
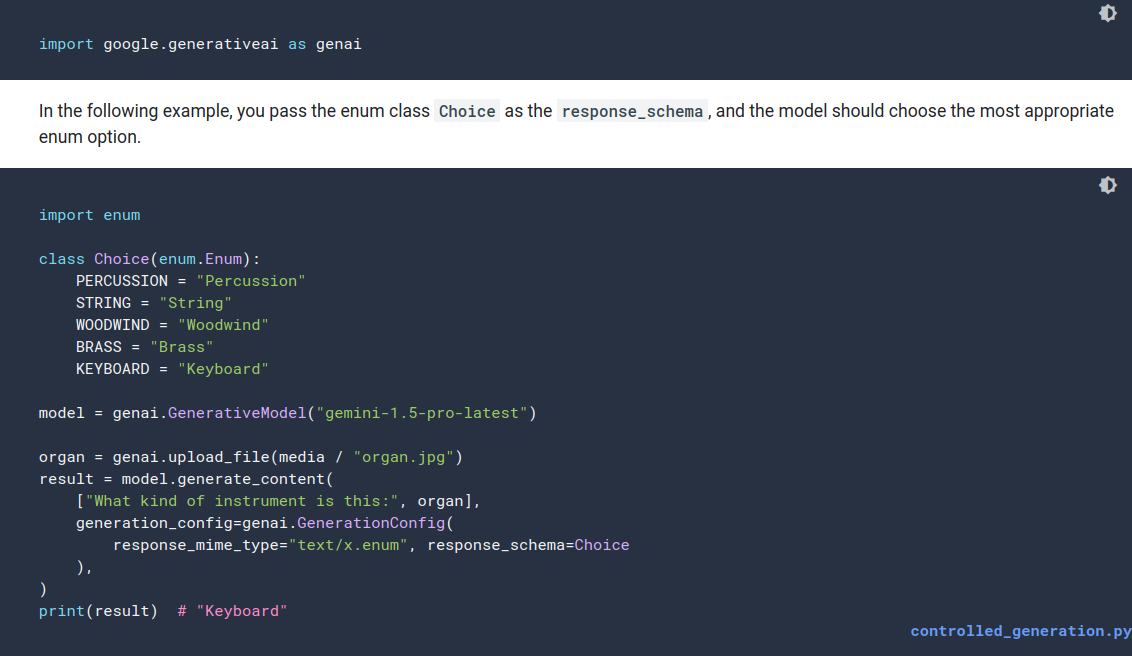 |
Enum Mode is a new Structured Outputs variant in the Gemini API.
It helps you constrain LLM outputs to predefined options.
When to use
Use it in cases you might want the model to choose a single option from a list of options. For example, for multiple-choice tasks or to limit responses in complex schemas.
How to Implement Enum Mode
In the example code in the above image, you pass the enum class "Choice" as the response_schema, and the model should choose the most appropriate enum option Set `response_mime_type` param to "text/x.enum"
Alternatively, pass the enum directly in a dictionary without defining a class.
Apply Enum Mode in JSON schemas or function calling for more granular control.
Try the enum quickstart Colab to get started with this feature.
|
|
Read the guide
|
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Advertise
|
|
|
|
|
