Hey, | Welcome to today's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries are there to keep you up-to-date with the latest breakthroughs in AI.
Let's get into it,
Lior | |
|
|
|
IN TODAY'S SIGNAL
| TOP REPO
KOLENA WEBINAR
TOP SIGNALS
TOP PAPERS
Diffusion on Syntax Trees: improves code generation efficiency by 20%, using a noise process for syntax tree edits.
SaySelf: reduces confidence calibration error by 30% in LLMs, through self-reflective rationales and multiple reasoning chains.
Grokfast: significantly reduces training iterations, accelerating the grokking process by 50 times in machine learning models.
PYTORCH TIP |
Read Time: 5 min 03 sec |
|
|
|
Enjoying this newsletter?
Please forward it to a friend or colleague. It helps us keep this content free.
|
|
|
|
TOP REPO
| Object Detection | YOLOv10: The Best Real-Time End-to-End Object Detection Model |
⇧ 7132 Likes |
 |
What's New |
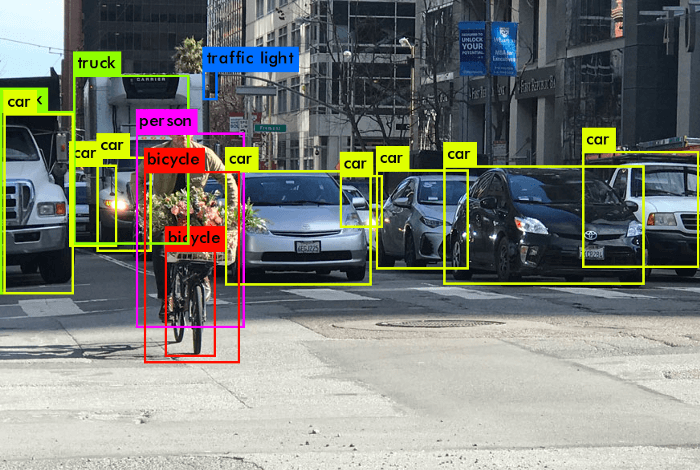
YOLO (You Only Look Once) is a real-time object detection framework known for balancing performance and efficiency. It is used in applications like autonomous driving, robot navigation, and object tracking, where rapid and accurate identification of objects is critical.
YOLOv10 is particularly performant, achieving 46% less latency and 25% fewer parameters than its predecessors.
The GitHub repo has gained significant attention, receiving 7,000 stars in one week.
Core Innovation YOLOv10 eliminates the need for non-maximum suppression with consistent dual assignments, reducing latency and improving efficiency. It builds on CSPNet for better gradient flow and uses PAN layers for multiscale feature fusion.
Key features
- Lightweight Classification Heads: Depth-wise separable convolutions.
- Spatial-Channel Decoupled Downsampling: Minimize information loss.
- Rank-Guided Block Design: Optimal parameter utilization.
Performance Metrics - YOLOv10-S: 1.8x faster than RT-DETR-R18 with similar AP on the COCO dataset.
- YOLOv10-B: 46% less latency and 25% fewer parameters than YOLOv9-C with the same performance.
Model Variants - Nano (N): For resource-constrained environments.
- Small (S): Balances speed and accuracy.
- Medium (M): General-purpose use.
- Balanced (B): Higher accuracy with increased width.
- Large (L): Higher accuracy at increased computational cost.
- Extra-Large (X): Maximum accuracy and performance.
| |
Access | Install Mamba-2 with !pip install mamba-ssm and integrate it with PyTorch.
Pretrained models can be accessed on Hugging Face for various sequence tasks. |
from ultralytics import YOLO

# Load a pretrained YOLOv10n model
model = YOLO("yolov10n.pt")

# Perform object detection on an image
results = model("image.jpg")

# Display the results
results[0].show()
| |
Yolov10 repo
|
|
|
|
 | New Webinar: How to Enhance your AI Testing with Metadata | Join Kolena's free webinar focused on the effective utilization of metadata in machine learning and advanced techniques for metadata hydration.
This session is designed for ML industry practitioners looking to elevate the quality and efficiency of their models.
- The benefits of having a variety of metadata
- How metadata makes for potent testing
- The utility of automatically extracted metadata
- Plus a brief demo of how Kolena automatically extracts relevant metadata for various datasets
Stay ahead of the curve and save your seat today. |
|
Register now
| partner with us | | | |
TRENDING SIGNALS
| Graphs |
|
⇧ 4766 Likes | |
Tutorials |
| ⇧ 256 Likes |
| OpenAI |
|
⇧ 1988 Likes | |
Quantization |
| ⇧ 279 Likes
| | Industry |
|
⇧ 1021 Likes | | |
|
|
|
|
TOP PAPERS
| Code Generation |
| ⇧ 5402 |
Problem Autoregressive language models generate code line by line without runtime feedback, making debugging difficult and inefficient.
Solution Shreyas Kapur's neural diffusion model edits syntax trees directly, introducing a "noise" process inspired by fuzzing techniques. This model iteratively refines and debugs code while ensuring syntactic validity.
Results
The model improves efficiency by 20% in inverse graphics tasks, requires 30% fewer nodes, and achieves 99% accuracy for TinySVG with a pixel matching tolerance of 0.005. This approach allows faster, more accurate, and resource-efficient code generation and debugging. | |
Language Models |
|
⇧ 607 |
Problem
Large language models (LLMs) often generate inaccurate information and fail to provide reliable confidence estimates, limiting their applications. Previous methods for confidence estimation, including prompting and training-based approaches, yield suboptimal or binary confidence scores.
Solution
SaySelf, a training framework, improves LLM confidence estimates and generates self-reflective rationales. It uses multiple reasoning chains, semantic clustering, and reinforcement learning with a custom reward function to fine-tune LLMs.
Results
SaySelf reduces confidence calibration error by 30% and maintains task performance on both in-distribution and out-of-distribution datasets. Generated rationales further enhance calibration accuracy. The code is publicly available on GitHub. | |
Grokking | |
| ⇧ 1162 | Problem
Grokking, a phenomenon where models generalize long after overfitting, requires excessive iterations, making it impractical due to high computational costs.
Solution
The "Grokfast" algorithm accelerates grokking by amplifying slow-varying gradients using low-pass filters, either moving average (Grokfast-MA) or exponential moving average (Grokfast-EMA). This technique is easily implementable with a few lines of code.
Results
Experiments show Grokfast accelerates grokking by up to 50 times across diverse tasks, including images, languages, and graphs. This reduces training iterations significantly | | |
|
|
|
|
PYTORCH TIP
| Cutting GPU memory usage in half with sequential backward calls |
Using this simple PyTorch trick, you can cut your GPU memory usage by up to 50% or effectively double your batch size. Instead of summing multiple losses and then calling backward(), you should call backward() on each loss separately. |
# Don't do this
loss1 = compute_loss1(model, images)
loss2 = compute_loss2(model, images)

loss = loss1 + loss2
loss.backward()


# Do this
loss1 = compute_loss1(model, images)
loss1.backward()

loss2 = compute_loss2(model, images)
loss2.backward()
| Why It Works
This approach frees the computational graph after each backward() call, leading to substantial memory savings. For example, if your model originally used 8GB of GPU memory with a batch size of 32, applying this technique could reduce memory usage to 4GB, allowing you to double your batch size to 64. The results will remain identical to the traditional method.
Limitations
This technique only works if you have multiple losses with disentangled computational graphs.
Bonus
The more losses you have, the more memory you will save.
|
|
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics.
|
|
|
|
Want to promote your company, product, job, or event to 180,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
