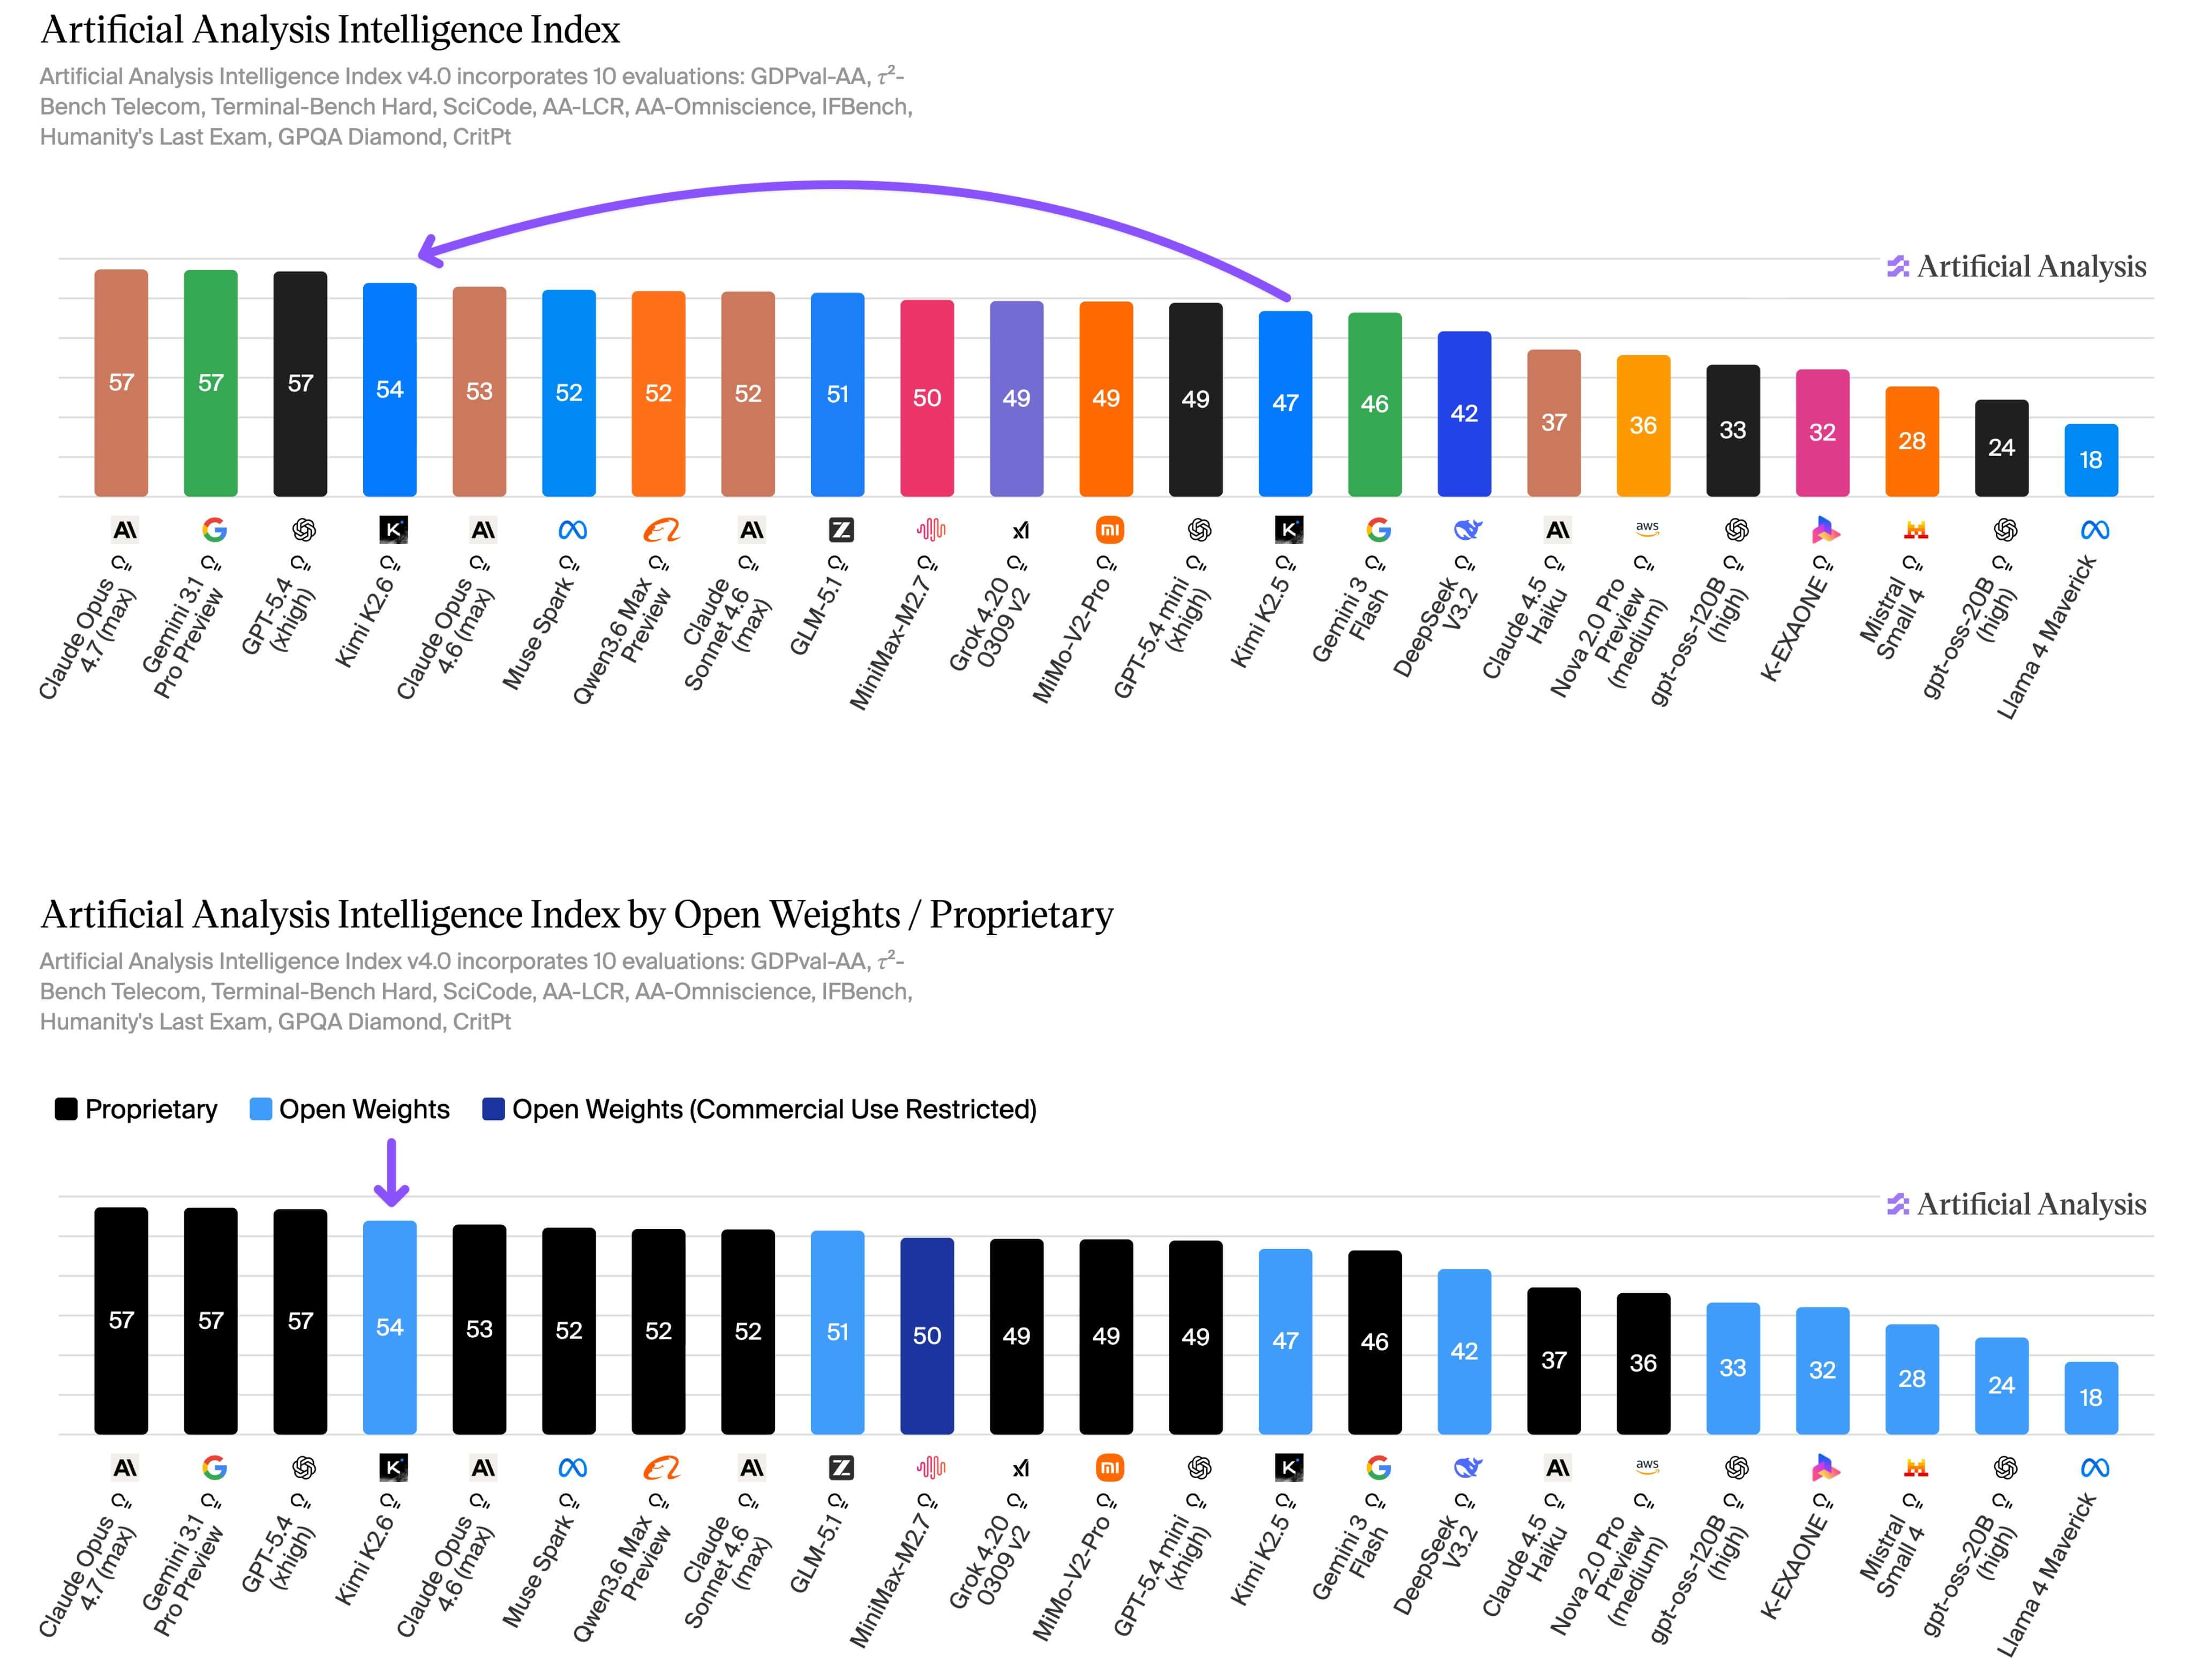
On the back of the release of Claude Opus 4.7 and GPT-5.5, we had a week of significant open source releases. DeepSeek-v4 and Kimi-K2.6, now leading the open source LLM landscape, provide alternative options for developers building AI applications.
These open-weights models provide a path to building systems with massive context windows, multimodal comprehension, and capabilities such as coding and tool-use. While they might not match the capabilities of the latest frontier models, they are more than good enough to support agentic frameworks at scale and low cost.
 DeepSeek-v4: The heavyweight contender
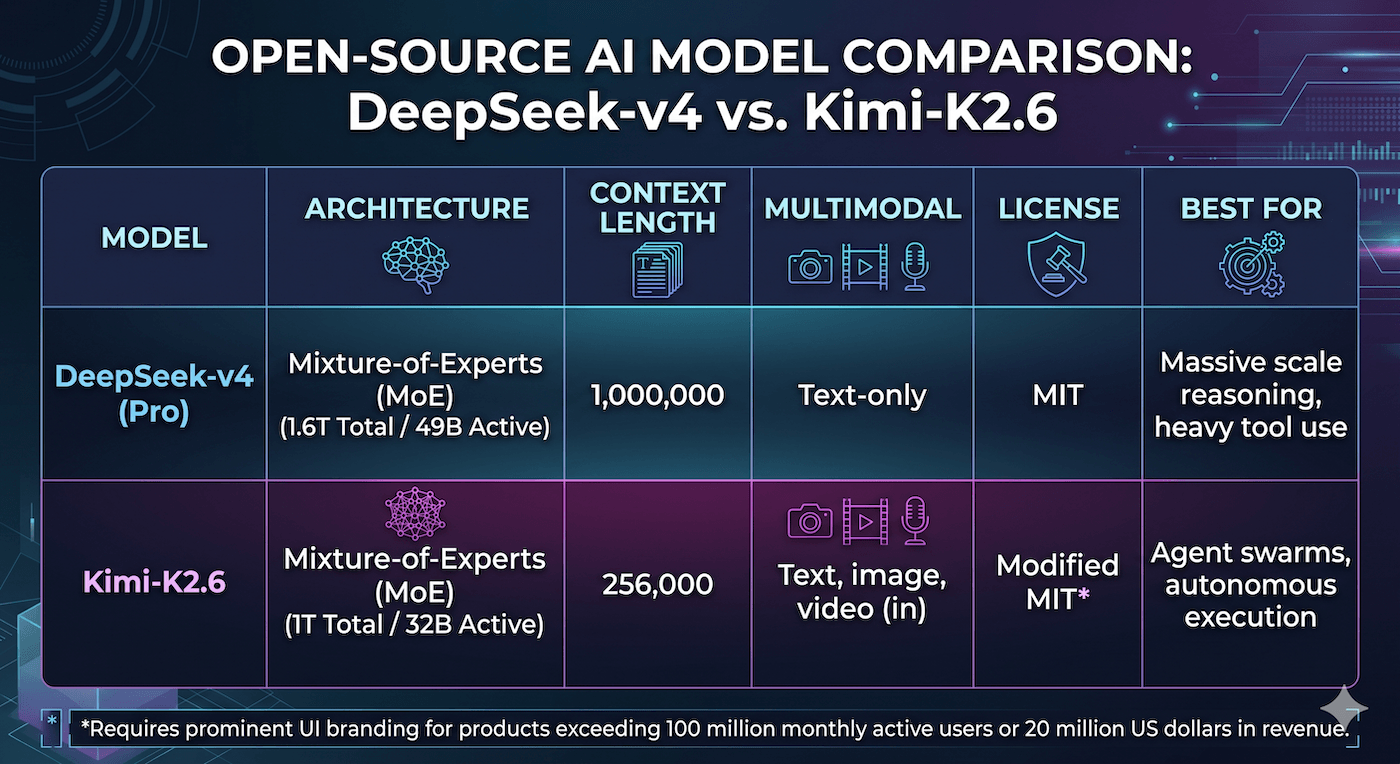
DeepSeek-v4 was the most anticipated open model of the week. It uses a Mixture-of-Experts (MoE) architecture that keeps inference costs manageable while scaling the model's parameter count and knowledge capacity.
The model comes in two sizes:
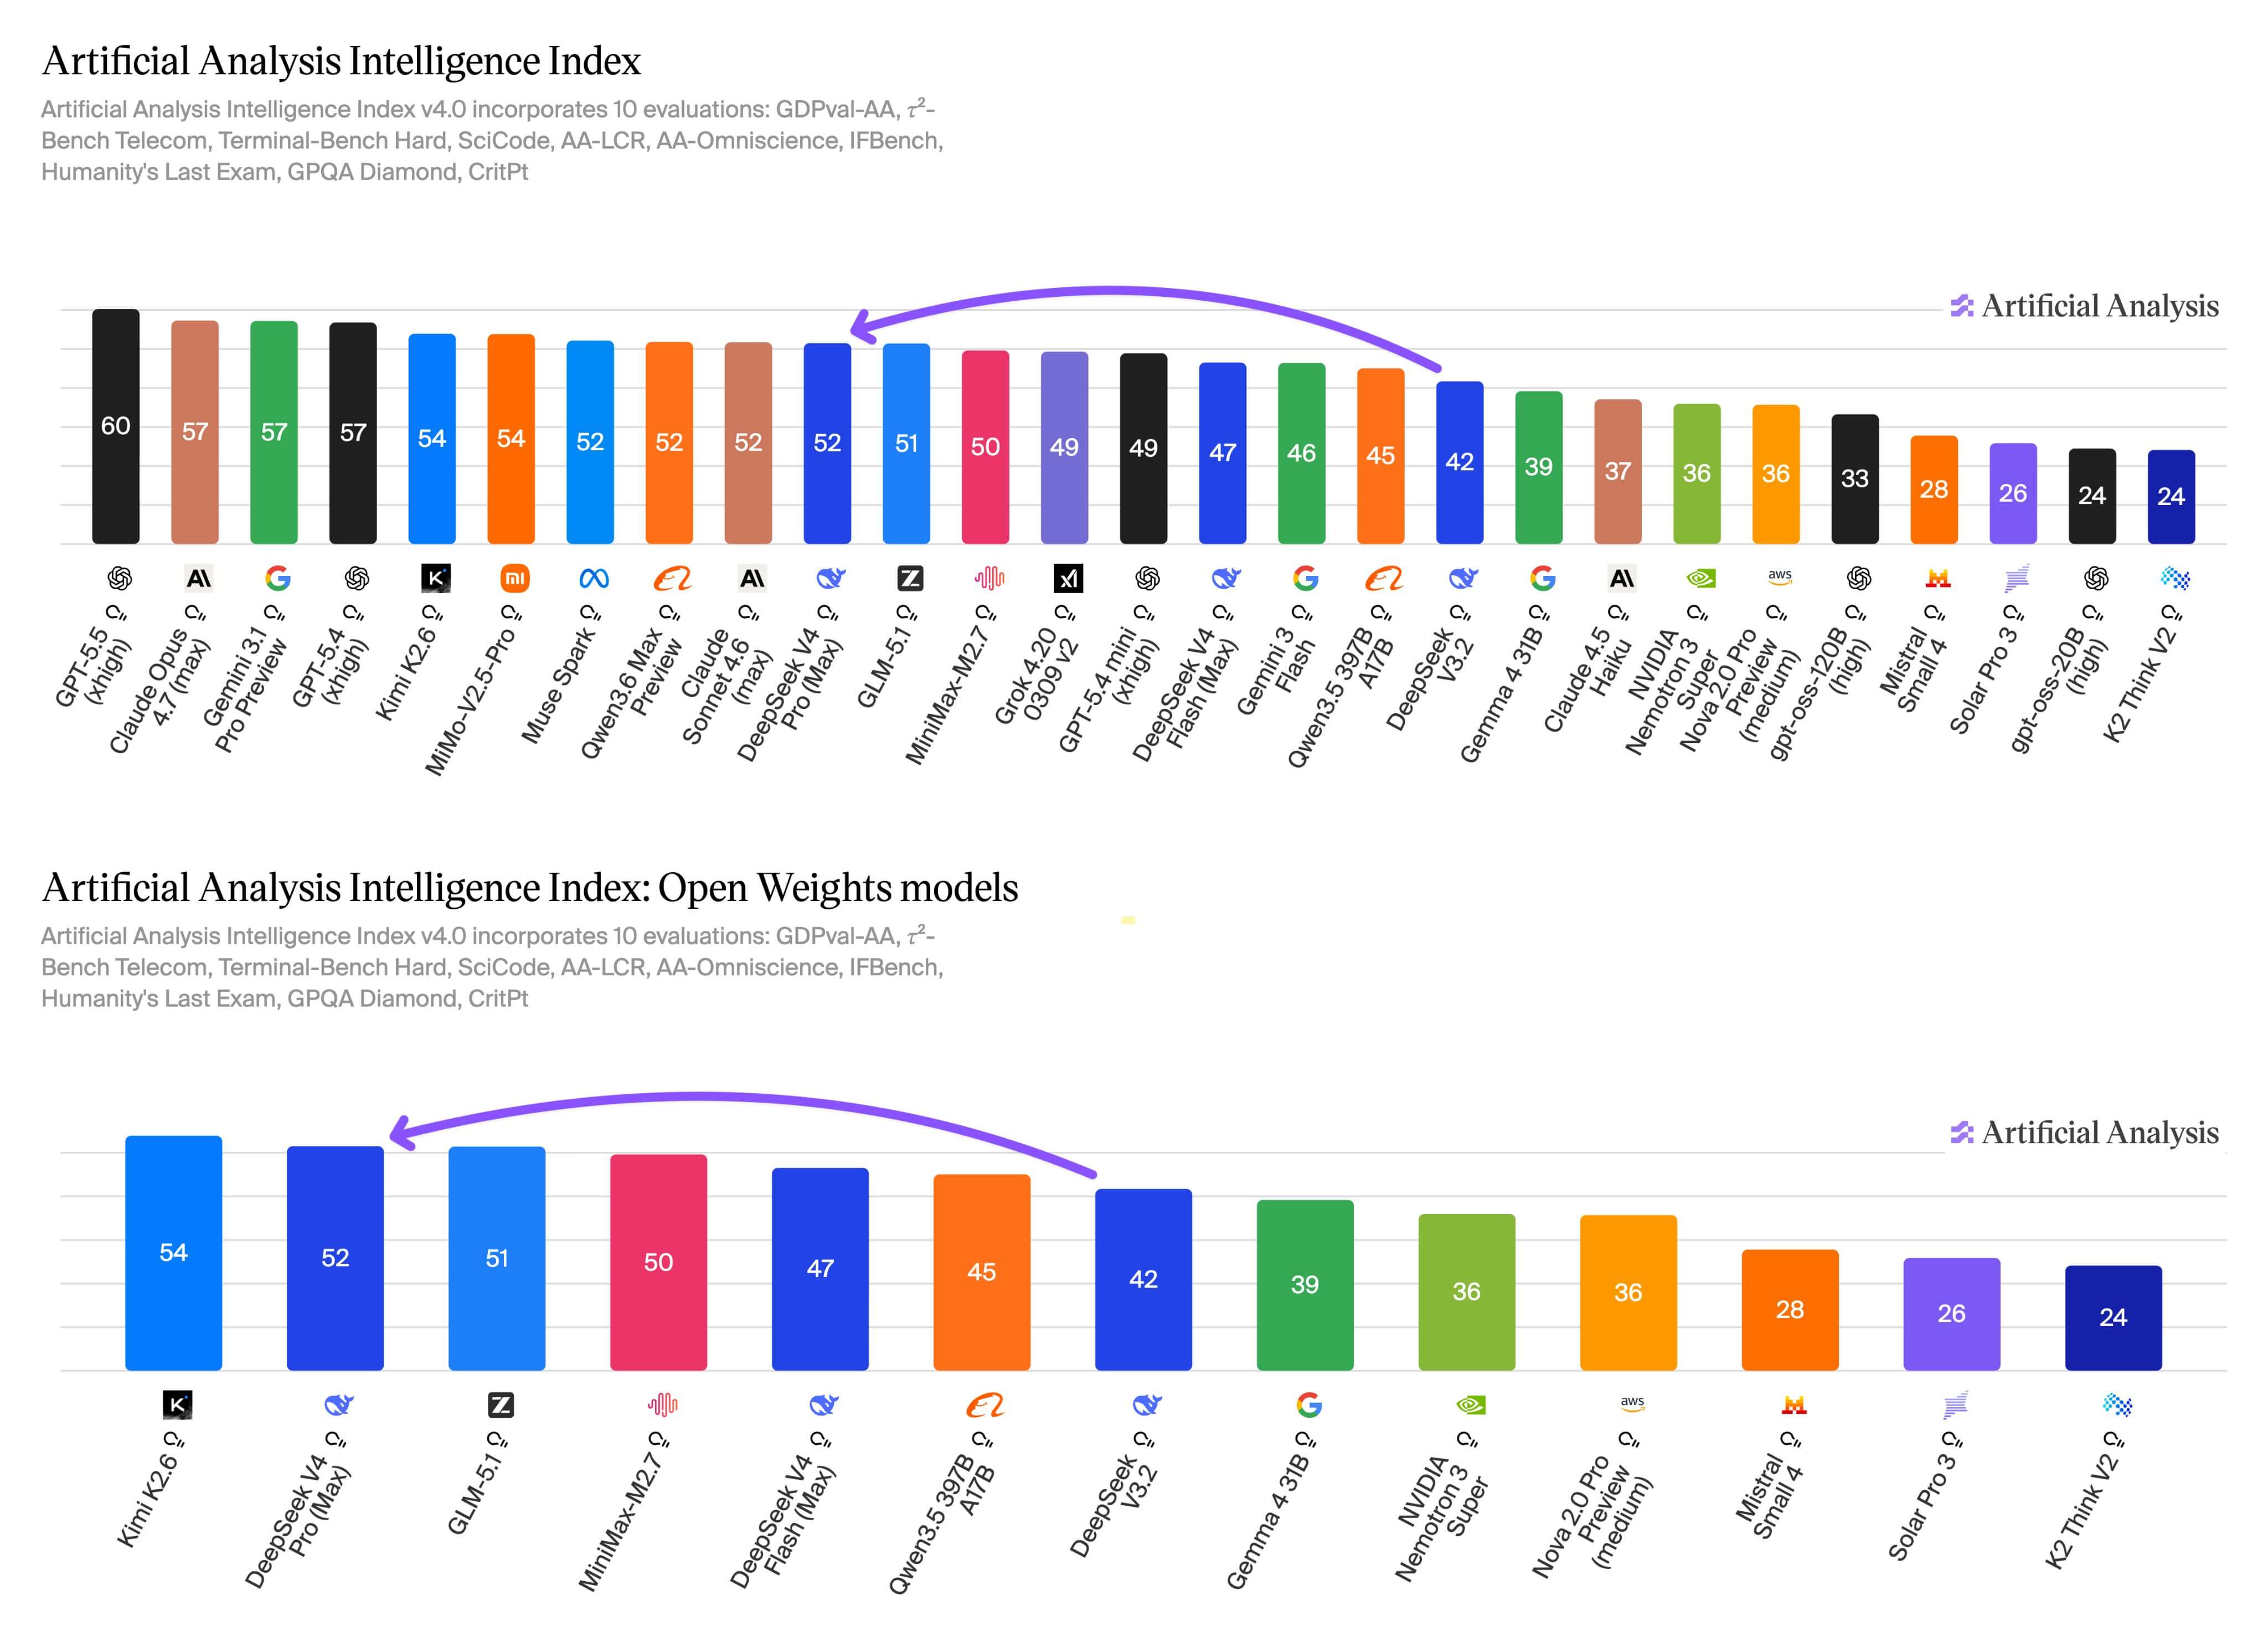
- DeepSeek-v4 Pro: A massive 1.6-trillion parameter MoE with 49 billion active parameters. It currently ranks as the second-leading open model on the Artificial Analysis Intelligence Index behind Kimi-K2.6.
- DeepSeek-v4 Flash: A lighter version with 284-billion total parameters that activates 13 billion for each token for faster, more cost-effective inference.
What I usually like about DeepSeek releases is the architectural innovations. And this one didn't disappoint.
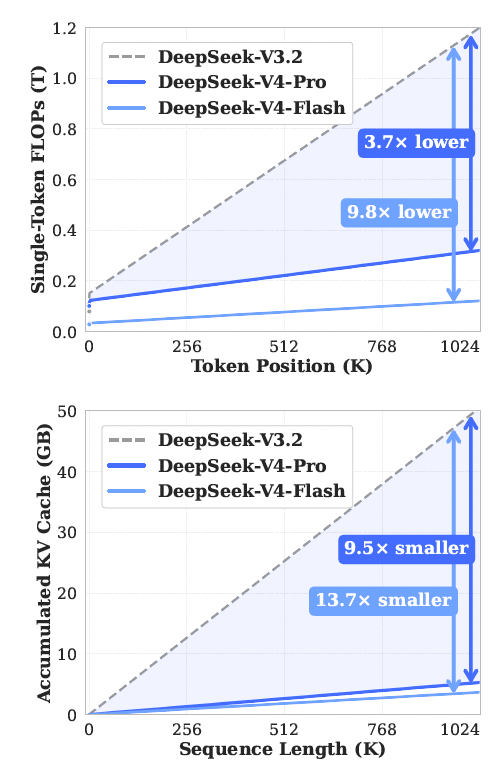
Both Pro and Flash support a massive context window of up to 1 million tokens. However, a 1-million-token context window introduces severe hardware challenges due to the Key-Value (KV) cache, which stores the computed attention values of the tokens in the LLM's context window.
For a million tokens, the KV cache can cause out-of-memory errors or force the system to offload data to slower system RAM. To solve this memory bottleneck, DeepSeek introduces two new attention optimization mechanisms:
- Compressed Sparse Attention (CSA): Compresses the data stored in the KV cache to drastically reduce the baseline memory footprint.
- Heavily Compressed Attention (HCA): Further optimizes memory scaling for extreme context lengths, preventing the linear explosion of memory requirements.
These techniques build on the DeepSeek Sparse Attention (DSA) technique that was introduced in the DeepSeek-v3.2 model. According to the technical report, these optimizations allow DeepSeek-v4 to maintain a 1-million-token context using a fraction of the VRAM required by its predecessor. You can now feed the model entire repositories or extensive API documentation without collapsing your hardware infrastructure.
One of the important characteristics of DeepSeek-v4 is the MIT license, which allows commercial use with no strings attached.
While powerful, developers should note a few tradeoffs:
- Slower speeds and high token consumption: The size and special architecture of the model make it slower than other models in the same class.
- Text-only input: DeepSeek-v4 currently lacks multimodal support, though the technical report indicates the research team is actively working on bringing vision capabilities to future updates.
Kimi-K2.6: The swarm orchestrator
While DeepSeek-v4 was the most anticipated release of the week, Kimi-K2.6 was the most impressive. It currently leads the open models on the Artificial Analysis Intelligence Index. It stands out for its native multimodal capabilities and deep integration with agentic frameworks like OpenClaw and Hermes.
The core architecture features:
- Massive MoE: The model comes with 1 million total parameters, 32 billion active per token (384 total experts, eight active and one shared expert per token).
- Multimodal inputs: Accepts text, image, and video natively, outputting text.
- 256,000-token context window: Enough to handle extensive system prompts, documentation, and historical conversation logs.
Kimi-K2.6 shows exceptional performance in coding tasks and reliable tool use, particularly when orchestrating agent swarms. In traditional workflows, a single model processes a task sequentially, which can lead to context dilution and hallucinations over long horizons. An agent swarm solves this by dividing the labor:
- Task decomposition: A primary orchestrator model breaks a complex goal into smaller sub-tasks.
- Parallel execution: The orchestrator spins up specialized sub-agents. For a web application, one agent handles the database schema, another builds the frontend layout, and a third writes the API routing.
- Dependency management: The model understands which tasks rely on others and coordinates the inputs and outputs across the swarm.
Example of Kimi-K2.6 optimizing an open source project over 13 hours and 1,000 tool calls
Kimi-K2.6 acts as a highly effective orchestrator because it maintains strong adherence to system prompts. This proactive, autonomous execution gives developers a reliable engine for building systems that can debug, refactor, or generate complex software architectures.
One catch to be aware of is that the model operates under a modified MIT license. Developers must prominently display "Kimi K2.6" on their user interface if their product exceeds 100 million monthly active users or generates over 20 million US dollars in revenue. This is not a big deal for most applications, but something to consider if you're a big enterprise (Cursor ran afoul of this recently).
Honorable mention: Qwen3.6-27B
While Kimi and DeepSeek made the main highlights, Qwen3.6-27B silently made its debut last week.
Qwen3.6-27B is a dense model (as opposed to MoE, every token runs through all 27 billion parameters). This size offers specific advantages for developers who want to run the model on a high-end local machine, such as an M-series MacBook Pro or a Mac Studio.
Qwen3.6-27B scores a 46 on the Artificial Analysis Intelligence Index, placing it well above average among comparable open models.
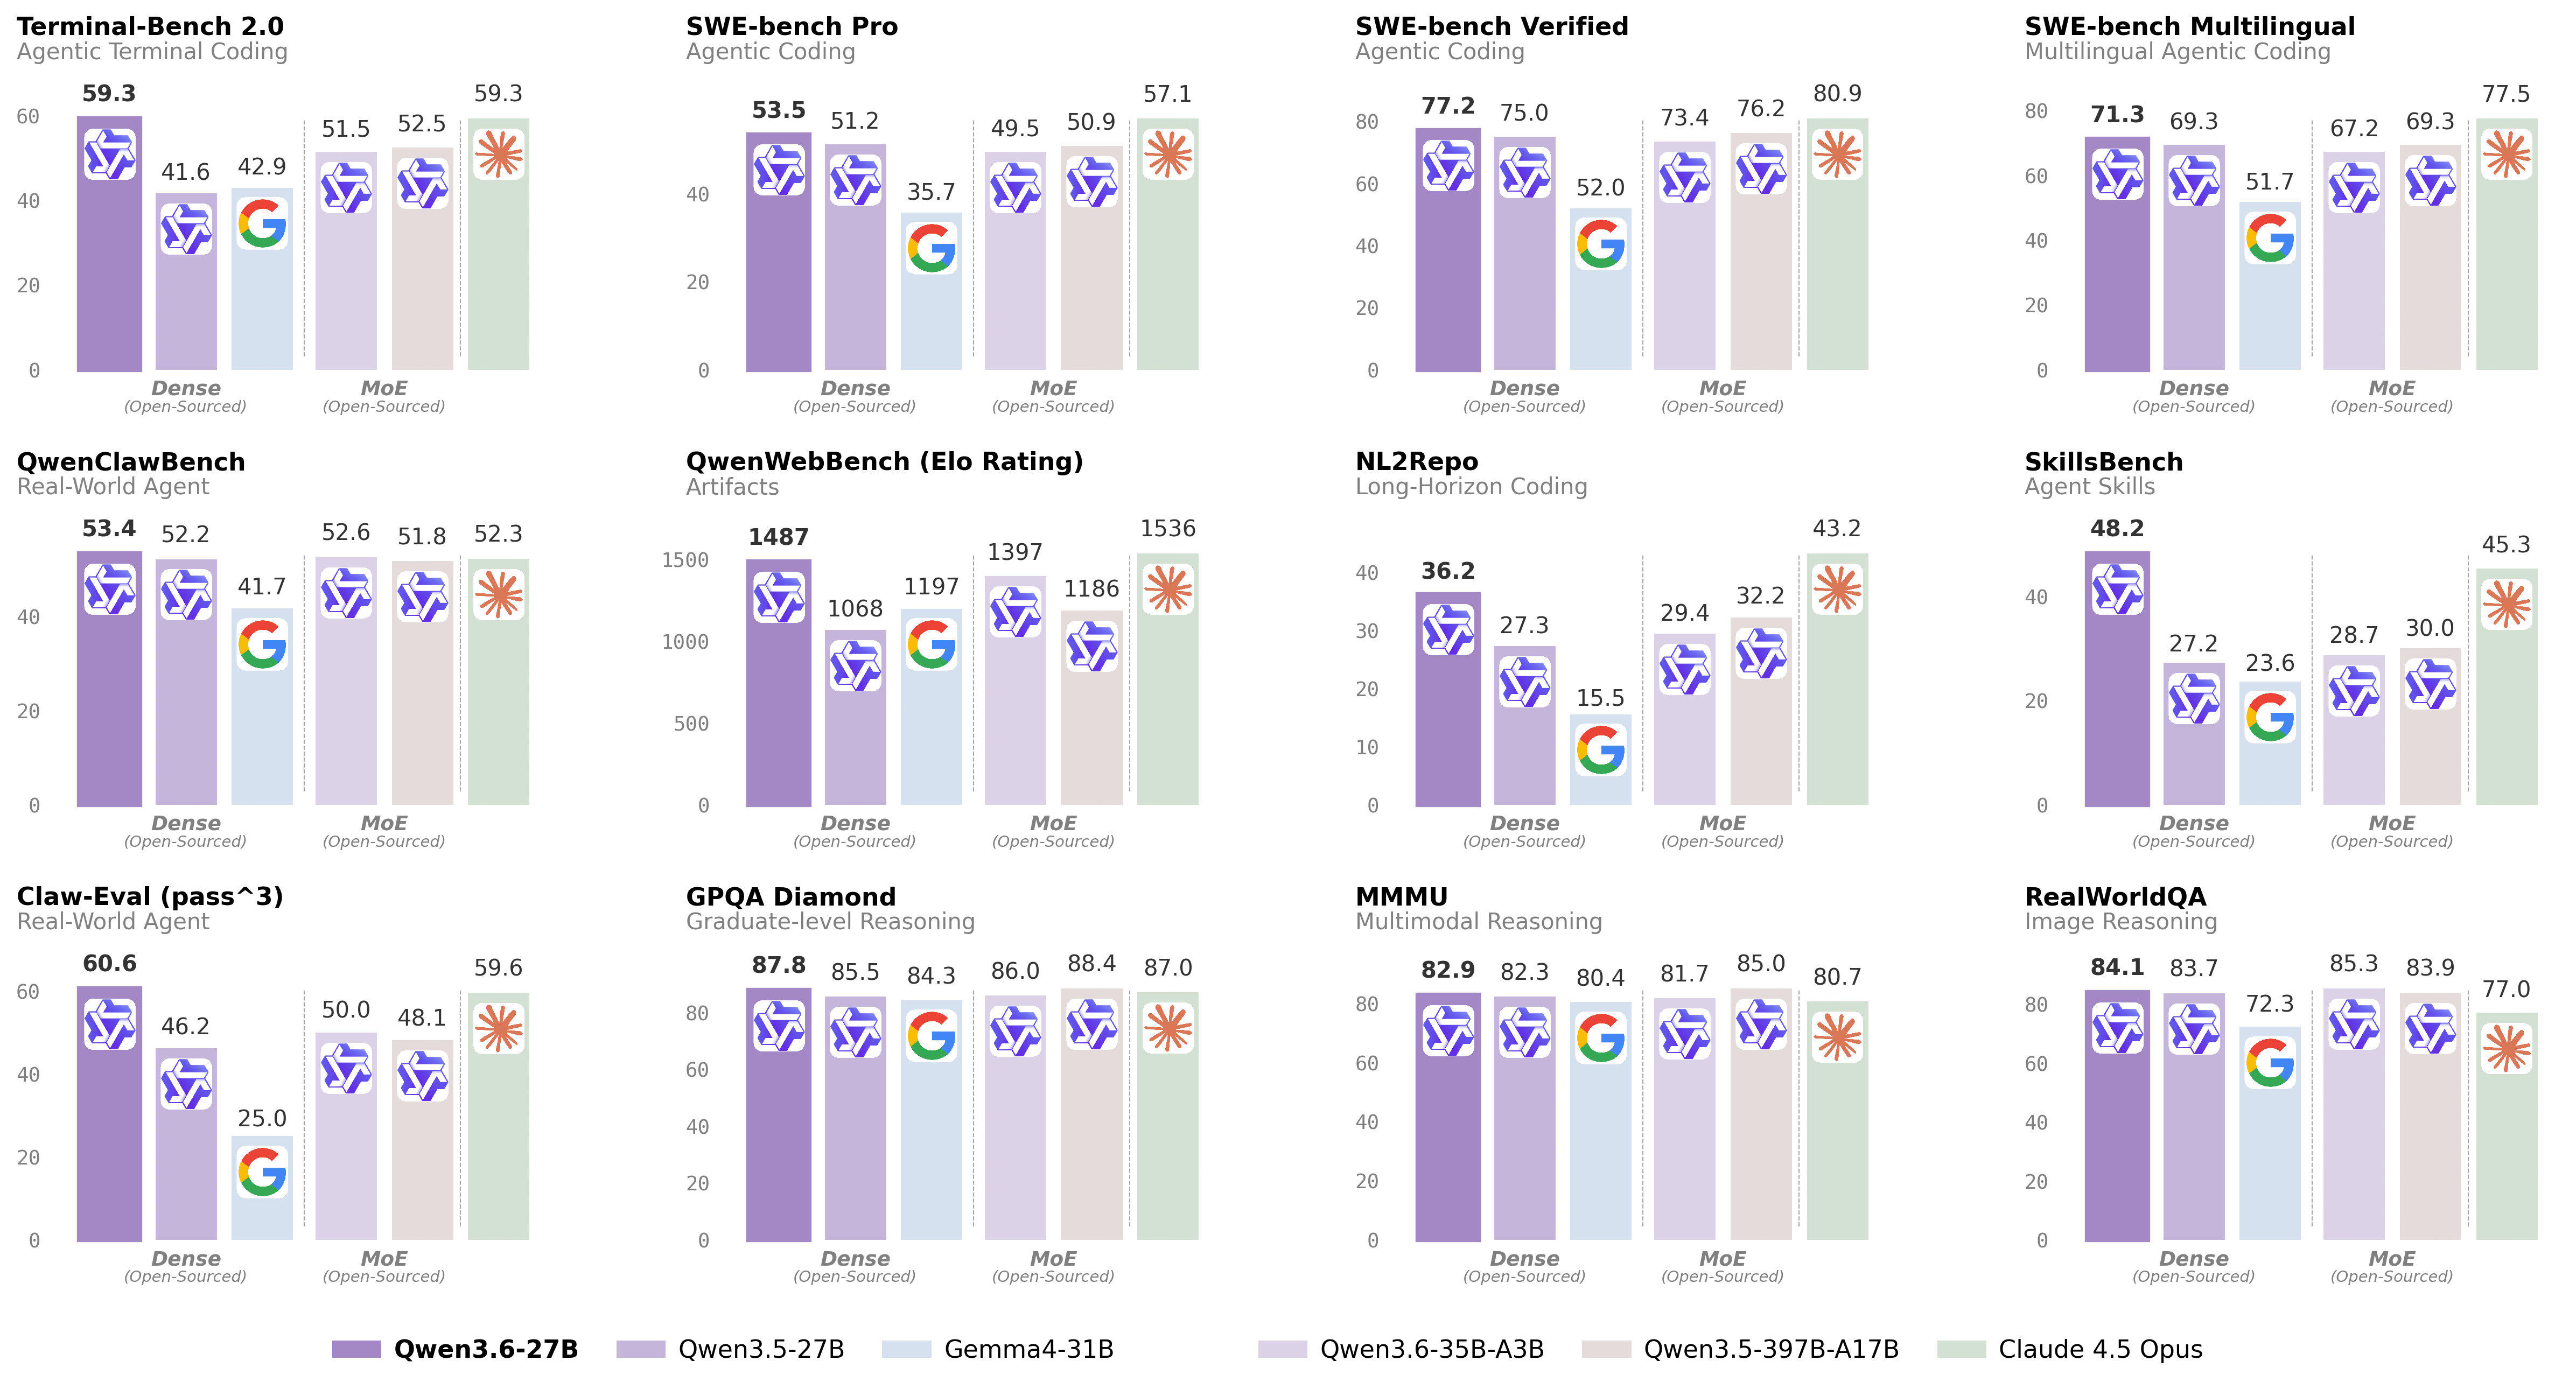
While it tends to be more verbose than its peers, its strong performance in agentic coding tasks makes it an ideal engine for a powerful local development loop.
Qwen3.6-27B was released under the permissive Apache 2.0 license.
Looking ahead
Also released last week was Xiaomi MiMo-V2.5-Pro, which currently matches Kimi-K2.6 in benchmark performance. It currently remains closed and only available through API access, but Xiaomi might release the weights soon.
The current open-source frontier trails the absolute bleeding edge of proprietary models. However, the raw capability of a base model defines only the starting point of an application.
The ultimate usefulness of an AI system depends on the scaffolding and harness you build around it. By applying careful engineering, prompt chaining, context and memory management, and tool integration, developers can achieve the edge they need. With open weights, you maintain full control over the execution environment, allowing you to fine-tune the system entirely to your specific software architecture and workflow requirements.