Open source is eating AI infrastructure from both ends today.
Cursor gives away the kernel that makes training 2.37x faster (named after kittens, because why not). Liquid AI ships a 2.6B agent that runs on your phone. Mistral drops a safety model punching 7x above its weight. The trend is clear: the moat is shrinking fast.
Labs are open-sourcing their crown jewels in real time. The question isn't who has the best model anymore. It's who builds the best product.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Cursor open-sources MoE training kernel that runs 2.37x faster than top baselines
|
|
4,366 Likes
|
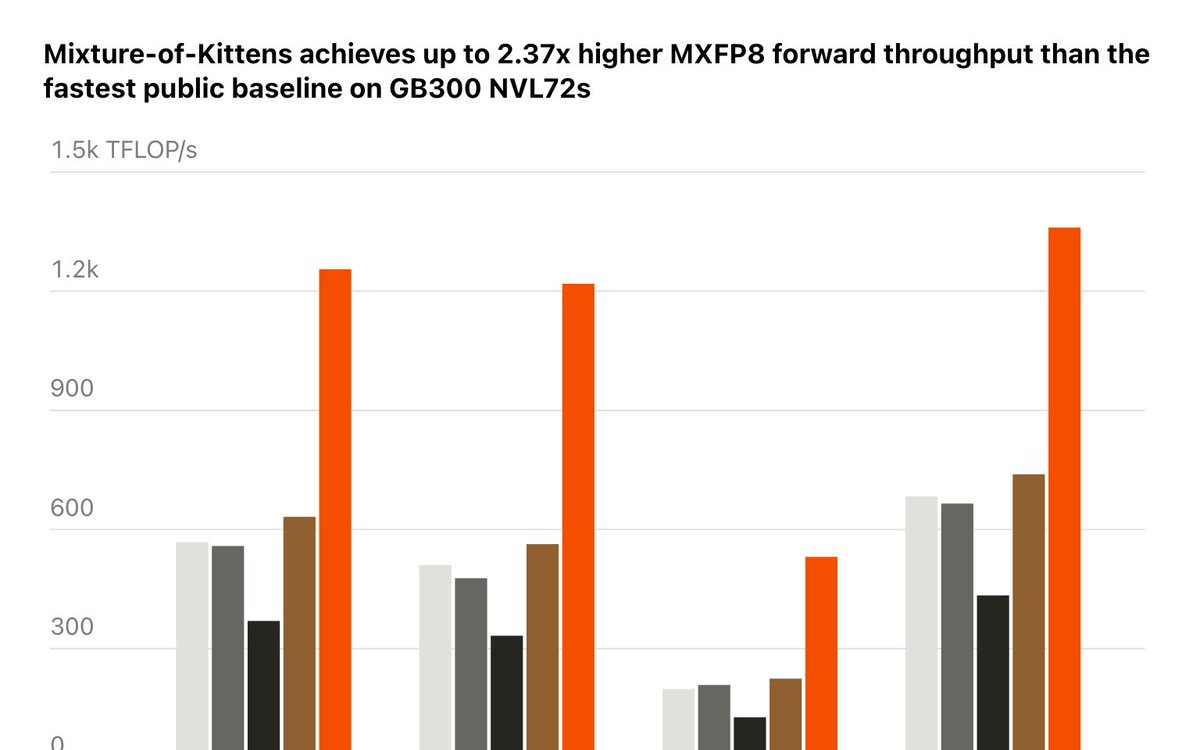
|
Cursor just open-sourced Mixture-of-Kittens (MoK), a tool that makes training large AI models much faster. Here is what you need to know. AI models like Cursor's own coding assistant use a design called Mixture-of-Experts, where only a small group of "expert" sub-networks activates for each input. That MoE layer had become the biggest bottleneck, sometimes eating more than half of total training time. MoK fixes this by doing something clever: it fuses all computation and communication into a single kernel, overlapping GPU math and inter-GPU networking, and fully eliminates CPU-GPU synchronization. The results in production: - Runs up to 2.37x faster than public baselines
- Raised end-to-end training throughput by 1.41x over their previous stack
- Supports BF16 and MXFP8, covering both forward and backward passes
You can try MoK and explore the code on GitHub. It is Apache-2.0 licensed, so you can use it freely in your own projects.
|
|
|
|
Presented by Mistral
|
|
Document AI, powered by the world's best OCR
|
|
Enterprise-grade document processing with Mistral AI's state-of-the-art OCR and data extraction.
- Digitize PDFs, scans, DOCX, PPTX, and handwritten sources
- Read tables, forms, invoices, and complex layouts; validate data and make scanned archives searchable
- Localize contracts and reports with 98%+ accuracy across 170+ languages
- Build E2E pipelines: OCR digitization, automated structuring, and natural language querying
- Redact sensitive data and enforce retention with full traceability
|
|
|
|
Top Repo
|
|
|
|
Nous Research ships Hermes Agent v0.20.0 in new Herald release
|
|
3,886 Likes
|
|
Hermes Agent just dropped v0.20.0, and it's the biggest release in the project's history. Since v0.19.0: roughly 3,650 commits, 1,400 merged PRs, and 1,200 issues closed from over 650 contributors on a repo now sitting at 224,000 GitHub stars. So what actually changed? Four big things: - Real-time voice , voice mode used to mean speak, wait, then listen to one long audio file. Now Hermes speaks clause-by-clause as the response streams, and you can interrupt it mid-sentence just by talking.
- Agent-to-Agent protocol (A2A v1.0) , your Hermes instance can now talk directly to other AI agents using a standard protocol, meaning you can build multi-agent pipelines without custom glue code.
- Outbound webhooks , Hermes can now push signed events to your external systems, so you can trigger dashboards, alerts, or automations automatically.
- Grounded research , responses now come with verifiable citations, so you can actually trust what it tells you.
To grab the update, just run hermes update. That's it.
|
|
|
|
Presented by Tiger Data
|
|
Query Billions of AI Events in Milliseconds
|
|
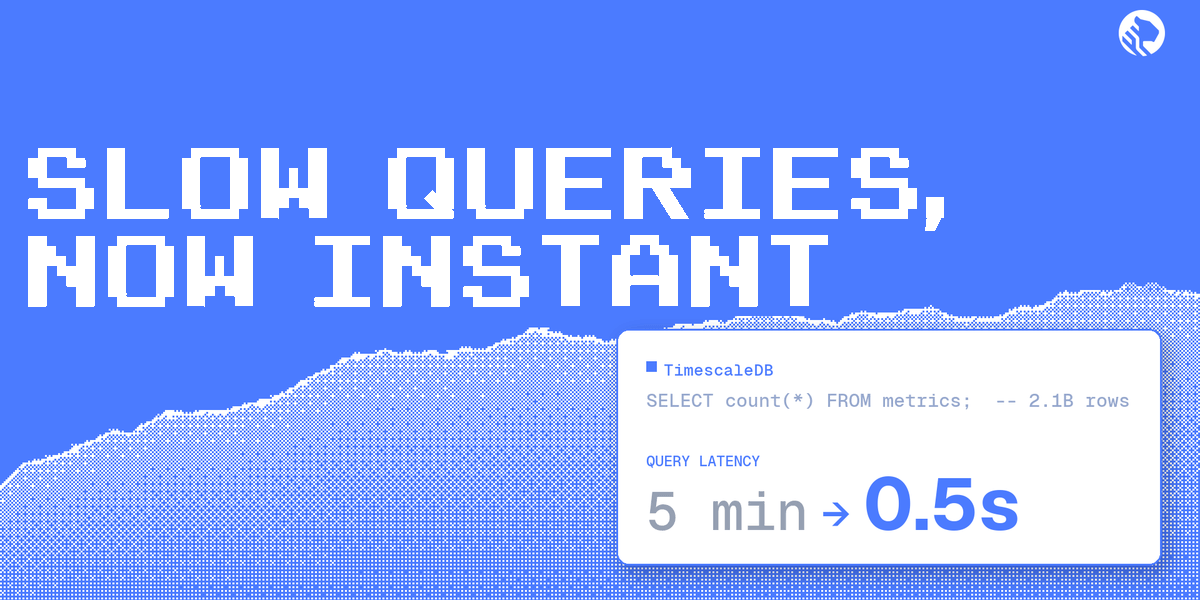
AI apps throw off billions of rows: prompts, embeddings, eval logs, latency traces.
TimescaleDB extends Postgres to query all of it in milliseconds at scale.
Same SQL, hypertables and continuous aggregates under the hood.
Plexigrid cut query times from 5 minutes to half a second.
|
|
|
|
Top News
|
|
|
|
Liquid AI ships a 2.6B open-weight agentic model that runs fully on-device
|
|
3,683 Likes
|
|
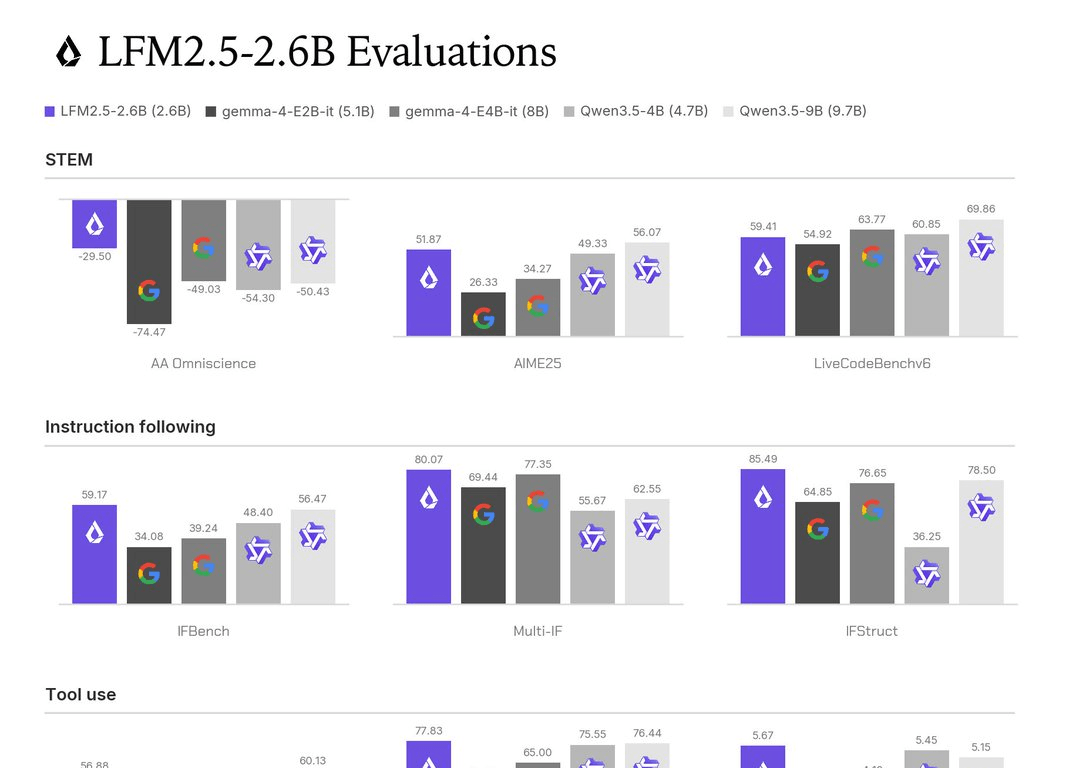
Most small AI models fall apart the moment you ask them to plan across steps or call tools reliably. LFM2.5-2.6B from Liquid AI is a direct push against that wall. It is a tiny but capable agent model that runs fully on your device, no cloud needed. Unlike cloud-based agents, you get free inference, real privacy, and the ability to run agents in parallel on local hardware at no extra cost per run. The numbers are solid for its size: - 220 tokens/s on Apple M5 Max, 113 tok/s on AMD Ryzen, and around 30 tok/s on phones
- Fits in under 2.5 GB of memory
- Beats Qwen3.5-9B on tool use benchmarks despite being 4x smaller
- Coding is the one area where larger models keep a clear lead
It ships with day-one support for llama.cpp, MLX, vLLM, SGLang, and ONNX. To use it, serve it behind an OpenAI-compatible endpoint and point your agent at it. Both base and post-trained versions are on Hugging Face now.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
