|
|
Hey, | Welcome to today's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries ensure you're always up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior | |
|
|
IN TODAY'S SIGNAL
|
Read Time: 4 min 06 sec |
|
|
|
Enjoying this newsletter? Please forward it to a friend or colleague. It will help us keep this content free.
|
|
|
|
TOP NEWS
| Language Models | Google Releases New Infinite Context Method |
⇧ 1683 ⇆ 394 |
 |
What's New | Can LLMs Handle Unlimited Context? Google researchers introduced a new concept called Infini-attention in their latest paper, enabling LLMs to process inputs of any length.
Comparison with Traditional Transformers: Typical transformers reset their attention memory after each context window to manage new data, losing previous context. For example, in a 500K token document split into 100K token windows, each segment starts fresh without memory from the others.
Infini-attention's Approach: Infini-attention retains and compresses the attention memory from all previous segments. This means in the same 500K document, each 100K window maintains access to the full document's context.
The model compresses and reuses key-value states across all segments, allowing it to pull relevant information from any part of the document.
How Infini-attention Works:
- Utilizes standard local attention mechanisms found in transformers.
- Integrates a global attention mechanism through a compression technique.
- Merges both local and global attention to manage extended contexts efficiently.
In other words, the method effectively gives each window a view of the entire document, achieving what's termed as "infinite context."
Key Performance Metrics:
- 1B Model: Effectively manages sequences up to 1 million tokens.
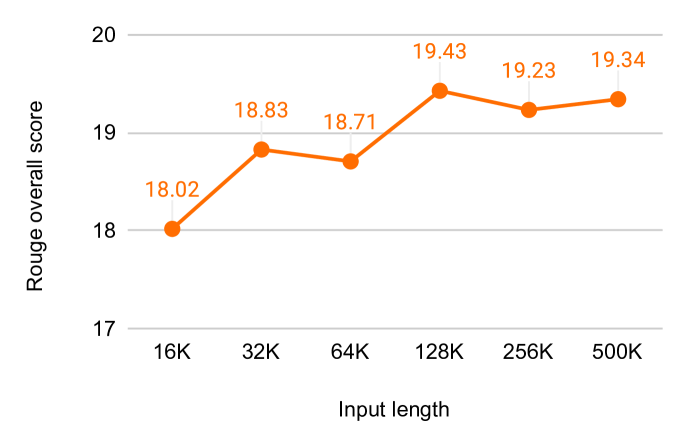
- 8B Model: Achieves state-of-the-art results in tasks like summarizing books up to 500K tokens in length.
Key Highlights:
- Memory Efficiency: Constant memory footprint regardless of sequence length.
- Computational Efficiency: Reduces computational overhead compared to standard mechanisms.
- Scalability: Adapts to very long sequences without the need for retraining from scratch.
| Why This Matters | Elvis Saravia: "Given how important long-context LLMs are becoming having an effective memory system could unlock powerful reasoning, planning, continual adaption, and capabilities not seen before in LLMs. Great paper!"
| Community Feedback |
swyx: "with Griffin and Infini-attention, it increasingly feels like Google leapfrogged Together and RWKV in the race for scaling up linear attention, and they shared a watercooler conversation with Anthropic or something"
Raúl Avilés Poblador: "Sounds good on paper but scaling this to near-infinity would also mean inference would require crazy hardware resources, isn't it?"
|
|
Read the paper
| Get the Pytorch Implementation |
|
|
|
| Revolutionize AI Development with Gretel's Synthetic Data Solutions |
Facing data privacy roadblocks in your AI projects? Our partner Gretel's synthetic data solutions create realistic, anonymized datasets that enable robust AI training without risking sensitive information.
Gretel’s groundbreaking synthetic data platform speeds up development cycles and helps you meet stringent privacy standards with ease, enabling your team to innovate safely and efficiently.
We highly recommend you download their one-page solution brief to learn more!
|
|
Download brief
| partner with us |
|
|
|
TOP OF GITHUB
| Language Models |
|
A collection of guides and examples for the Gemini API, including quickstart tutorials for writing prompts and using different features of the API, and examples of things you can build.
| ☆ 1573 | |
Code Assistants | |
|
Aider is a command line tool that lets you pair program with GPT-3.5/GPT-4, to edit code stored in your local git repository. Aider will directly edit the code in your local source files, and git commit the changes with sensible commit messages. You can start a new project or work with an existing git repo. Aider is unique in that it lets you ask for changes to pre-existing, larger codebases.
| ☆ 8922 | |
RAG | |
RAGFlow is an open-source RAG (Retrieval-Augmented Generation) engine based on deep document understanding. It offers a streamlined RAG workflow for businesses of any scale, combining LLM (Large Language Models) to provide truthful question-answering capabilities, backed by well-founded citations from various complex formatted data. |
☆ 4709 | | |
|
|
|
|
Give Your Honest Opinions on Building with AI
| How satisfied are you with your current AI stack? Do you think your company is allocating GPUs correctly? What are you most excited to see in the next generation of models and tools?
Share your thoughts on the evolving state of AI in the newest State of AI survey. (You could win a $500 Amazon gift card!)
|
Share thoughts ↗️ |
|
|
|
TOP LECTURE
| Language Models | Build an LLM from Scratch Chapter 5: "Pretraining an LLM on Unlabeled Data" |
☆ 13,532 |
 |
What's New |
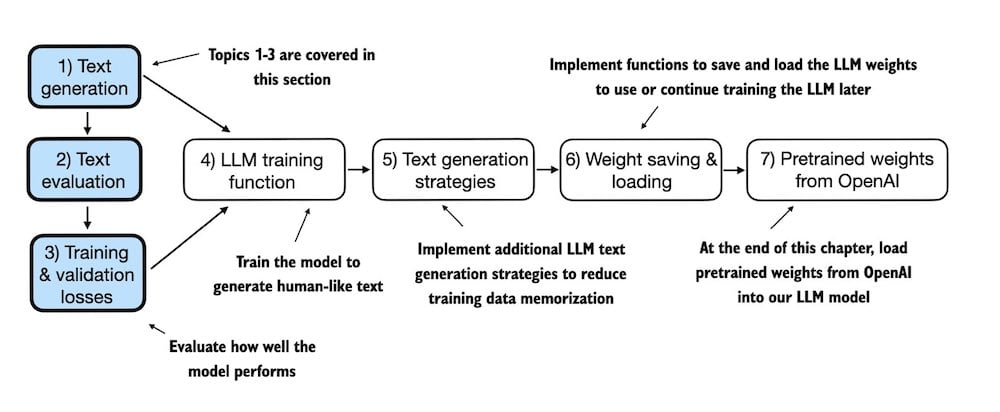
Chapter 5 of Sebastian Raschka's "Build an LLM from Scratch" book, titled "Pretraining an LLM on Unlabeled Data," is now available. This chapter advances the series by focusing on the implementation of a training function and the initiation of pretraining for the LLM.
Key topics covered include:
- Computing the training and validation set losses to assess the quality of text generated by the LLM during training.
- Implementing a training function and starting the pretraining process.
- Techniques for saving and loading model weights, allowing for the continuation of training at different stages.
- Loading pretrained weights from OpenAI to enhance model performance.
|
|
Check the repo
|
|
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics.
|
|
|
|
Want to promote your company, product, job, or event to 175,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
