
Alibaba's Qwen2.5-Coder-32B Beats GPT-4o on Code and Runs on a Laptop
Alibaba's 32B open-weight coder matches GPT-4o on code generation, runs locally on a MacBook, and ships under Apache 2.0.
Takeaways
- Alibaba released Qwen2.5-Coder-32B-Instruct, an Apache 2.0 open-weight coding model matching GPT-4o.
- Scores SOTA on EvalPlus, LiveCodeBench, BigCodeBench, and 75.2 on MdEval code repair.
- Hits 74% on Aider's edit benchmark, beating GPT-4o's 71% on the same task.
- 32.5B params, 128K context via YaRN, trained on 5.5T tokens across 92 languages.
- Runs locally on a 64GB MacBook, or via Ollama, vLLM, SGLang.
- Full family covers 0.5B to 32B, all sharing the same tokenizer and chat template.
Alibaba's Qwen team just dropped what may be the strongest open-weight coding model available. Qwen2.5-Coder-32B-Instruct is a 32-billion parameter model that goes toe-to-toe with GPT-4o on code generation benchmarks, ships under the permissive Apache 2.0 license, and is small enough to run on a well-specced laptop.
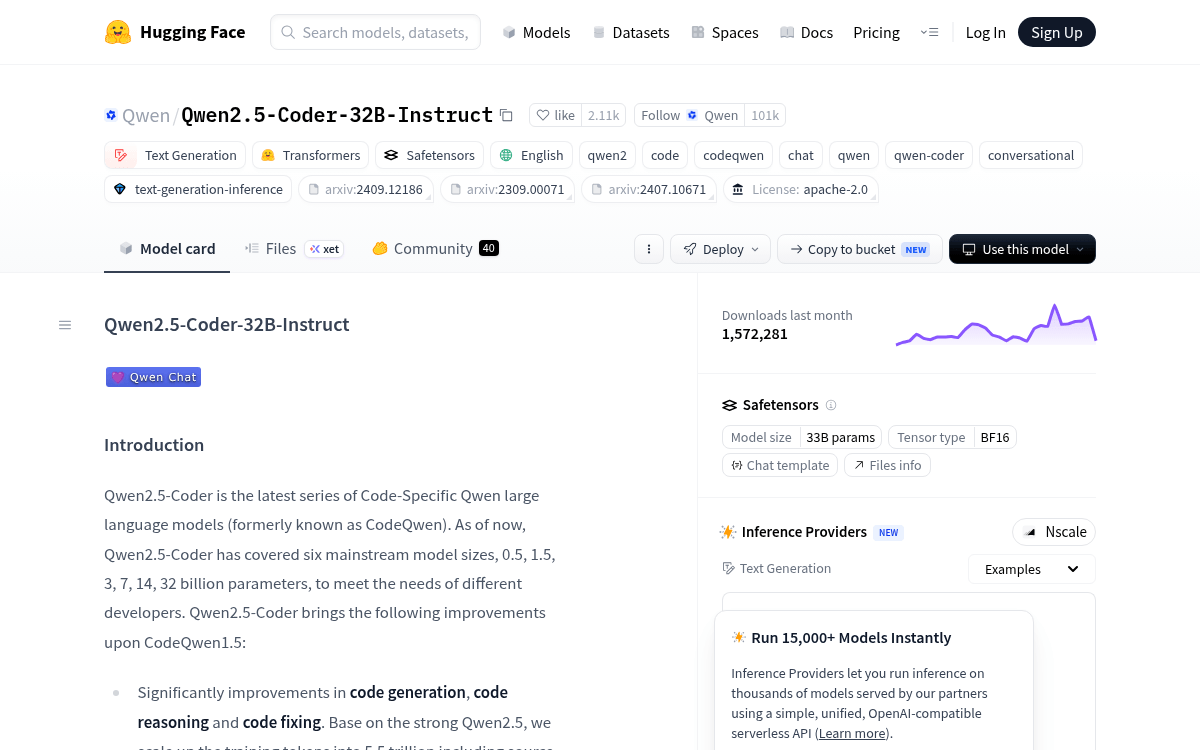
The release is part of a full family covering six sizes (0.5B, 1.5B, 3B, 7B, 14B, and 32B), but the 32B Instruct variant is the headliner. It has already crossed 1.5 million downloads on Hugging Face and become the default open-source pick for local coding assistants.
Benchmarks that actually moved
Qwen2.5-Coder-32B-Instruct posts the best numbers among open-source models on EvalPlus, LiveCodeBench, and BigCodeBench. The Qwen team's own technical report claims a 3.7% state-of-the-art improvement over prior open-source coders, and on EvalPlus it edges out DeepSeek-Coder-V2-Instruct.
Independent evaluations back this up. On Paul Gauthier's Aider code-editing benchmark, the model landed in surprising company: 84% for Claude 3.5 Sonnet, 75% for Claude 3.5 Haiku, 74% for Qwen2.5 Coder 32B, 71% for GPT-4o, 69% for Qwen2.5 Coder 14B, and 58% for Qwen2.5 Coder 7B on the whole-edit task. Beating GPT-4o on a real-world editing task is something open-weight models have not managed cleanly before.
On multi-language code repair, Qwen2.5-Coder-32B-Instruct scored 75.2 on MdEval, ranking first among all open-source models. Repair is a better proxy for day-to-day developer work than one-shot generation from a clean prompt, which makes that number more interesting than it looks.