
Alibaba's Qwen3-4B-Base Beats Last Year's 7B Models on Half of Benchmarks
Alibaba's compact 4B base model punches at 7B weight, pretrained on 36T tokens across 119 languages under Apache 2.0.
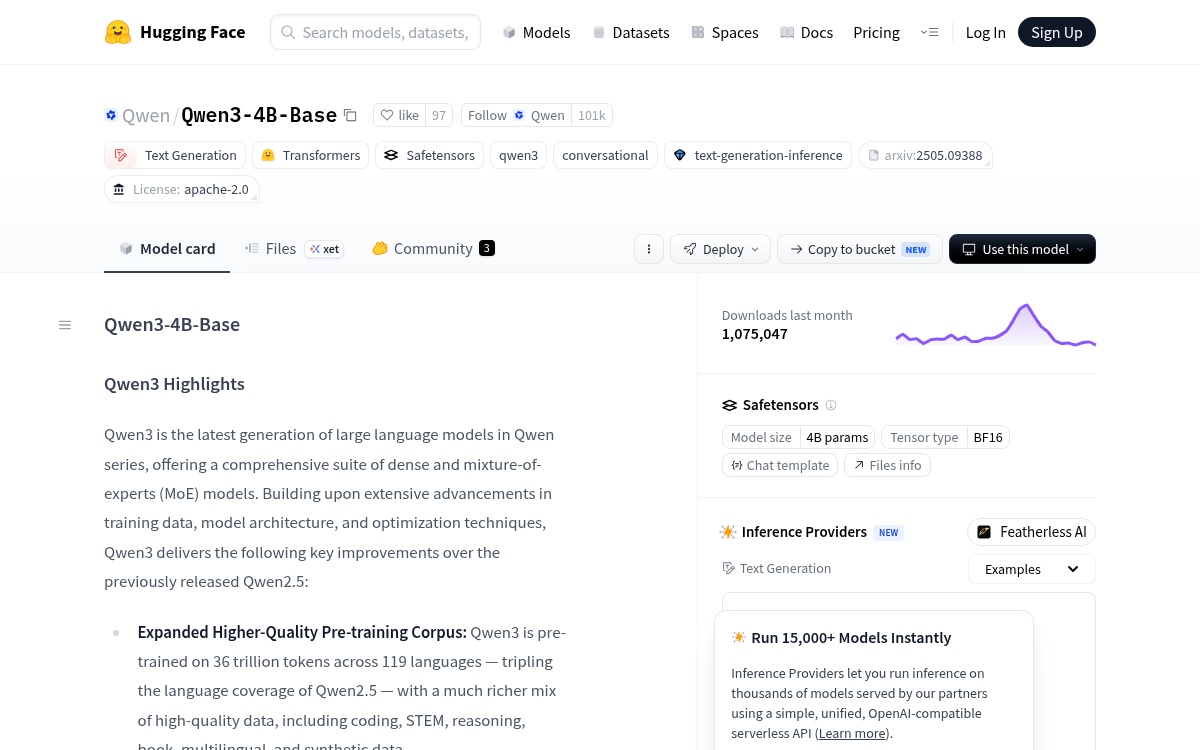
Takeaways
- Qwen3-4B-Base is a dense 4B parameter causal LM released by Alibaba under Apache 2.0 on Hugging Face
- Pretrained on 36T tokens across 119 languages using a three-stage pipeline ending at 32k context
- Architecture: 36 layers, grouped-query attention with 32Q / 8KV heads, SwiGLU, QK-layernorm
- Matches Qwen2.5-7B-Base performance while running at 4B parameters, per the Qwen3 technical report
- Base checkpoint only, no instruction following or thinking-mode toggles included
- Over 1M downloads, 400+ community fine-tunes, and quantizations for llama.cpp, Ollama, LM Studio
Alibaba's Qwen team quietly dropped a base model that has crossed a million downloads and is rewriting expectations for what a 4B parameter dense transformer can do. Qwen3-4B-Base is the raw, pre-instruction-tuning checkpoint from the Qwen3 family, released under Apache 2.0 and now sitting behind hundreds of downstream fine-tunes on Hugging Face.
The chat-tuned Qwen3-4B is what you reach for if you want an assistant out of the box. This checkpoint is the foundation you want if you plan to run your own supervised fine-tuning, domain adaptation, or reinforcement learning stage. It is a causal language model still in the pretraining stage, optimized to be a starting point rather than a finished product.
The specs that matter
The architecture is deliberately conservative and easy to deploy. Qwen3-4B-Base has 4.0B parameters (3.6B non-embedding), 36 layers, grouped-query attention with 32 query heads and 8 key/value heads, and a 32,768-token context length. That GQA ratio matches the 8B sibling, which keeps the KV cache small enough to fit comfortably on a single consumer GPU.
- Dense decoder-only transformer, not a mixture-of-experts
- BF16 weights, roughly 8 GB on disk
- SwiGLU activations, RMSNorm, rotary position embeddings
- QK-layernorm added for training stability
- Apache 2.0 license, commercial use allowed
A pretraining stack that dwarfs Qwen2.5
The training recipe is where this release earns its trending status. Qwen3 is pretrained on 36 trillion tokens across 119 languages, tripling the language coverage of Qwen2.5, with a much richer mix of high-quality data including code, STEM, reasoning, books, multilingual, and synthetic sources.