
Alibaba's Qwen3-Coder Shrinks to One GPU With 1.18M Downloads Already
Alibaba's Qwen team shipped an FP8-quantized 30B Mixture-of-Experts coder that runs on a single H200, with 256K native context and agentic tool calling.
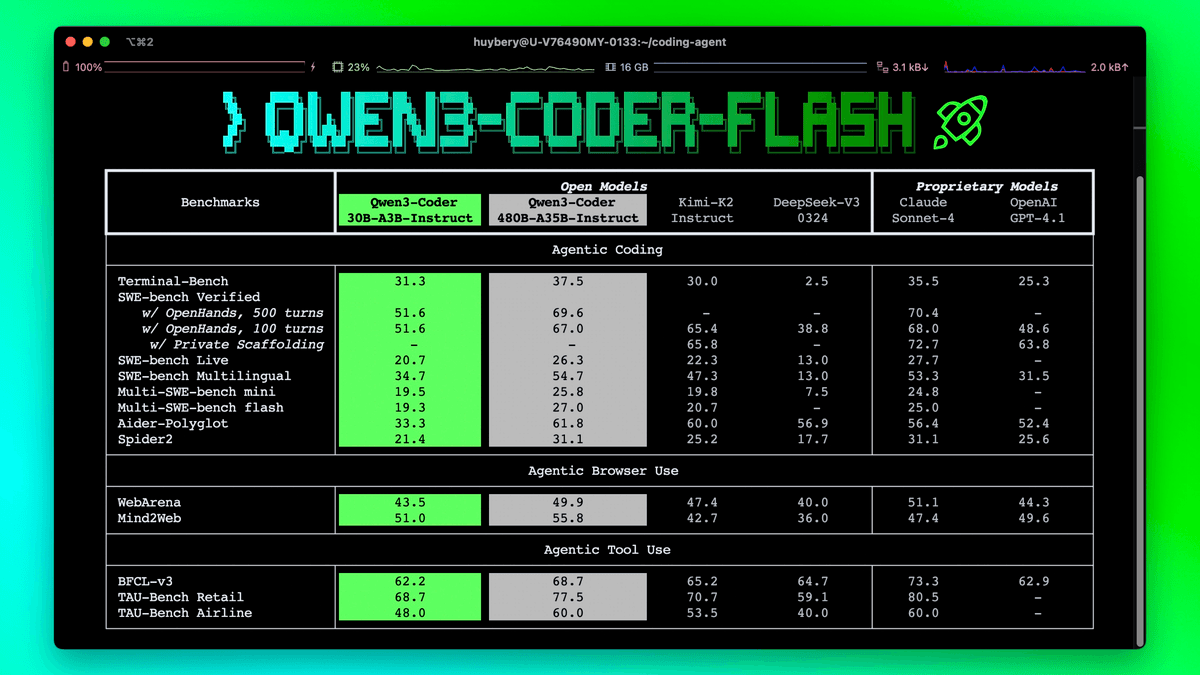
Takeaways
- Qwen released an FP8 build of Qwen3-Coder-30B-A3B, a 30.5B MoE with 3.3B active parameters.
- Native 256K context, extendable to 1M with YaRN for repository-scale code understanding.
- Fine-grained FP8 quantization at block size 128 runs on a single H200 GPU.
- Priced at $0.07/M input and $0.27/M output on OpenRouter across four providers.
- Supports Transformers, vLLM, SGLang, and Docker with OpenAI-compatible tool calling.
- Non-thinking mode only; Apache 2.0 licensed and already past 1.18M downloads.
Alibaba's Qwen team has released an FP8-quantized version of its 30B Mixture-of-Experts coding model, and it has already crossed 1.18 million downloads on Hugging Face. Qwen3-Coder-30B-A3B-Instruct-FP8 is a compressed drop-in for the flagship Qwen3-Coder-30B, tuned for agentic coding workflows like file editing, tool calling, and repository-scale reasoning, and it fits on a single high-end GPU.
What's actually in the box
The architecture is a sparse MoE with 30.5B total parameters and 3.3B activated, 48 layers, 128 experts with 8 routed per token, and 262,144 tokens of native context. Attention uses grouped-query attention with 32 query heads and 4 key/value heads. Context extends further with YaRN extrapolation, reaching up to 1M tokens for repository-scale understanding.
The FP8 variant uses fine-grained quantization with block size 128, meaning scaling factors are computed per 128-element block rather than per tensor. That preserves accuracy far better than naive FP8 while roughly halving memory versus bfloat16. One behavioral change worth flagging: the model supports only non-thinking mode and does not generate think blocks in its output, so specifying enable_thinking=False is no longer required.
Why FP8 changes the deployment math
The bfloat16 version of Qwen3-Coder-30B demands serious hardware, requiring roughly 250GB of memory or unified memory for the full weights in some configurations. The FP8 build compresses that footprint enough to run comfortably on a single H200. According to a