
Alibaba's Qwen3-Omni Beats GPT-4o on Audio While Running on One GPU
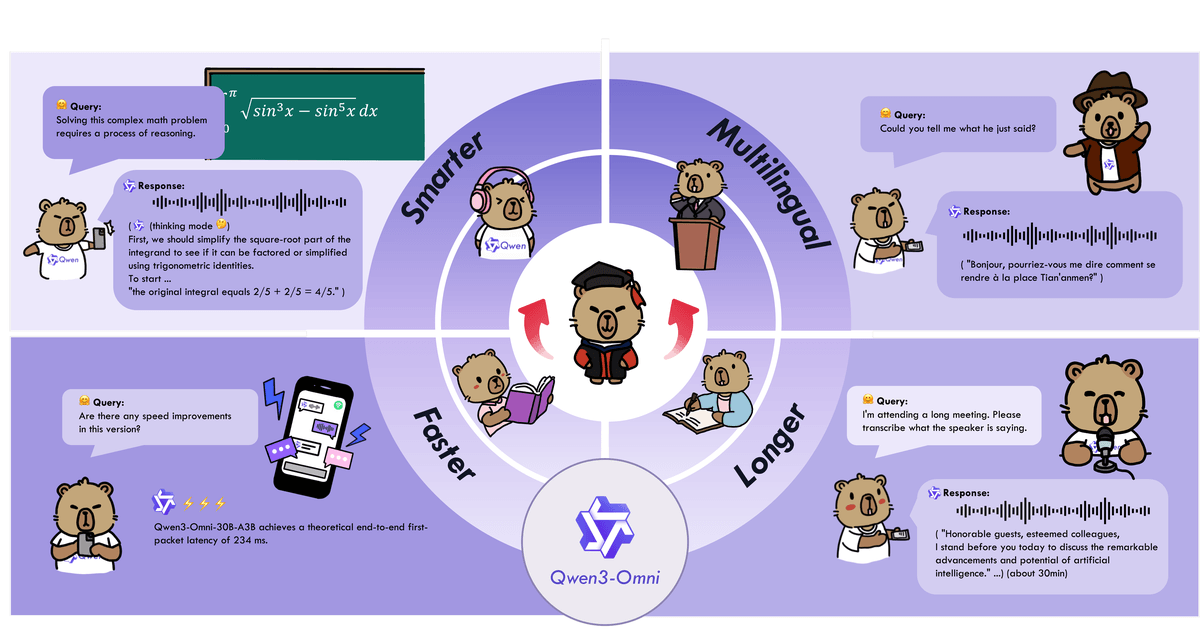
Alibaba's Qwen team dropped a natively end-to-end omni-modal MoE that handles text, image, audio, and video with 234ms speech latency.
Takeaways
- Qwen released Qwen3-Omni-30B-A3B-Instruct, an Apache 2.0 omni-modal MoE (30B total, ~3B active).
- Handles text, image, audio, video in; streams text and speech out with 234ms first-packet latency.
- Ships alongside Thinking and Captioner variants; see the technical report.
- Reaches open-source SOTA on 32 of 36 audio benchmarks, beating Gemini 2.5 Pro and GPT-4o-Transcribe.
- New AuT audio encoder trained from scratch on 20M hours replaces Whisper.
- Supports 119 text languages, 19 speech input, 10 speech output; code and cookbooks on GitHub.
Alibaba's Qwen team just shipped Qwen3-Omni-30B-A3B-Instruct, an open-weight multimodal model that ingests text, images, audio, and video and streams back both text and natural speech in real time. The headline claim is unusual: a single omni-modal system that does not regress on text or vision compared to same-size single-modality Qwen models, while topping most public audio benchmarks. It ships under Apache 2.0 with weights on Hugging Face and a full vLLM path for deployment.
What actually landed
The release is a family of three checkpoints built on the same 30B backbone, all under Apache 2.0: Qwen3-Omni-30B-A3B-Instruct, Qwen3-Omni-30B-A3B-Thinking, and Qwen3-Omni-30B-A3B-Captioner. The Instruct variant contains both the Thinker and Talker components and supports audio, video, and text input with audio and text output. The Thinking variant is text-output only but adds chain-of-thought reasoning across modalities. The Captioner is a fine-tune focused on producing detailed, low-hallucination descriptions of arbitrary audio, filling a gap in the open ecosystem.
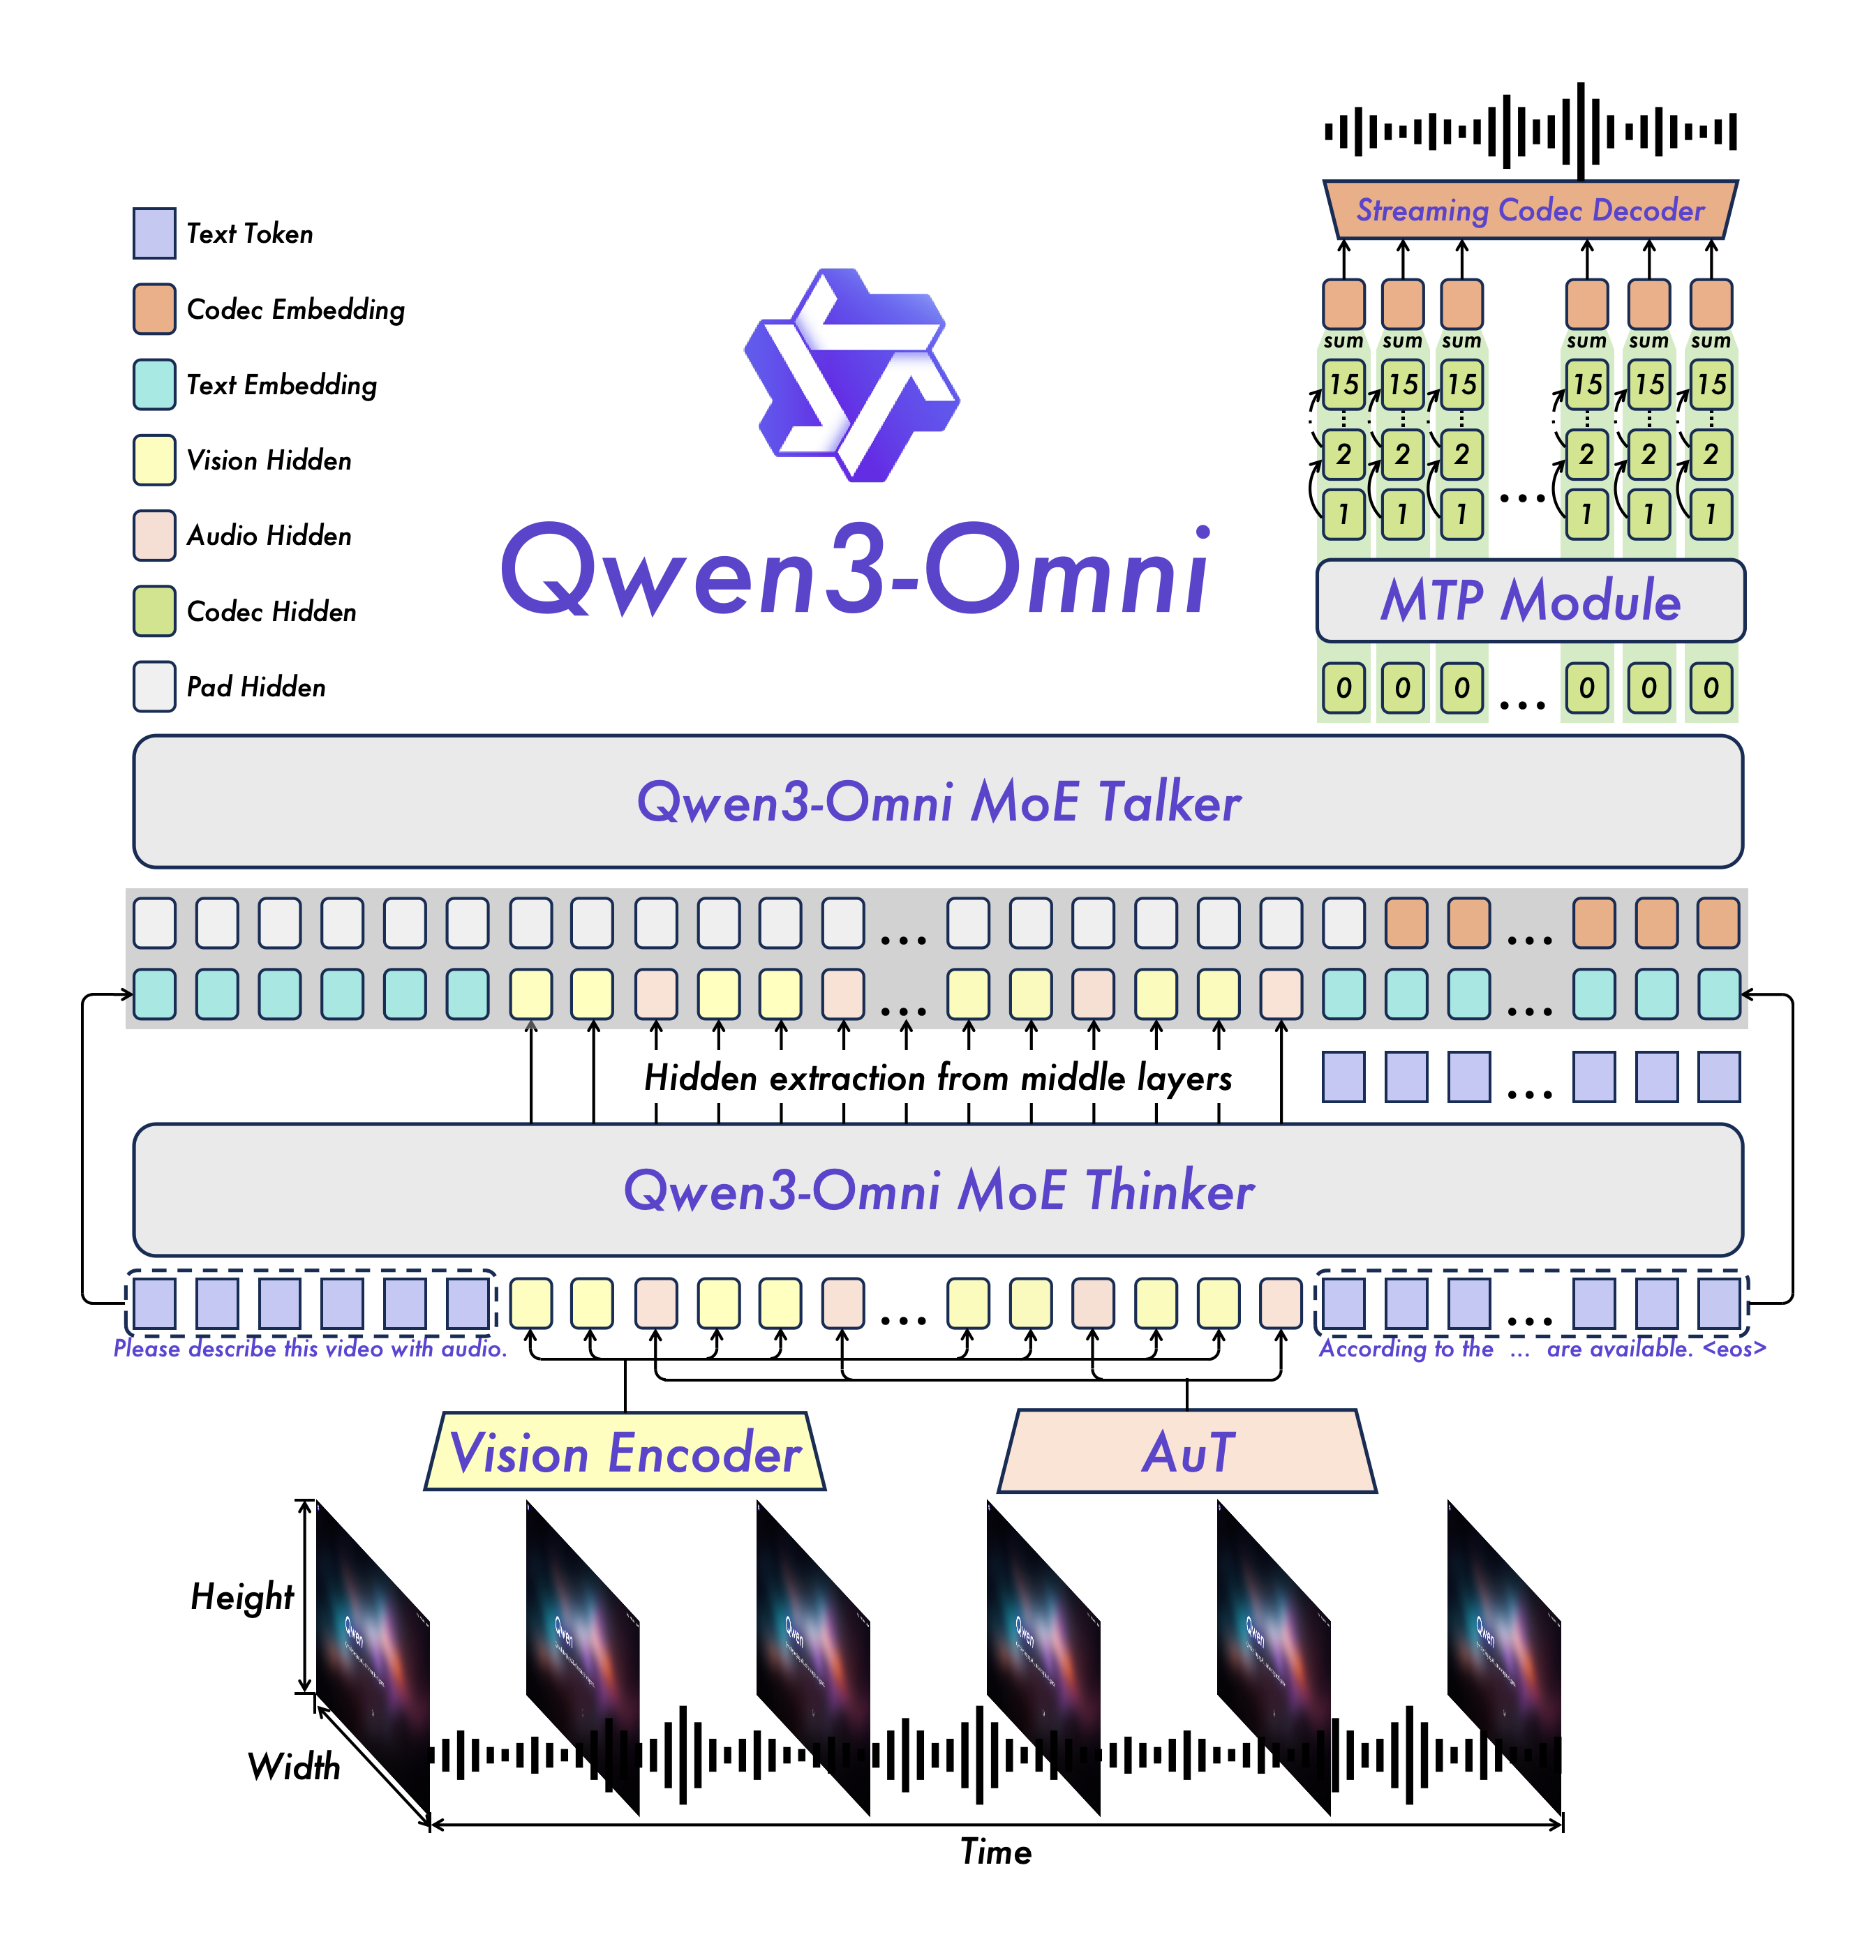
Under the hood, the backbone is a mixture-of-experts design with 30B total parameters and roughly 3B activated per forward pass, which is where the A3B suffix comes from. That activation budget is what makes running a 30B omni-model on a single high-end GPU realistic.
Inside the Thinker-Talker MoE
The architecture evolves the Thinker-Talker split introduced in Qwen2.5-Omni, but nearly every component has been swapped out. Both halves are upgraded to MoE designs, and the Whisper audio encoder is replaced with an AuT (Audio Transformer) encoder trained from scratch on 20 million hours of supervised audio, yielding stronger general-purpose audio representations.