
Black Forest Labs' FLUX.2 Klein Generates Images in Under a Second
Black Forest Labs released a 9B distilled image model that runs text-to-image and multi-reference editing in under a second on a single RTX 4090.
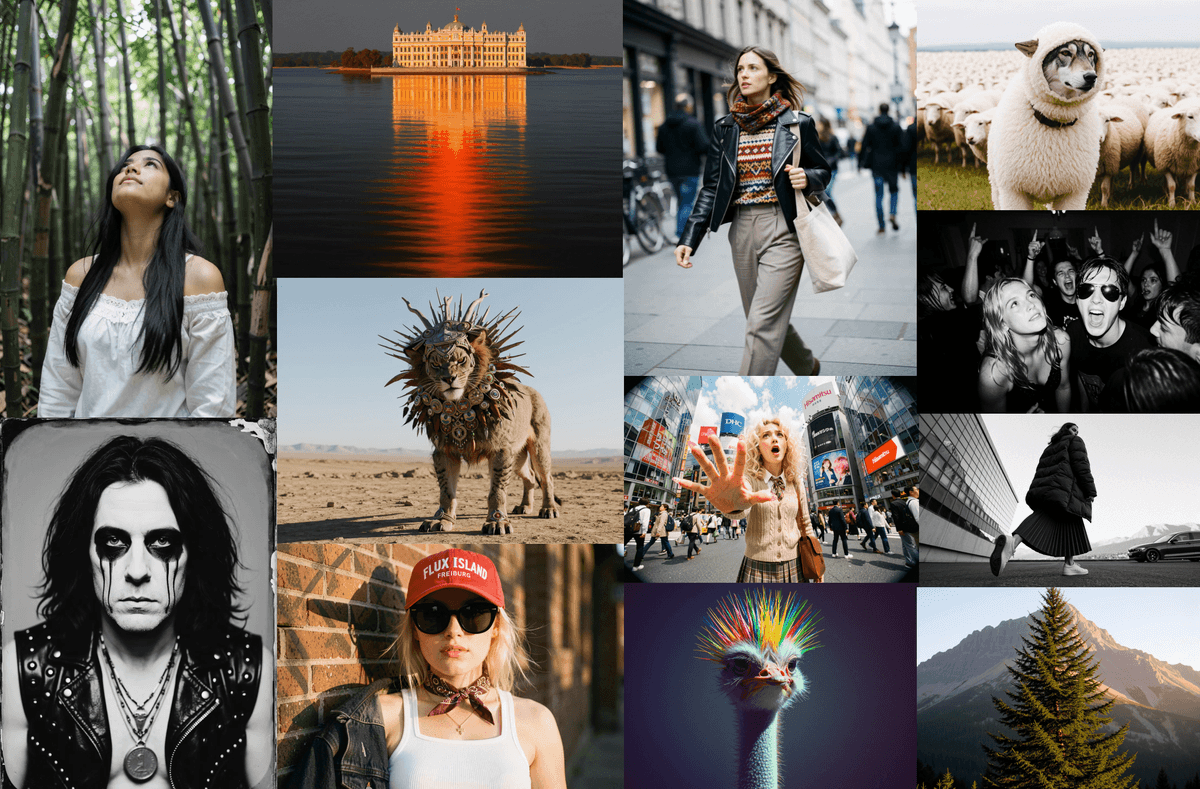
Takeaways
- FLUX.2 klein 9B generates or edits images in under a second using only four inference steps.
- Unified architecture handles text-to-image, single-reference editing, and multi-reference generation in one pipeline.
- 9B backbone paired with 8B Qwen3 text encoder, step-distilled from the larger FLUX.2 dev.
- Requires ~29 GB VRAM on an RTX 4090; a 4B sibling runs in 13 GB on 3090/4070.
- 4B is Apache 2.0 and commercial-safe; the 9B is under FLUX Non-Commercial License.
- FP8 and NVFP4 quantized builds cut VRAM up to 55% and run up to 2.7x faster.
Black Forest Labs just released FLUX.2 klein 9B, a compact rectified flow transformer that folds text-to-image generation and multi-reference editing into a single model finishing in roughly four sampling steps. End-to-end inference drops below a second on modern GPUs, and the smaller 4B sibling runs on consumer hardware with as little as 13GB of VRAM. The 9B variant is the flagship of the klein family, aimed at people who want the quality ceiling of the larger FLUX.2 dev without waiting a coffee break for each render.
Where klein sits in the FLUX.2 lineup
The klein family slots underneath the models Black Forest Labs shipped last quarter. The larger FLUX.2 max and pro releases from November 2025 chase the limits of photorealism and grounding, while klein targets consumer hardware and latency-critical workflows. The name comes from the German word for small, reflecting both the compact model size and the minimal latency.
Under the hood, the 9B is a distilled rectified flow transformer, meaning the diffusion trajectory has been compressed so the model reaches a clean image in far fewer denoising steps than a standard flow model. It pairs a 9B image backbone with an 8B Qwen3 text embedder and was step-distilled down to four inference steps, letting it match or exceed models roughly five times its size while finishing in under half a second on modern GPUs.
How the speed number is achieved
Distillation is the trick: a larger, more complex teacher model trains a smaller, more efficient student to approximate its outputs in fewer steps. In the reference Diffusers pipeline, guidance scale is fixed at 1.0 and num_inference_steps=4