
Daily's PhoneLLM Matches GPT Quality at 94% Lower Cost for Voice Agents
Pipecat released PhoneLLM Alpha 1, a 30B Mamba-Transformer MoE fine-tuned for voice phone agents with sub-100ms TTFT and $0.00025 per agent-minute.
Takeaways
- Pipecat released PhoneLLM Alpha 1, an open-weights 30B MoE voice-agent LLM under BSD 2-Clause.
- Fine-tuned from NVIDIA Nemotron 3 Nano 30B-A3B, hybrid Mamba-Transformer with 3.5B active parameters.
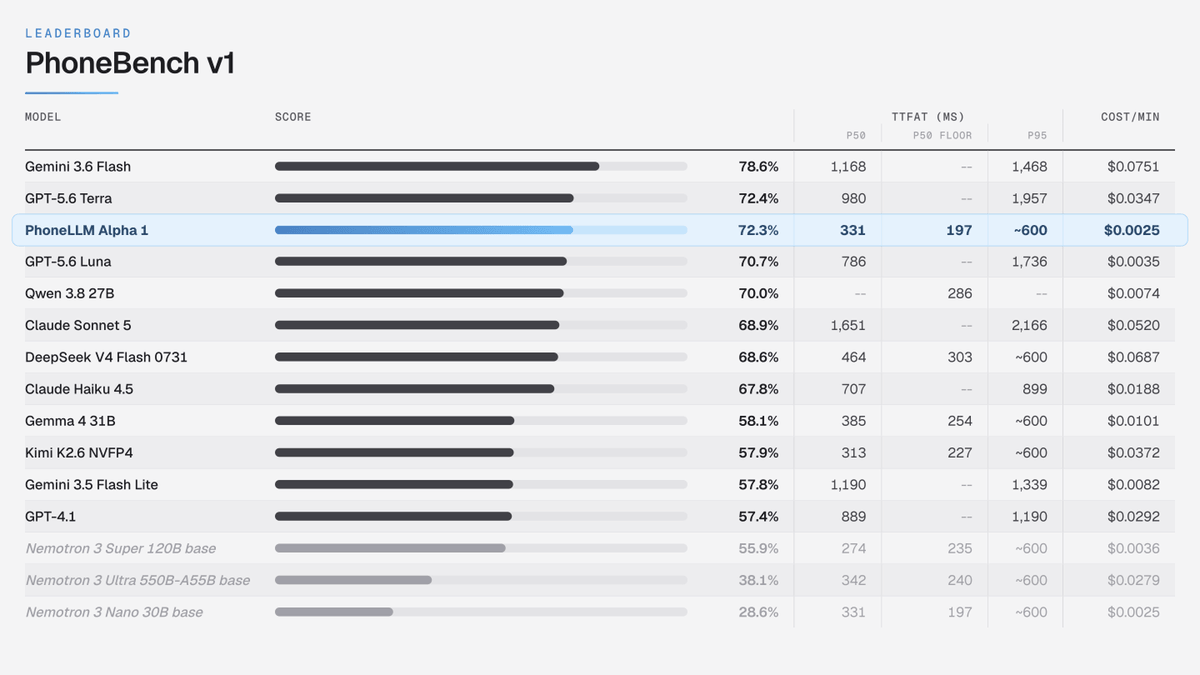
- Claimed parity with GPT 5.6 Terra at 94% lower cost and 1,300ms faster P95 TTFT.
- Single-request TTFT P95 under 100ms on one NVIDIA B200; 88 concurrent agents per node.
- Self-hosted cost lands around $0.00025 per agent-minute on Modal B200 infrastructure.
- Ships with PhoneBench v1, an LLM-judge benchmark for phone-agent quality and tool-call accuracy.
The Pipecat team at Daily has released PhoneLLM Alpha 1, an open-weights model built specifically for voice agents that answer and place phone calls. It is a full-parameter fine-tune of NVIDIA Nemotron 3 Nano 30B-A3B, released under BSD 2-Clause with no commercial restrictions, and ships alongside a new benchmark called PhoneBench v1 that grades models on real phone-call behavior.
The headline claim: PhoneLLM matches GPT 5.6 Terra in quality, at 94% lower cost and 1,300ms faster P95 time-to-first-token. For developers trying to fit a frontier model into a real-time voice loop, that gap determines whether the product works at all.
Built for the phone call's hard constraints
Voice agents live and die by latency and tool-call reliability. Frontier models are increasingly tuned for reasoning traces, which blow past the tight budget a phone call demands. The team puts total voice-to-voice latency at around 1,500ms for a call to feel natural, and that budget spans speech-to-text, the LLM, text-to-speech, and network hops combined.
The other problem is tool-call hallucination. In long multi-turn conversations, models routinely claim they booked a table or created a ticket without actually invoking the function. PhoneLLM trains specifically to call the right tool at the right time with thinking disabled, cutting reasoning delay without sacrificing reliability.
