
Datalab's Chandra OCR 2 Beats Gemini and GPT-5 Mini Across 43 Languages
Datalab's new 5B parameter OCR model hits state of the art on olmOCR, adds 90+ languages, and doubles throughput over Chandra 1.
Takeaways
- Chandra OCR 2 from Datalab scores 85.8% on olmOCR bench, state of the art among open models.
- Smaller than Chandra 1 (roughly half the parameters) with 2x throughput improvement on vLLM.
- Supports 90+ languages with 77.8% average on 43-language bench, beating Gemini 2.5 Flash and GPT-5 Mini.
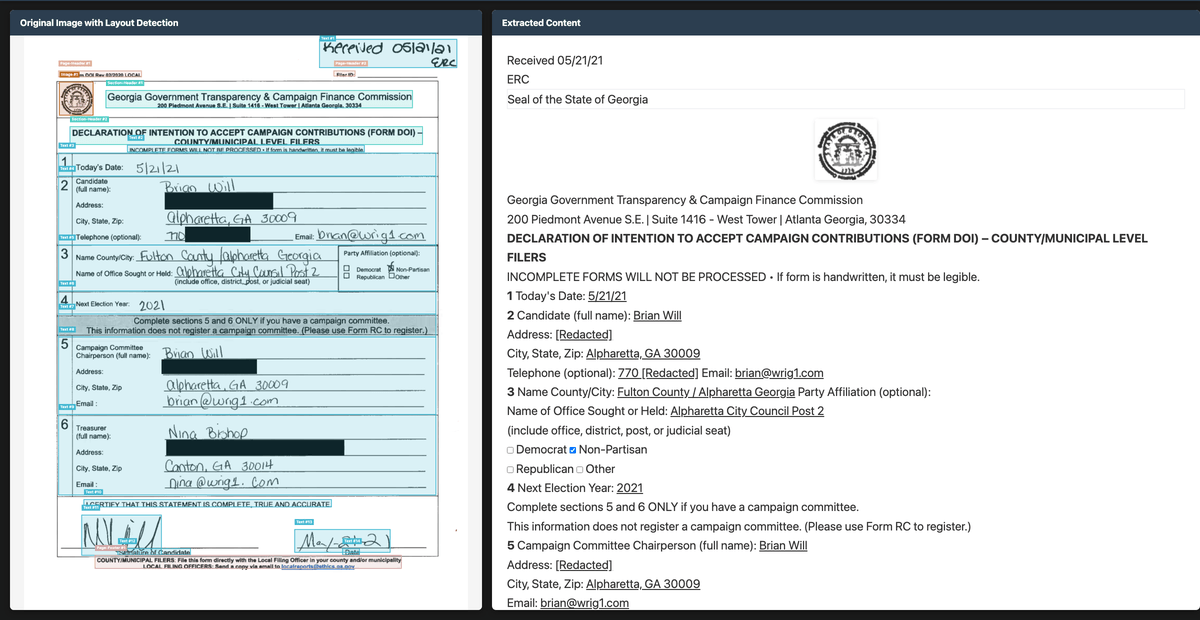
- Handles handwriting, checkboxes, complex tables, math equations, and multi-column layouts.
- Outputs structured Markdown, HTML, or JSON via chandra-ocr pip package with vLLM or Transformers.
- Apache 2.0 code, OpenRAIL-M weights free for research and startups under $2M funding.
Datalab has released Chandra OCR 2, an open-weights document reader built on Qwen 3.5 that ingests PDFs and images and returns clean Markdown, HTML, or JSON with layout intact. It now leads the olmOCR benchmark while shrinking from Chandra 1's 9B parameters down to a 4B checkpoint that runs faster on a single GPU.
What actually changed
The model card lists concrete jumps over version 1 rather than vague quality claims. Chandra 2 scores 85.9% on the olmOCR benchmark and 77.8% on an internal 43-language multilingual test, beating its predecessor across every category with 2x the throughput. The largest gains show up in South Asian scripts (Bengali +27.2, Kannada +42.6, Malayalam +46.2, Tamil +26.9, Telugu +39.1), where most systems, including Gemini and GPT-5 Mini, still fall over.
Beyond the benchmarks, the release focuses on things that break real document pipelines:
- Handwriting and cursive, including handwritten math