
Jonatas Grosman's Greek Speech Model Hits 2.6M Downloads on Hugging Face
A community-fine-tuned Greek speech recognition model built on Facebook's XLSR-53 has crossed 2.6 million downloads, becoming a default choice for Greek ASR.
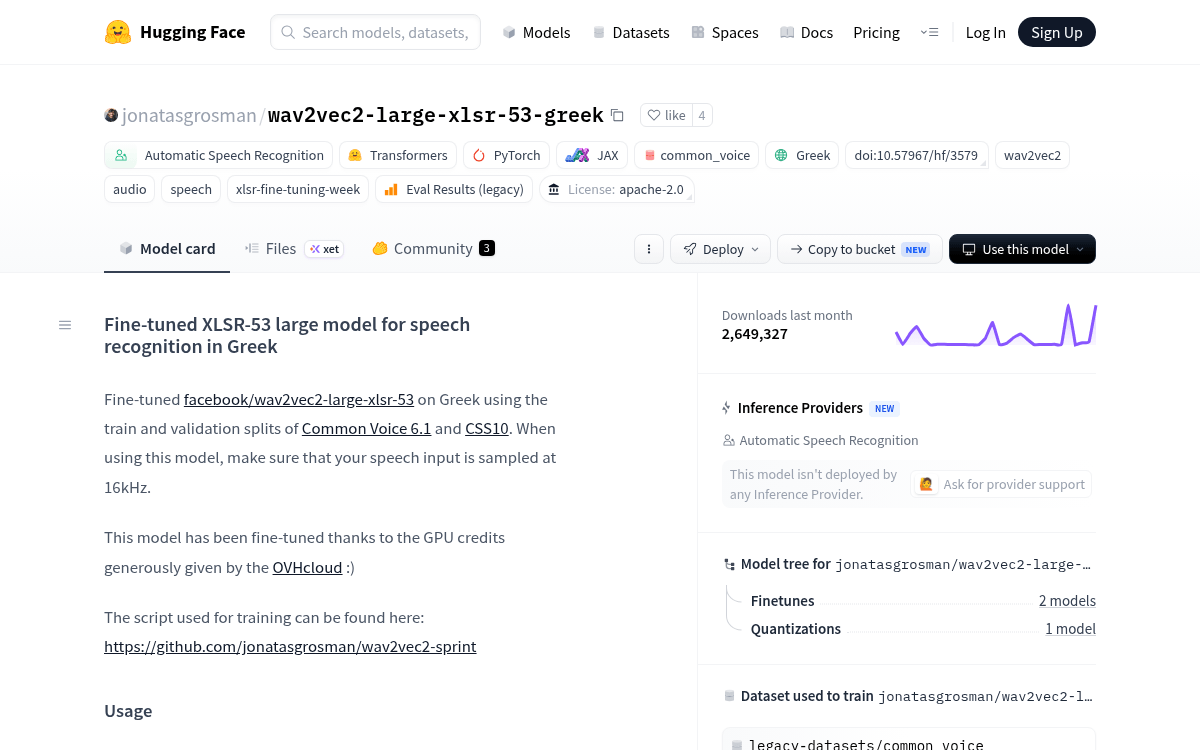
Takeaways
- Community fine-tune of Facebook's XLSR-53 for Greek ASR, Apache 2.0 licensed
- Reports 11.62% WER and 3.36% CER on Common Voice Greek test set
- Backbone pretrained on 56,000 hours across 53 languages with 24 transformer layers
- Trained on Common Voice 6.1 plus CSS10, requires 16kHz audio input
- Over 2.6 million downloads, integrates with Transformers pipeline and HuggingSound
- Best fit for lightweight, self-hosted Greek transcription and further domain fine-tuning
Greek automatic speech recognition has always been a bit of a desert compared to English or Mandarin, which is why a community model built on top of Facebook's multilingual wav2vec 2.0 backbone has become one of the most-downloaded audio models on Hugging Face. Jonatas Grosman's wav2vec2-large-xlsr-53-greek has crossed 2.6 million downloads and 3,400 likes, quietly becoming a default building block for anyone shipping Greek voice features.
The recipe is straightforward. Grosman fine-tuned facebook/wav2vec2-large-xlsr-53 on Greek using the train and validation splits of Common Voice 6.1 and CSS10, distributed under Apache 2.0. It runs on PyTorch and JAX, and the author warns that speech input must be sampled at 16kHz, which is the single most common footgun when plugging it into a pipeline.
The backbone doing the heavy lifting
XLSR-53 is where the interesting engineering lives. Wav2Vec2-large-xlsr-53 is a multilingual extension of Wav2Vec2 with 24 Transformer layers and a hidden size of 1024, pretrained on roughly 56,000 hours of unlabeled speech covering 53 languages. The pretraining objective learns to fill in masked chunks of raw audio while sharing a discrete codebook of sound units across languages, which is why fine-tuning on a mid-resource language like Greek works so well with relatively little labeled data.