
Meta's w2v-BERT 2.0 Quietly Beats Whisper Across 143 Languages
Meta's Conformer speech encoder trained on 4.5M hours of audio across 143 languages has become the go-to backbone for multilingual ASR fine-tuning.
Takeaways
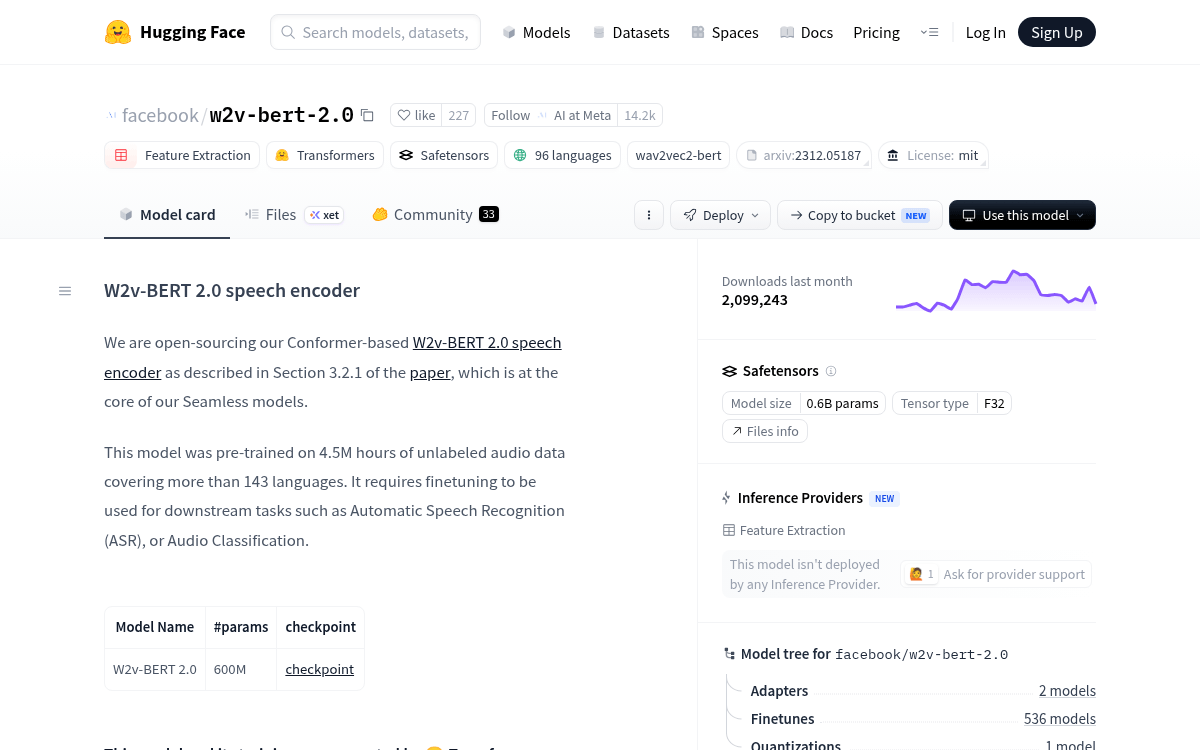
- Meta's w2v-BERT 2.0 is a 600M-parameter Conformer speech encoder covering 143 languages.
- Pretrained on 4.5M hours of unlabeled audio, up from 1M hours in the previous version.
- Serves as the core speech encoder inside SeamlessM4T v2 translation models.
- Ships as a bare checkpoint with no ASR head, requiring fine-tuning for downstream tasks.
- Available under MIT license via Hugging Face Transformers with over 2M downloads.
- Preferred backbone for low-resource ASR, speaker verification, and multilingual audio embeddings.
Meta's w2v-BERT 2.0 has quietly become one of the most widely used building blocks for multilingual speech systems on Hugging Face, with over 2 million downloads and more than 500 community fine-tunes built on top of it. The same speech encoder sits at the heart of Meta's SeamlessM4T v2 translation stack, released as a standalone checkpoint under an MIT license so anyone can drop it into their own audio pipelines.
A speech backbone with an unusually big appetite
w2v-BERT 2.0 is a Conformer-based encoder that serves as the core acoustic component of Meta's Seamless Communication system. The scale of its pretraining is what sets it apart: 24 Conformer layers combining contrastive learning with masked language modeling, trained on 4.5 million hours of unlabeled audio spanning 143 languages.
That is a 4.5x jump over the original w2v-BERT, which saw roughly 1 million hours. Meta also simplified the recipe by dropping the random-projection quantizer (RPQ) and its associated loss that appeared in SeamlessM4T v1.
What you actually get in the checkpoint
The release is deliberately minimal: a bare 600M parameter encoder with no task head, outputting raw audio embeddings rather than transcripts. Once fine-tuned with a CTC head, Wav2Vec2-BERT predicts text tokens in a single pass, making it considerably faster than Whisper at inference. It ships in Hugging Face Transformers and can be adapted to any low-resource ASR task with a custom token list.