
Mistral AI Quietly Refreshes Mistral-7B-Instruct With Modern Serving Tools
Mistral's original 7B instruct model gets a fresh model card with mistral-common tokenizer support and one-command deployment via vLLM, SGLang, and Docker.
Takeaways
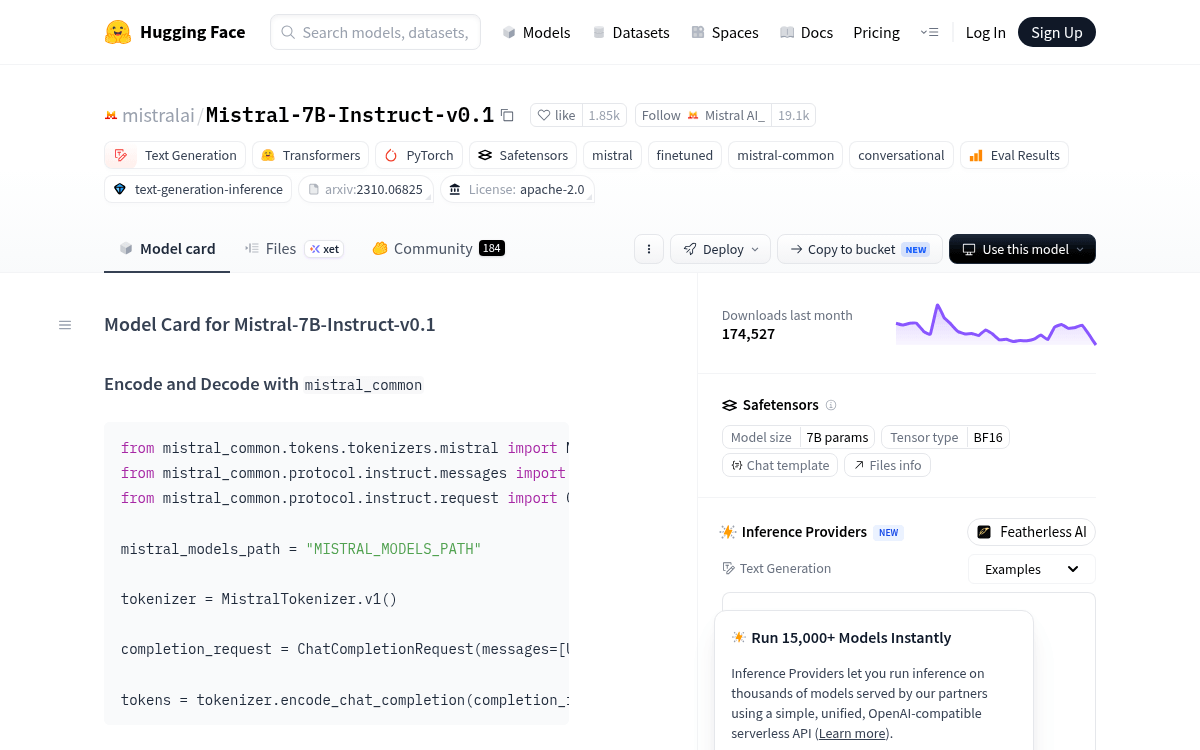
- Mistral-7B-Instruct-v0.1 model card refreshed with mistral-common tokenizer support and new deployment recipes.
- One-line serving now documented for vLLM, SGLang, and Docker Model Runner with OpenAI-compatible endpoints.
- Weights unchanged: still a 7.3B Apache-2.0 model using grouped-query and sliding-window attention.
- Prompt format remains
[INST]...[/INST], with 8k context and no built-in function calling. - Still one of the most-downloaded Mistral models, with 947+ community finetunes built on its base.
- MMLU-Pro of 25.75 shows its age; consider v0.3 or Mistral Small 3.1 for new projects.
Nearly two years after its original release, Mistral AI's first instruction-tuned model, Mistral-7B-Instruct-v0.1, has quietly received a refresh on Hugging Face. The updated model card ships new deployment recipes, first-class support for the mistral-common tokenizer library, and one-line serving via vLLM, SGLang, and Docker Model Runner. The weights are unchanged, but the surrounding tooling is now aligned with how the rest of Mistral's current lineup is packaged.
What actually changed under the hood
The checkpoint itself is the same 7.3B-parameter instruction-tuned model that Mistral released alongside the original Mistral 7B paper, fine-tuned from Mistral-7B-v0.1 on a mix of publicly available conversation datasets. The architecture still relies on grouped-query attention and its close cousin multi-query attention, plus sliding-window attention and a byte-fallback BPE tokenizer.
The refreshed card now documents:
- A
mistral-commonencode/decode path usingMistralTokenizer.v1(), which Mistral treats as the reference tokenizer implementation. - A vLLM serve command with
--tokenizer_mode mistral --config_format mistral --load_format mistraland auto tool-choice enabled.