
Mistral's Mixtral-8x22B Delivers 141B Open-Weight Power at 70B Speed
Mistral's sparse Mixture-of-Experts flagship packs 141B parameters but activates only 39B per token, with native function calling and Apache 2.0 licensing.
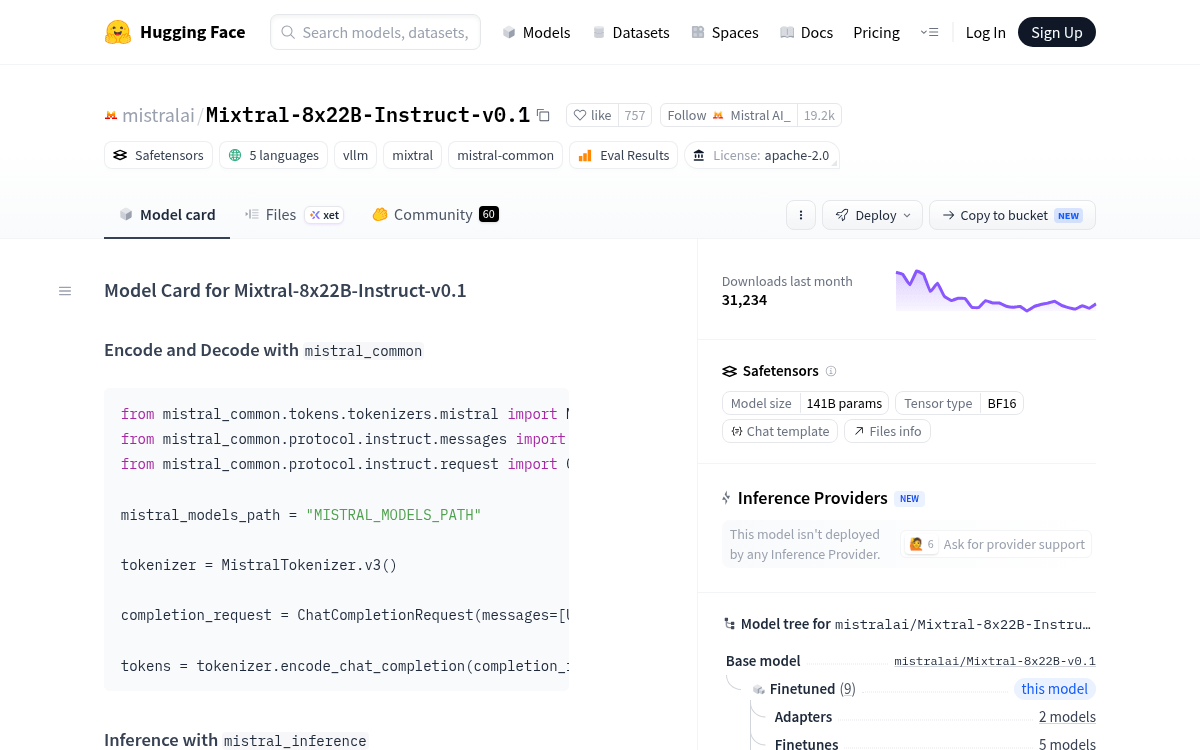
Takeaways
- Mistral's Mixtral-8x22B-Instruct-v0.1 ships 141B total parameters, 39B active per token.
- Sparse MoE with 8 experts per layer, top-2 routing across 56 layers.
- Context window of 65,536 tokens with native function calling support.
- Scores 90.8% GSM8K, 44.6% MATH, 56.33 on MMLU-Pro leaderboard.
- Apache 2.0 license permits full commercial use and self-hosting.
- Multilingual across English, French, Italian, German, and Spanish.
Mistral's Mixtral-8x22B-Instruct-v0.1 is an instruction-tuned checkpoint built on the company's largest open-weight base model. With 141B total parameters, an Apache 2.0 license, and native function calling, it gives teams a permissively licensed sparse MoE model that competes with dense 70B systems on inference speed while carrying a much larger total parameter budget.
Sparse Mixture-of-Experts routes each token through only a subset of parameters per forward pass, so compute costs scale with active parameters rather than total ones. Here, 39B of the 141B parameters fire on any given pass, which is where the speed advantage over comparably capable dense models comes from. The catch is memory: all 141B parameters still need to live somewhere, even when most are idle.
Architecture details
The model runs 56 layers with 8 experts per layer and a top-k of 2, meaning the router selects two experts per token at each layer. The context window sits at 65,536 tokens. Supported languages are English, French, Italian, German, and Spanish.
Full BF16 inference requires a multi-GPU setup, typically two to four H100s, or aggressive 4-bit quantization on a single node. Community quantizations and fine-tuned adapters are already available on the Hub for teams working with tighter hardware budgets.