
Mistral's Voxtral Mini Beats Closed APIs With Sub-500ms Open Streaming Speech
Mistral open sourced a 4B streaming speech recognition model that hits sub-500ms latency across 13 languages, matching offline systems at 480ms delay.
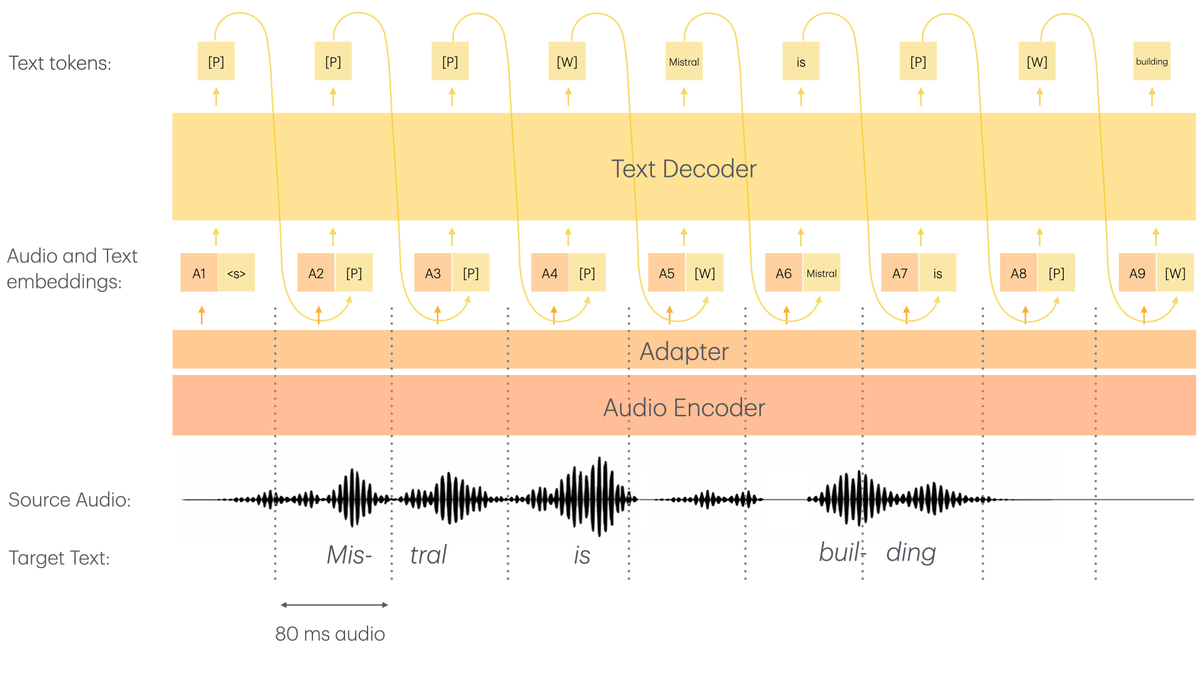
Takeaways
- Mistral released Voxtral Mini 4B Realtime, an open Apache 2.0 streaming ASR model.
- Sub-500ms latency across 13 languages, matching offline systems at 480ms delay.
- Configurable transcription delay from 80ms to 2400ms trades latency for accuracy.
- Runs on a single 16GB GPU in BF16, with day-one vLLM realtime API support.
- Architecture pairs a 3.4B LLM (Ministral 3B) with a 970M causal audio encoder.
- Hosted API priced at $0.006 per minute; community ports for MLX, Rust, C.
Mistral has released Voxtral Mini 4B Realtime, a streaming speech-to-text model that lands in a spot most open source ASR has struggled to reach: real-time latency without the usual accuracy tax. It handles streaming ASR with sub-500ms latency and multilingual transcription across 13 languages, ships under Apache 2.0, and lands with production integration in vLLM on day one.
You get open weights small enough to run on a single 16GB GPU, a configurable latency knob, and word error rates that trade blows with offline systems. That combination has historically meant paying per minute for a closed API.
Streaming as a first-class citizen
Voxtral Realtime is built from two pieces: a roughly 3.4B parameter language model (finetuned from Ministral 3B) and a 970M parameter audio encoder. The key detail is that the audio encoder was trained from scratch with causal attention, so it only looks at past audio frames rather than the full clip. Both the encoder and the LLM backbone use sliding window attention, which lets the model handle arbitrarily long streams without memory blowing up.
Most open source ASR (Whisper being the obvious example) is fundamentally an offline architecture. It expects a chunk of audio, runs bidirectional attention over it, and returns text. Streaming implementations bolt chunking and VAD on top, which introduces stutter and forces you to trade chunk size against accuracy. Voxtral treats streaming as the primary case.