
Norway's AI Lab Beats Whisper on Nynorsk With 1B Open Model
A 1-billion-parameter wav2vec2 model fine-tuned for Norwegian Nynorsk speech recognition has quietly crossed 1.1M downloads on Hugging Face.
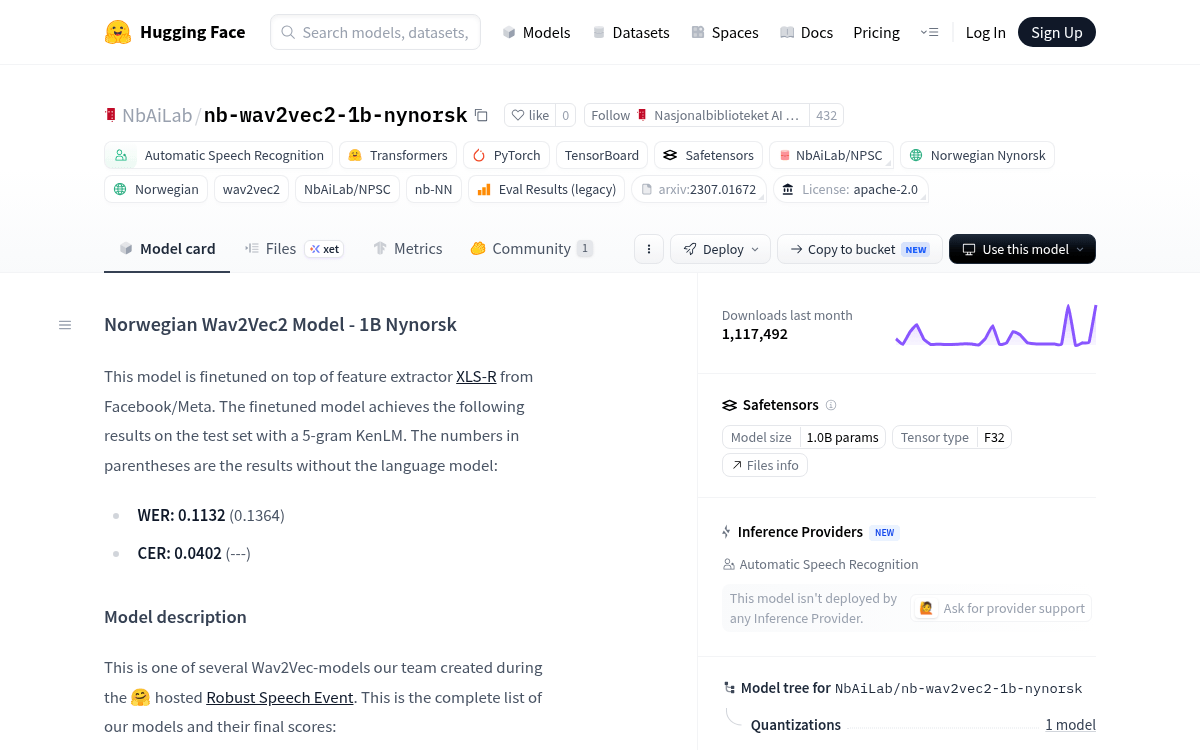
Takeaways
- NbAiLab's nb-wav2vec2-1b-nynorsk has crossed 1.1M downloads on Hugging Face.
- 1B-parameter wav2vec2 model fine-tuned from Meta's XLS-R for Norwegian Nynorsk ASR.
- Reports 11.32% WER with a 5-gram KenLM, 13.64% without, on NPSC test.
- Trained on the Norwegian Parliamentary Speech Corpus, released as Apache 2.0.
- Methodology published in Boosting Norwegian ASR (NoDaLiDa 2023).
- Drop-in replacement via Hugging Face pipeline; strongest on clean, formal speech.
Norwegian is written in two standards, Bokmål and Nynorsk, and the smaller of the two has long been a blind spot for speech recognition. A model from the National Library of Norway's AI Lab is filling that gap at scale, having pulled in over 1.1 million downloads on Hugging Face while flying under the radar of the English-speaking ML crowd.
nb-wav2vec2-1b-nynorsk is a 1-billion-parameter automatic speech recognition system that transcribes spoken Nynorsk into text. It ships under Apache 2.0, weighs roughly 11.7 GB on disk, and plugs straight into the standard Hugging Face Transformers pipeline.
The numbers behind the model
The checkpoint is fine-tuned on top of the XLS-R feature extractor from Facebook/Meta, then paired with a 5-gram KenLM language model at decode time. Reported evaluation metrics on the Norwegian Parliamentary Speech Corpus (NPSC) test set:
- WER with 5-gram LM: 11.32%
- WER without LM: 13.64%
- CER with LM: 4.02%
For context on where this sits in the family, the team also shipped a Bokmål sibling. The 1B Bokmål version reports WER of 6.33% with the 5-gram KenLM and 7.38% without. Nynorsk is harder because less training data is available for it, which is exactly why an open, purpose-built model matters.