
Unsloth Makes DeepSeek-V4-Flash Finally Runnable Locally on 160 GB
Unsloth ships lossless GGUF builds of DeepSeek-V4-Flash, making the 284B MoE model locally runnable on 110GB RAM after a critical llama.cpp fix landed July 7th.
Takeaways
- Unsloth released production-ready GGUF builds of DeepSeek-V4-Flash, the 284B/13B-active MoE model, following a critical llama.cpp multi-turn fix on July 7th.
- Lossless quantization: Unsloth's UD-Q8_K_XL is bit-identical to official weights; other community GGUFs re-quantize already-FP4 experts, introducing 5–30% weight error.
- Hardware requirements: 3-bit quant (103 GB) runs on 110 GB RAM; lossless 8-bit needs 169 GB — fits a 2×H100 or large Mac.
- Strong benchmarks: V4-Flash scores 79% SWE-bench Verified, 88.1% GPQA Diamond, and 91.6% LiveCodeBench in Think Max mode.
- Extremely cheap via API: $0.14/$0.28 per million input/output tokens — roughly 1% of Claude Opus 4.7's output price, with 10x cache-hit discounts for agentic loops.
- Migration deadline: Legacy
deepseek-chatanddeepseek-reasonerendpoints retire July 24, 2026 — migrate to deepseek-v4-flash now.
DeepSeek's V4 family arrived in April with a genuinely new architecture, and the smaller of its two models, DeepSeek-V4-Flash, has been one of the most-watched open-weight releases of 2026. Now, Unsloth has published a properly quantized GGUF version that finally makes local inference practical, following a key llama.cpp bug fix that landed on July 7th.
What got released, and why it took a while
DeepSeek-V4-Flash is a Mixture-of-Experts model with 284B total parameters and only 13B activated per token, supporting a context length of one million tokens. The open weights dropped under the MIT license, but running them locally was a mess for months. llama.cpp added DeepSeek V4 support, but multi-turn conversations would not function well when using KV cache quantization , it has since been fixed and merged in llama.cpp since July 7th, 2026. Before that fix, the model would produce garbled output mid-conversation.
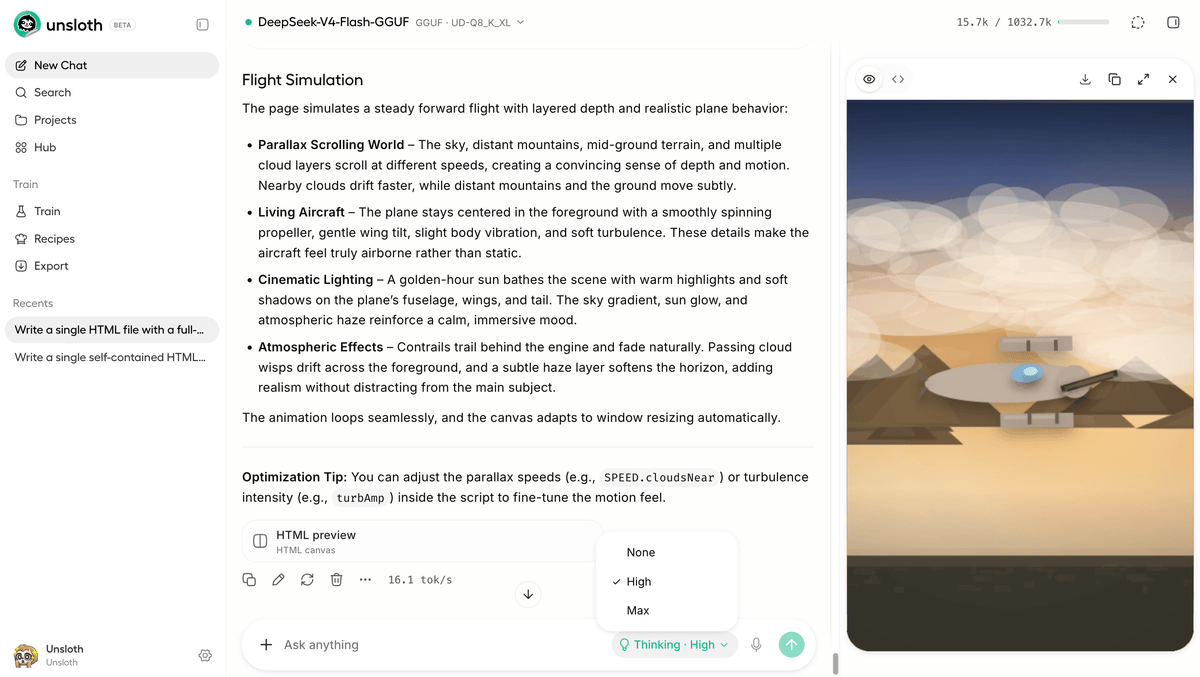
You can now run DeepSeek-V4-Flash in Unsloth Studio with toggles for High and Max thinking. The unsloth/DeepSeek-V4-Flash-GGUF repo is the first set of GGUF builds that Unsloth considers production-ready for this model.
The quantization problem is unusual here
V4-Flash is not a standard BF16 model that you compress down. DeepSeek-V4-Flash is quantization-aware-trained: the official checkpoint stores its routed experts , 96% of the model , natively in MXFP4, and everything else in FP8 or BF16. GGUF's MXFP4 is exactly that format, so Unsloth repacks the experts bit-for-bit, and FP8 dequantizes into BF16 with no rounding.
This matters because other GGUF conversions got it wrong. Unsloth checked every tensor against the official DeepSeek weights: all 1,328 are bit-identical, and it stays lossless at inference with KL-divergence ~0 and 100% top-token agreement. Non-Unsloth DeepSeek-V4-Flash GGUFs were converted without these paths, thus deviating from the official weights. The practical consequence: other community GGUFs re-quantize the already-FP4 experts to Q4_K or IQ2_XXS, introducing 5–30% weight error per layer. Unsloth's builds keep those expert weights untouched.