
Unsloth Packs OpenAI's gpt-oss-20b Into a 16 GB Local Reasoning Model
Unsloth's GGUF pack of OpenAI's gpt-oss-20b runs on 16GB of memory across llama.cpp, Ollama, LM Studio, and vLLM with Apache 2.0 licensing.
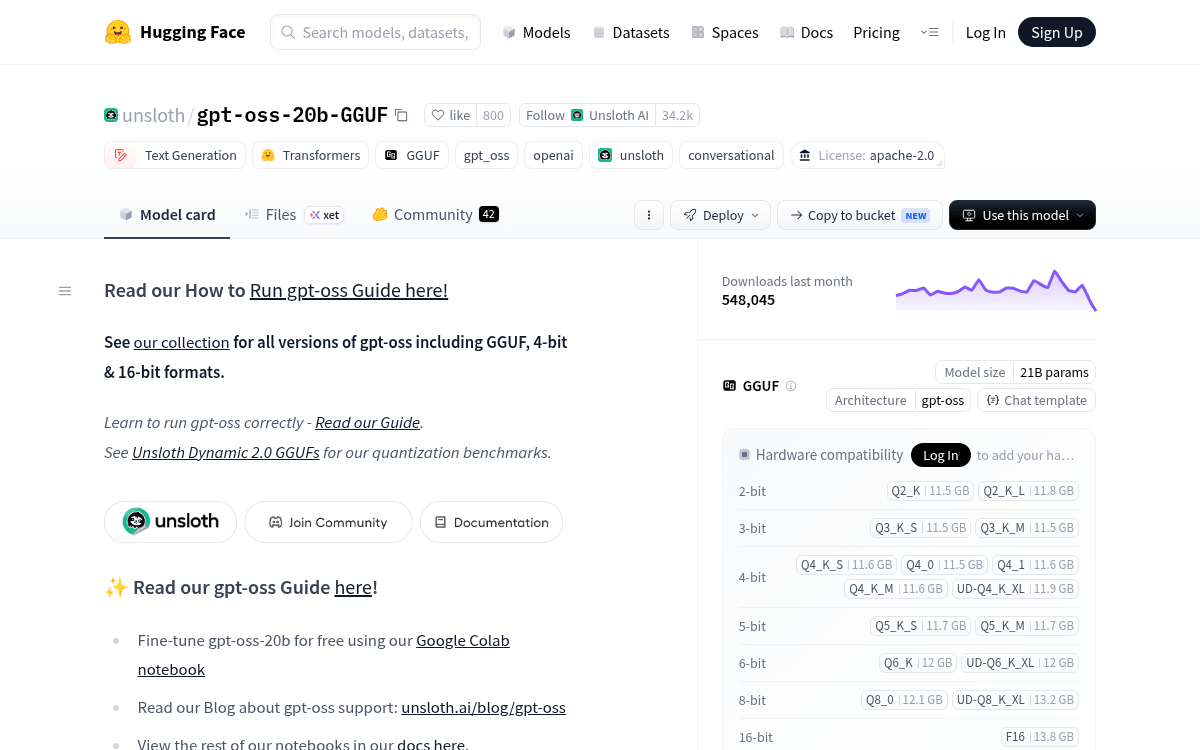
Takeaways
- Unsloth published GGUF quantizations of OpenAI's gpt-oss-20b, from Q2 to F16.
- Runs within 16GB memory thanks to native MXFP4 precision in the MoE layers.
- 21B total parameters, 3.6B active, trained on OpenAI's Harmony response format.
- One-line install for llama.cpp, Ollama, LM Studio, Jan, vLLM, and SGLang.
- Apache 2.0 license with configurable low, medium, or high reasoning effort.
- Fine-tunable on consumer GPUs via Unsloth's free Colab notebook.
Unsloth has published a full set of GGUF quantizations of gpt-oss-20b, OpenAI's open-weight reasoning model, covering everything from a 2-bit build at 11.5 GB to a full F16 build at 13.8 GB, with over half a million downloads on Hugging Face. The pack plugs directly into llama.cpp, Ollama, LM Studio, Jan, vLLM, and SGLang, giving you an OpenAI-compatible local server with a single command.
A mixture-of-experts that fits in 16 GB
gpt-oss-20b is a 21B-parameter mixture-of-experts model with 3.6B active parameters, trained on the OpenAI Harmony response format. Its MoE layer uses native MXFP4 precision, which is what lets the larger gpt-oss-120b run on a single H100 and keeps the 20B variant within 16 GB of memory. That puts it within reach of a consumer GPU or a modern Mac without any heroic engineering.
Unsloth's contribution is packaging that model into GGUF across a wide precision ladder. The F16 quant upcasts every layer from MXFP4 to BF16 and leaves them unquantized, so you can stay faithful to OpenAI's original weights or trade accuracy for a smaller footprint.