
Unsloth Shrinks Z.ai's 754B GLM-5.1 Coding Giant to Fit on a Mac
Unsloth ships day zero GGUF quants of Z.ai's 754B agentic coding model, shrinking it from 1.65TB down to 200GB so it can run on a single high-memory workstation.
Takeaways
- Unsloth released GLM-5.1-GGUF, day-zero Dynamic 2.0 quants of Z.ai's 754B agentic coding model
- Compression shrinks the model from 1.65TB to 220GB (2-bit) or 200GB (1-bit), an 80-85% reduction
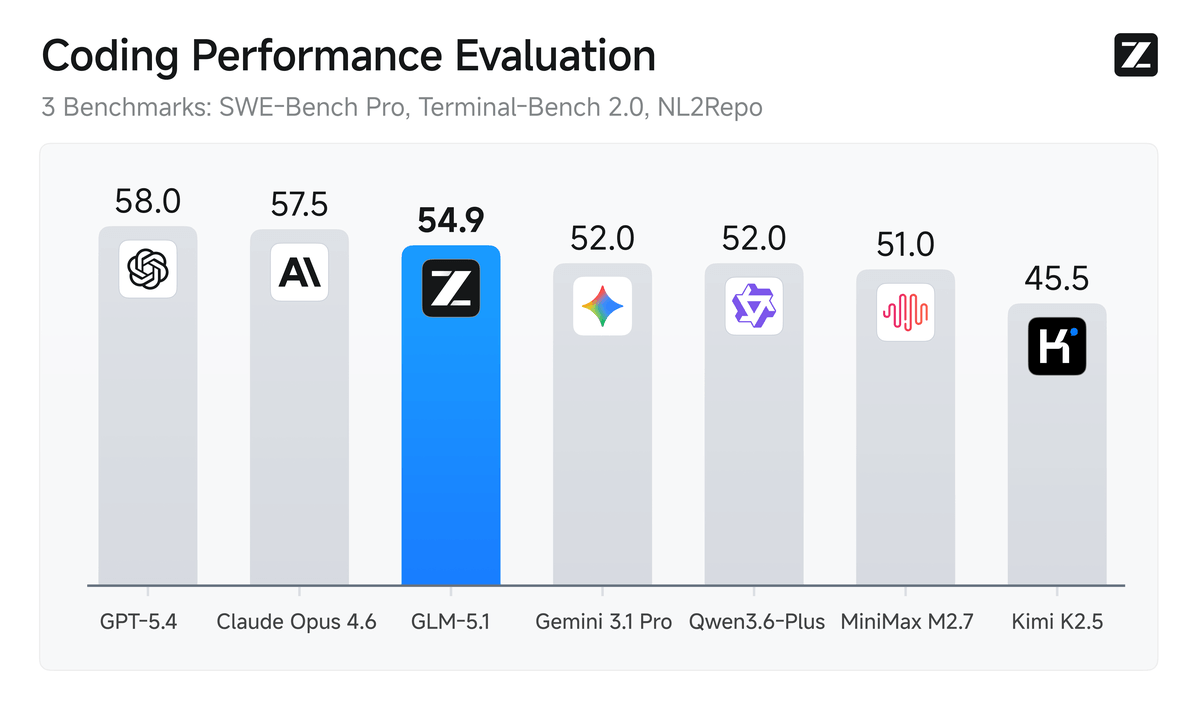
- GLM-5.1 hits state-of-the-art 58.4 on SWE-Bench Pro, beating Claude Opus 4.6 and GPT-5.4
- Architecture: 40B active params, 256 experts, MLA + DeepSeek Sparse Attention, MTP speculative decoding
- 2-bit quant runs on a 256GB Mac Studio or 24GB GPU with 256GB RAM via MoE offloading
- MIT-licensed with 202K context; full deployment guide covers llama.cpp and Unsloth Studio
Z.ai's new flagship coding model just became runnable on hardware you can actually buy. Unsloth has released GLM-5.1-GGUF, a set of Dynamic 2.0 quantizations of the 754B-parameter GLM-5.1 that compress the weights by up to 85% while preserving the model's agentic coding chops. The original checkpoint requires an 8-GPU B200 node to serve at full precision. The 2-bit quant fits on a maxed-out Mac Studio.
The upstream release itself is the interesting story. GLM-5.1 achieves state-of-the-art results on SWE-Bench Pro, sustains autonomous execution for up to 8 hours, and ships as both an open-weight release and an API-accessible service. Unsloth's contribution makes that capability tractable on local hardware without a datacenter.
What's actually in the box
GLM-5.1 is a refresh of GLM-5, not a ground-up rebuild. It keeps the same architecture: 40B active parameters per token, 256 routed experts with top-8 routing plus 1 shared expert, Multi-head Latent Attention combined with DeepSeek Sparse Attention, and a Multi-Token Prediction head for speculative decoding. The MTP head is what lets inference engines like vLLM and SGLang run speculative decoding out of the box.
The scale jump from the previous generation is not trivial. Compared to GLM-4.5, GLM-5 grows from 355B parameters (32B active) to 744B (40B active), and pre-training data expands from 23T to 28.5T tokens. DeepSeek Sparse Attention (DSA) reduces deployment cost while preserving long-context capacity. The context window is 202,752 tokens, with support for up to 128K output tokens for long agent trajectories.