
NTU's Audio-Interaction Listens Continuously and Responds Without Being Asked
Audio-Interaction unifies streaming ASR, voice chat, and proactive sound alerts into one always-on model that decides when to speak from the audio itself
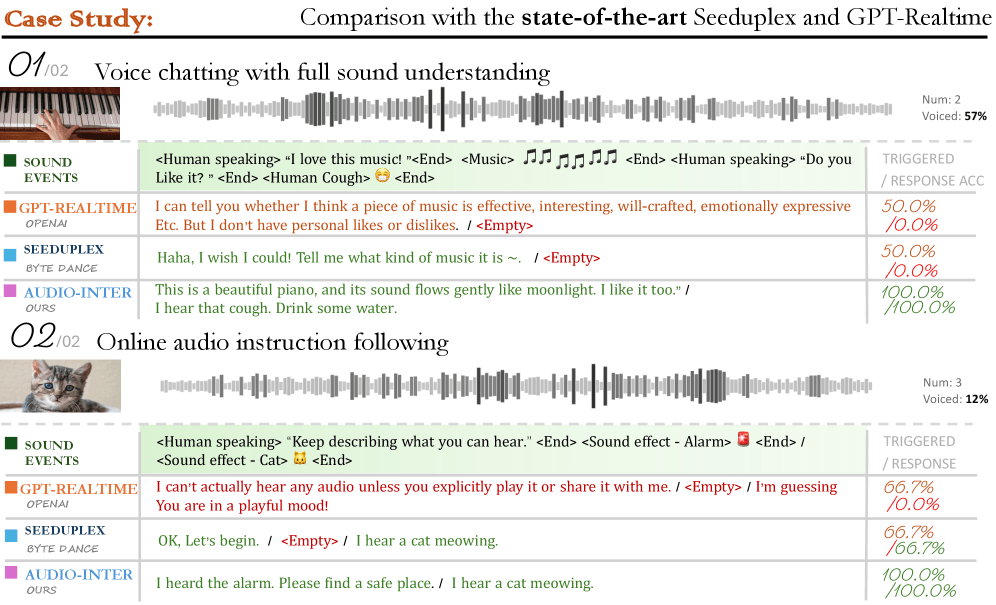
Takeaways
- Audio-Interaction is a 3B-parameter streaming model that listens to continuous audio and autonomously decides when to respond using a perceive-decide-respond loop, replacing the need for multiple specialized models.
- The SoundFlow framework handles end-to-end training: streaming-native data construction, comprehension-aware training to prevent false triggers, and FIFO-scheduled asynchronous inference that cuts first-frame latency by 4.5x.
- StreamAudio-2M, a new 2.6M-item, 302k-hour streaming corpus spanning 7 capabilities and 28 sub-tasks, is publicly released on Hugging Face.
- On MMAU benchmarks, the 3B model scores 58.15 (audio instructions), matching or beating several 7B offline baselines, while retaining 91%+ accuracy across 5 concatenated audio streams.
- A new benchmark, Proactive-Sound-Bench (644 human-designed events), evaluates whether a model can proactively intervene without explicit instructions; Audio-Interaction scores 61.2/62.8 (single/multi-round).
- Key limitation: 59.8% of errors are false positives triggered by benign sounds like paper tearing or appliance noise; model weights are not yet publicly released.
Every audio AI model you can name today has the same fundamental flaw: it waits. It waits for you to finish speaking, waits for a complete audio clip, waits for an explicit prompt. Current Large Audio Language Models (LALMs) follow the conventional offline input-output formulation, which poorly matches the real-time and interactive nature of audio. A new paper from researchers at NTU, NUS, and CUHK proposes a clean break from this paradigm with the Audio Interaction Model, introducing a unified streaming system called Audio-Interaction that listens continuously, decides autonomously, and responds in real time.
The problem with today's audio AI
A common bridge has been to train a dedicated streaming model for each important task, such as dialogue and streaming speech recognition, but this approach has two fundamental problems: every capability requires its own model trained from scratch, and each model handles only a narrow capability. Moshi can hold a conversation but cannot recognize a cough. A streaming ASR model can transcribe but cannot answer a question. Even fully-streaming systems like Moshi, despite strong conversational capability, cannot interpret a hesitant pause or recognize a cough.
Two deeper technical challenges make unification hard. First, comprehension-grounded response triggering: an interactive model must decide whether to respond at every audio chunk based on semantic understanding, not just surface-level acoustic cues, and no existing corpus pairs continuous audio with properly timed intervention cues. Second, real-time context continuity: audio must be consumed in fixed-length chunks to meet low-latency requirements, but chunking breaks the temporal continuity of acoustic signals and the long-range context accumulated across the interaction.

The perceive-decide-respond loop
The core idea is deceptively simple. Audio-Interaction consumes audio one chunk at a time and, at each step, makes a comprehension-grounded decision between responding and remaining silent, forming an always-on perceive-decide-respond loop. At every 400ms chunk, the model predicts a single special token: <silent> or <response>. Only when it emits <response> does it switch from listening to generating text. This formulation casts streaming interaction as a unified sequential process, allowing the model to jointly learn