
Tencent Runs Text Backwards to Fix a Flaw Hiding in Every LLM
Researchers from Institute of Science Tokyo and Tencent show that simply reversing input text before embedding boosts frozen LLM performance by up to 8 points on standard benchmarks
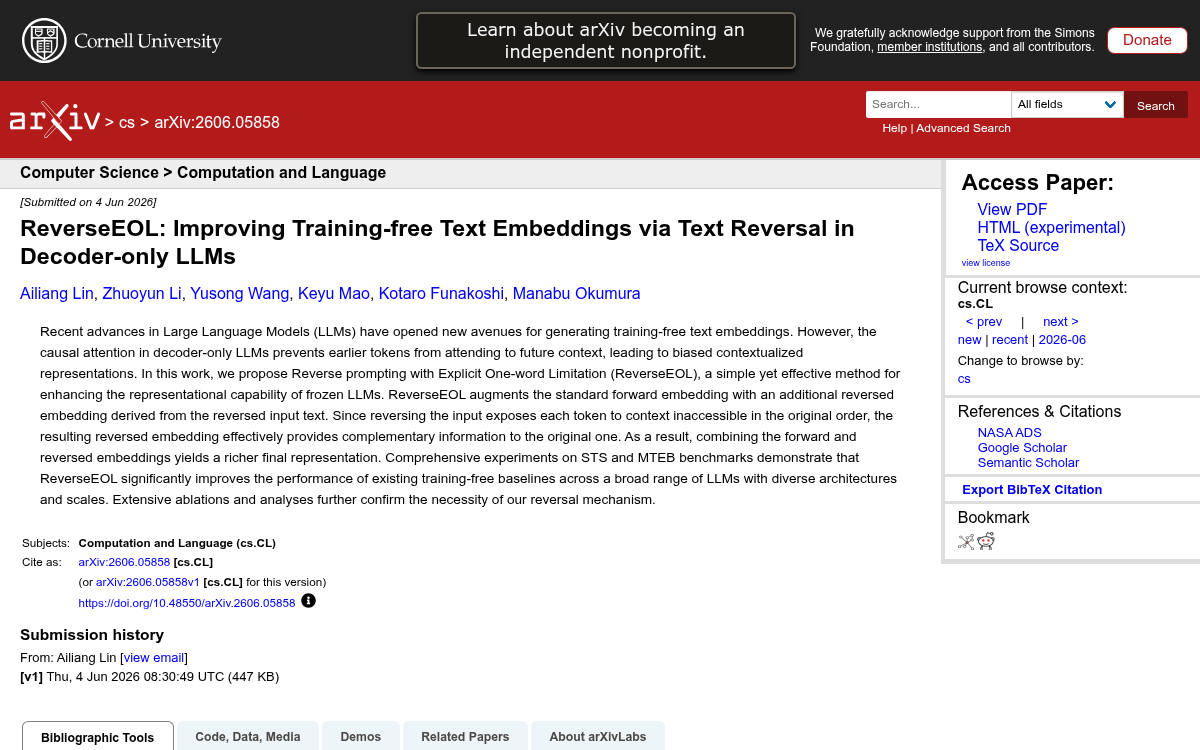
Getting useful text embeddings out of a frozen, off-the-shelf LLM sounds appealing: no fine-tuning, no labeled data, no GPU-hours spent on contrastive training. But there is a structural catch baked into every decoder-only model, and a new paper from researchers at the Institute of Science Tokyo and Tencent proposes a surprisingly elegant fix: just run the text backwards.
The paper, "ReverseEOL: Improving Training-free Text Embeddings via Text Reversal in Decoder-only LLMs"