
Alibaba's Qwen3.6-27B Beats a Model 15x Its Size on Coding
Alibaba's new 27B dense open-weight model beats its own 397B MoE flagship on agentic coding, with Thinking Preservation and hybrid linear attention.
Takeaways
- Alibaba released Qwen3.6-27B, a dense open-weight model under Apache 2.0.
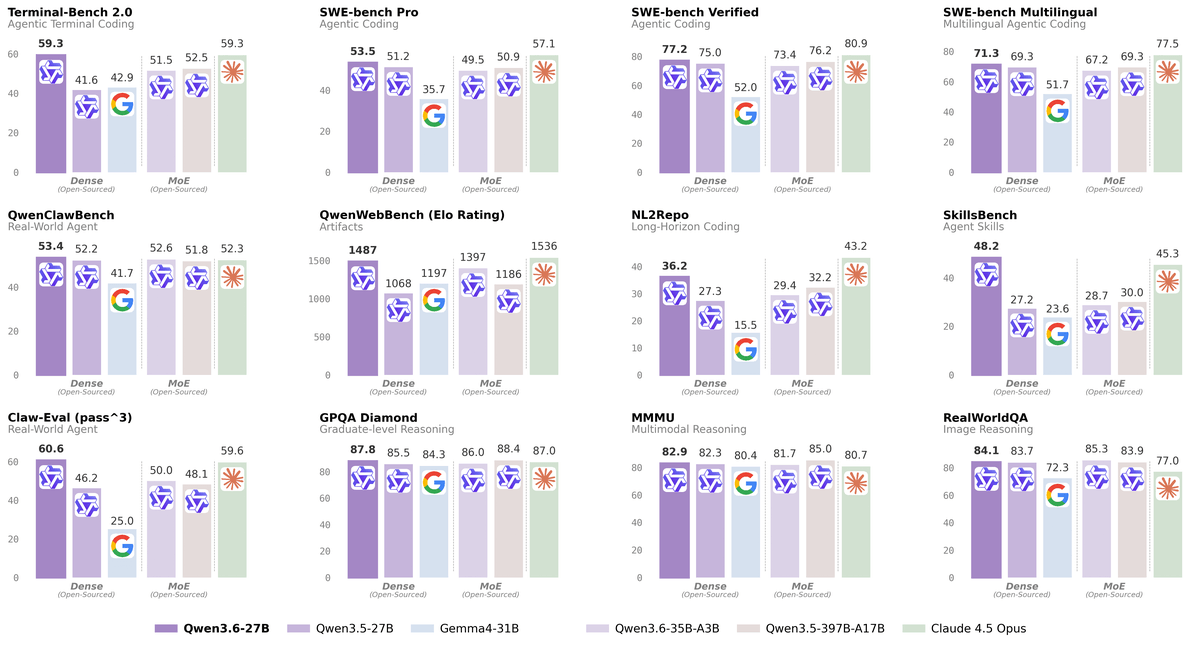
- Beats the 397B Qwen3.5 MoE on SWE-bench Verified (77.2) and Terminal-Bench 2.0 (59.3).
- New Thinking Preservation flag retains reasoning traces across conversation turns.
- Hybrid architecture: three Gated DeltaNet linear-attention sublayers per one full-attention sublayer.
- 262K native context, extensible to 1M tokens via YaRN scaling; multimodal input.
- Runs on a single RTX 5090 at 4-bit; GitHub repo has deployment details.
Alibaba's Qwen team just released Qwen3.6-27B, a dense 27-billion-parameter model that upends the assumption that bigger is always better. It delivers flagship-level agentic coding performance, surpassing the previous-generation open-source flagship Qwen3.5-397B-A17B (397B total, 17B active MoE) across all major coding benchmarks. A model roughly fifteen times smaller than its predecessor is now winning the coding races that matter.
It ships under Apache 2.0, runs on a single high-end GPU, and introduces two ideas worth attention beyond the leaderboard scores: a hybrid attention architecture and a new mechanism called Thinking Preservation.
What actually shipped
Qwen3.6-27B is a dense causal language model with a vision encoder, natively multimodal across text, images, and video. It brings substantial improvements in agentic coding, the Thinking Preservation mechanism, and a hybrid architecture blending Gated DeltaNet linear attention with traditional self-attention.
Headline specs:
- Context length: 262,144 natively, extensible to 1,010,000 tokens via YaRN scaling
- Two weight variants on Hugging Face:
Qwen/Qwen3.6-27Bin BF16 andQwen/Qwen3.6-27B-FP8with fine-grained FP8 quantization (block size 128) - Runs on SGLang, vLLM, KTransformers, and Hugging Face Transformers
- Fits in 16-24 GB VRAM at 4-bit quantization, runs on a single high-end consumer GPU (RTX 5090) or M3 Max/Ultra Mac
- Function calling and structured JSON outputs supported
Grab the weights from Hugging Face or ModelScope, try it interactively on Qwen Studio, or hit it through the Alibaba Cloud Model Studio API. On OpenRouter, Qwen3.6-27B costs $0.30/M input tokens and $2.00/M output tokens, with a separate cache-read rate of $0.03/M tokens, served by seven providers.