
AllenAI Opens the Full Training Stack Behind Tulu 3 to Beat GPT-4o-mini
AllenAI's open-instruct ships a complete post-training pipeline covering SFT, DPO, and RLVR, powering Tulu 3 and OLMo-2 instruction models.
Takeaways
- AllenAI's open-instruct ships a full post-training stack: SFT, DPO, and RLVR in one Apache-2.0 codebase.
- Powers Tulu 3 and OLMo-2 instruct models on Llama 3.1 8B/70B and OLMo-2 7B/13B bases.
- RLVR uses programmatic verifiers (math, code, format) instead of learned reward models for reliable improvements.
grpo_fast.pyuses vLLM plus Ray, splitting training and rollout GPUs to cut hardware needs.- QLoRA support lets you finetune a 70B Llama on a single 80GB A100.
- Tulu 3 reportedly beats Llama 3.1-Instruct, Qwen 2.5, GPT-4o-mini, and Claude 3.5-Haiku on several benchmarks per the Tulu 3 paper.
Most labs publish their base model weights and call the release open. AllenAI has been quietly doing the harder thing: releasing the entire post-training stack that turns a raw pretrained model into something you'd actually want to talk to. Their open-instruct repository is the working codebase behind the Tulu and OLMo instruction models, and it's one of the few places you can study a frontier-quality alignment pipeline end to end.
The full alignment stack in one repo
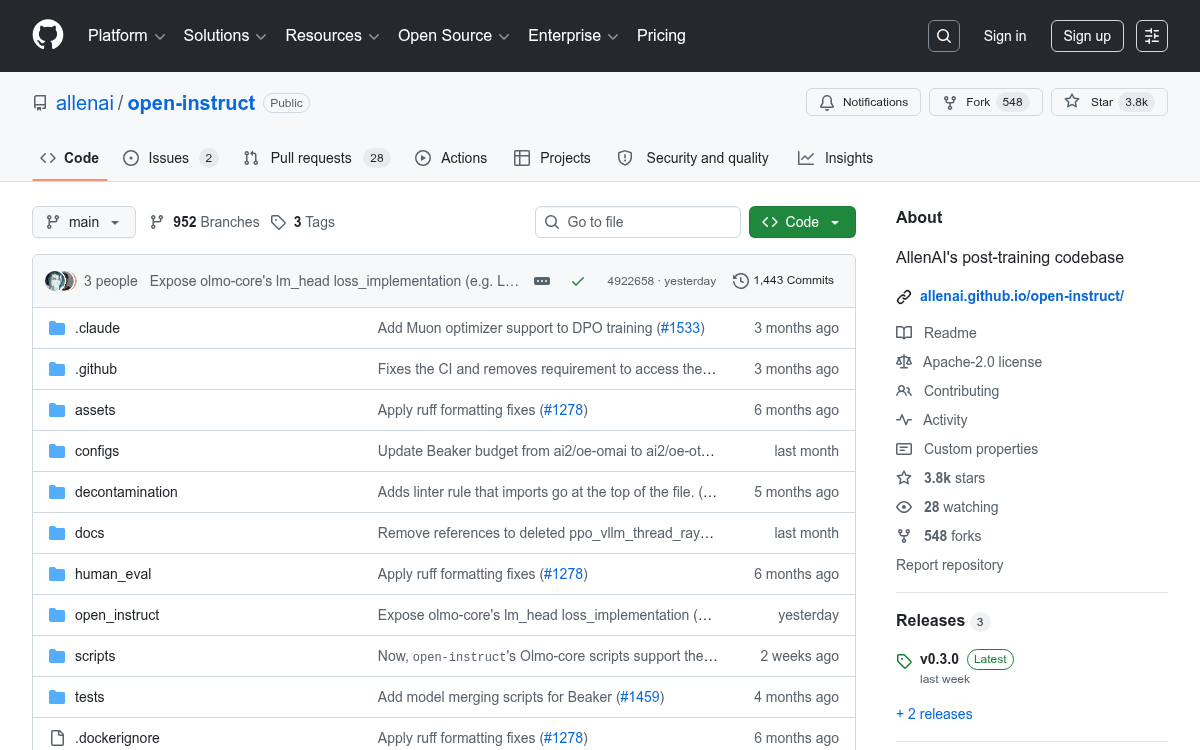
The repo serves as an open effort on instruction-tuning and post-training popular pretrained language models on publicly available datasets. Concretely, it bundles three things that usually live in separate research codebases:
- Code for finetuning language models with latest techniques and instruction datasets in a unified format
- Code for DPO, preference finetuning and reinforcement learning with verifiable rewards (RLVR)
- Checkpoints and other useful artifacts from AllenAI's exploration
RLVR is the piece worth pausing on. Instead of training a reward model to guess what humans like, you use programmatic checks (does the math answer equal the ground truth, does the code pass tests, does the output match a format) as the reward signal. The training methodology incorporates Supervised Fine-tuning, Direct Preference Optimization, and an innovative technique termed Reinforcement Learning with Verifiable Rewards, which ensures reliable and measurable improvements in model behavior.