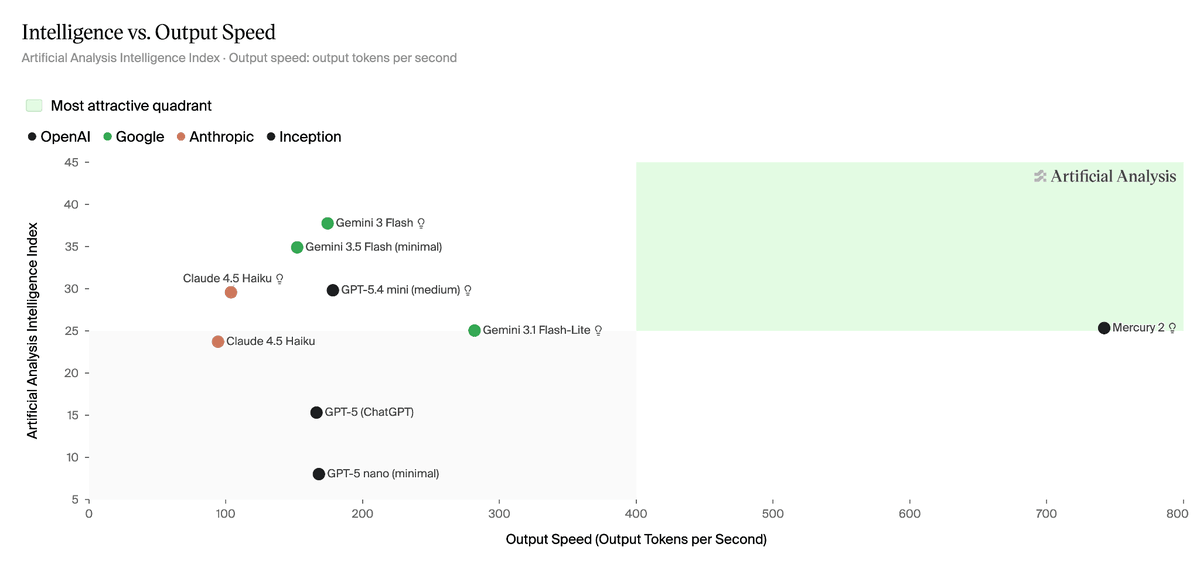
LLM startup competing in the fast-inference space. Inception builds diffusion-based language models (dLLMs) that generate tokens in parallel rather than one at a time, hitting 1,000+ tokens per second on standard NVIDIA GPUs. Its Mercury model family targets coding and reasoning workloads, with an OpenAI-compatible API.
Inception's new diffusion LLM hits 1,068 tokens/sec, beats GPT-6 Luna and Claude Haiku 5.5, and proves scaling laws apply beyond autoregressive models.
Inception's new Mercury Decide is a structured decision model that returns typed answers with calibrated probabilities at 14 decisions per second, free on OpenRouter.
Inception Labs' new diffusion-based model returns its first spoken token in 320ms median, finally fitting a reasoning model inside the 500ms voice budget.
Mercury 2, Inception Labs' diffusion-based LLM hitting 1,000+ tokens/sec, is now available on Azure AI Foundry with enterprise-grade infrastructure and OpenAI-compatible APIs.
Inception is hiring its first Forward Deployed AI Engineer as enterprise demand for Mercury 2 — the world's only production diffusion LLM hitting 1,000+ tokens/sec — outpaces what its research team can handle alone.